Introduction
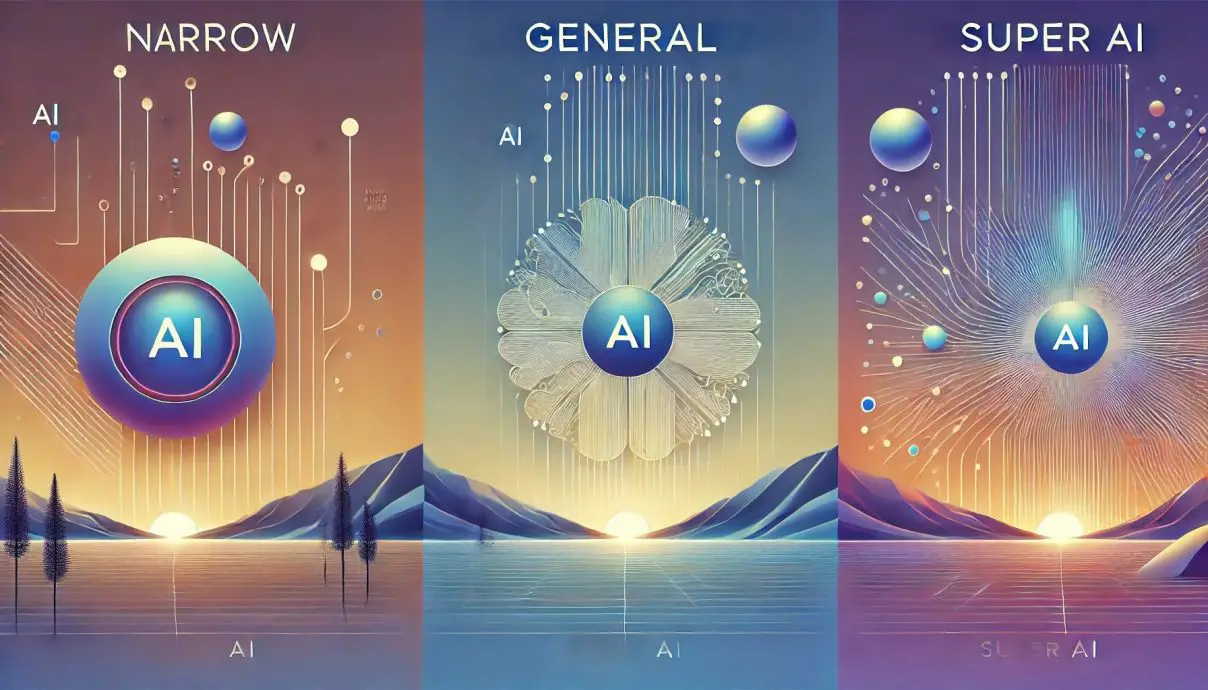
The Types of AI: Narrow, General, and Super AI framework describes a capability ladder that frames every real debate about artificial intelligence today. Every system shipping in 2026 falls into the narrow category, from medical imaging tools to the chatbots that answered your last customer service question. The Stanford HAI AI Index 2025 report ties roughly 252 billion dollars of 2024 private AI investment almost entirely to narrow systems with no general reasoning. General AI could learn a new domain the way a person does. It remains a research goal, as AGI is not here yet argues even for the newest frontier models. Super AI is a hypothetical system that would outperform the best human experts on effectively every cognitive task across science, policy, and daily life. Keeping the three categories clear matters because journalists, vendors, and policymakers routinely collapse them, which turns risk analysis and investment into guesswork. This guide explains what each type is, how researchers measure progress between them, and the honest 2026 picture without the marketing distortion.
Quick Answers on the Three Types of AI
What are the three types of AI based on capability, and which one exists today?
The three types are narrow AI, general AI, and super AI. Narrow AI is the only type that exists in 2026 and runs every production system you use.
What is the main difference between narrow general and super AI?
Narrow AI solves one task well, general AI would match a human across many tasks, and super AI would surpass human experts in every cognitive domain.
How close are we to general or super AI?
General AI remains a research goal with no agreed arrival date. Super AI is a theoretical later stage that is not on any serious engineering roadmap for 2026.
Key Takeaways on Narrow, General, and Super AI
- Narrow AI runs every real system in 2026, from image classifiers to the chatbot drafting your email replies, and it handles exactly one domain at a time.
- General AI would transfer learning across arbitrary new domains without retraining, and no shipped model does this today, despite marketing language suggesting otherwise.
- Super AI is a hypothetical system that would exceed the top human expert in every cognitive task, and it sits outside any current engineering roadmap.
- Confusing the three types is the single most common source of bad AI investment, policy, and risk analysis you will encounter in the coming decade.
Table of contents
- Introduction
- Quick Answers on the Three Types of AI
- Key Takeaways on Narrow, General, and Super AI
- What Is AI Classified by Capability
- Why Capability Classifications Matter More Than Hype Cycles
- The Journey From Rule-Based Systems to Modern Narrow AI
- Types of AI in Daily Life: Narrow AI Examples From 2026
- The Technical Architecture Behind Today’s Narrow AI Systems
- What Artificial General Intelligence Would Actually Require
- Types of AI Research: Implementation Paths Toward General Intelligence
- The AGI Timelines Experts Are Debating This Year
- Artificial Superintelligence as a Hypothetical Capability Horizon
- Risks and Alignment Challenges Across All Three AI Types
- How to Build an AI Governance Framework for Mixed Capability
- Sector Impact: Healthcare, Finance, and Education Under Each AI Type
- Policy and Regulation Shaping Narrow, General, and Super AI
- The Economic Shift From Task Automation to Cognitive Automation
- Ethics Beyond Alignment: Fairness, Autonomy, and Consent
- Comparing Narrow, General, and Super AI Across Seven Dimensions
- Real-World Narrow AI Examples at Scale Today
- Case Studies on Enterprise Narrow AI With Transparent Outcomes
- Key Insights on Narrow, General, and Super AI
- The Future of AI Development Past Narrow Models
- Frequently Asked Questions on Narrow, General, and Super AI
What Is AI Classified by Capability
Types of AI: Narrow, General, and Super AI are the three capability tiers that classify artificial intelligence by scope, where narrow AI handles one task, general AI matches human reasoning across many tasks, and super AI would exceed human experts across every cognitive domain.
An Interactive From AIplusInfo
Which AI Capability Tier Fits Your Use Case?
Pick a task, a desired autonomy level, and the risk you can tolerate. The explorer maps your inputs to narrow, general, or super AI and shows which tier can actually ship it in 2026.
Document review and discovery
Human in the loop
Low
Capability tier required
Narrow AI
Available today. Ships in weeks with standard MLOps.
Realistic 2026 feasibility
High
Hundreds of production narrow AI systems ship this profile weekly.
Oversight burden
Standard
Monitoring, drift detection, incident response, and bias audits suffice.
Mapping draws on Stanford HAI AI Index 2025 adoption benchmarks and the capability definitions from AGI is not here yet.
Why Capability Classifications Matter More Than Hype Cycles
Vendors describe nearly every new model with words like intelligent, autonomous, and general, which blurs the line between a specialized tool and a hypothetical thinking machine. The capability tier a system actually occupies determines how you should buy, deploy, govern, and critique it, so a slip in classification compounds across every downstream decision. A narrow AI vendor who positions a product as early AGI is making a marketing claim, not a technical one. That distinction changes contract language, regulatory exposure, and insurance coverage. The narrow ai vs general ai vs super ai debate also drives public policy, because lawmakers who conflate the three tend to over-regulate the first and under-prepare for the next. Classification is not academic trivia, it is the vocabulary that lets practitioners, buyers, and regulators argue coherently about what a system can and cannot do.
Consider two systems a hospital might buy, both labeled AI assistants in the pitch deck, with very different operational realities underneath. One is a narrow AI model trained to flag suspicious chest X-rays, and it was validated on roughly 100,000 images from the same scanner manufacturer. The other is a general-purpose chatbot the vendor claims can draft discharge notes, triage inbound referrals, and answer billing questions, all from one model. The second product is still narrow AI, because a single large language model that handles several text tasks is a text specialist, not a general reasoner. Treating it as general AI leads a clinical team to trust it on edge cases the training set never covered. That is where safety incidents emerge in the real world.
Classification also shapes risk assessment, because narrow AI, general AI, and super AI pose different failure modes that need different mitigations. Narrow AI failures are usually distribution shift, dataset bias, or adversarial inputs, all handled with better data pipelines and human review. General AI, if it ever ships, would introduce goal misspecification and transfer-learning errors into domains the vendor never anticipated. Super AI failure modes, discussed in AI risk assessment benchmarks, extend to loss of oversight entirely, which is why alignment researchers treat it as a different category of problem. The point is operational: you cannot pick controls without first fixing the capability tier the system belongs to. The Types of AI: Narrow, General, and Super AI framework is what tells you which tier applies.
The Journey From Rule-Based Systems to Modern Narrow AI
Building on that classification, the historical path from early rule systems to today’s narrow AI explains why current models are powerful yet still narrow. The earliest expert systems of the 1970s and 1980s, like MYCIN for infection diagnosis, encoded human knowledge as hundreds of if-then rules a programmer wrote by hand. These systems were narrow by construction because they could only answer questions covered by their rulebooks. Extending them to a new domain meant hiring more experts to write more rules. Machine learning changed the economics by letting systems infer patterns from labeled data, but the trained model still only knew the specific task its labels described. Deep learning extended that pattern to raw images, speech, and text. An image classifier trained on cats and dogs still cannot answer a tax question, no matter how large the model.
The transformer architecture of 2017 widened the scope that one model could cover, which is why large language models feel more general than earlier narrow systems. A single language model can translate, summarize, answer trivia, and write code, and that breadth created the illusion that general AI had arrived. Capability research since then has shown repeatedly that these models are still narrow. They fail at tasks requiring persistent goals, physical world grounding, or novel reasoning outside their training distribution. The AI breakthrough challenges deep learning norms argument reinforces this, noting that benchmark gains have slowed on reasoning-heavy tasks while compute budgets keep growing. The practical takeaway is that modern narrow AI is wider than ever. Width is not depth, and width alone does not cross the Types of AI: Narrow, General, and Super AI line into general intelligence.
Types of AI in Daily Life: Narrow AI Examples From 2026
Shifting focus to lived experience, narrow general and super ai examples become easier to understand when you count the narrow systems a typical person touches each day. The alarm app on your phone uses narrow AI to classify ambient noise, decide if you are awake, and adjust the next snooze cycle, usually without you noticing. Your email client runs several narrow AI models that triage spam, suggest replies, and promote the senders you actually read, each trained on separate labeled datasets. The map app routes your commute using a narrow AI traffic model, a narrow AI estimated-time-of-arrival model. A narrow AI incident classifier, which cooperate but do not share a general understanding of your trip. Even the dishwasher at home may use a narrow AI load sensor to pick a water program, with no awareness that it is a dishwasher at all.
In the workplace the pattern repeats at larger scale, with narrow AI handling specific functions inside almost every category of enterprise software. Customer service platforms route tickets with narrow AI classifiers, summarize prior interactions with narrow AI text models, and suggest next replies through separate narrow AI suggestion engines. Finance teams run narrow AI anomaly detectors on expense reports, narrow AI forecasters on revenue, and narrow AI OCR systems on invoices, each tuned to a specific domain. Human resources teams use narrow AI matchers for resume screening, narrow AI schedulers for interview coordination, and narrow AI tone checkers on performance reviews. None of these is the same model, and that is the operational signature of narrow AI across the enterprise.
Media and entertainment platforms depend heavily on narrow AI recommenders, which drive what you watch, read, and listen to each evening. Netflix, Spotify, YouTube, and TikTok each run specialized narrow AI ranking models trained on billions of user interactions, as described in the AI recommendation systems explained overview. These recommenders are powerful enough to influence political opinion and consumer taste at population scale. The European Commission’s Digital Services Act describes new rules for very large online platforms that force systemic risk assessments of these recommender systems. Narrow does not mean small, and narrow AI at platform scale can shape societies as deeply as any general system might.
Industrial and scientific domains also lean on narrow AI, often invisibly, in ways that would surprise a casual observer who only sees chatbots in the news. Weather prediction centers run narrow AI nowcasting models that Google DeepMind GraphCast extended to global medium-range forecasting with accuracy competitive with the European Centre for Medium-Range Weather Forecasts. Biopharma firms use narrow AI structure predictors like AlphaFold to prioritize protein targets for drug discovery, which has shortened early-stage research timelines. Semiconductor fabs use narrow AI defect detectors on wafers to raise yield and shrink failure rates. Each of these is a narrow AI story even though the applications are frontier science.
The Technical Architecture Behind Today’s Narrow AI Systems
Beyond the user-facing examples, the technical architecture of narrow AI explains why these systems succeed in their lane and stumble outside it. Most production narrow AI systems share a common pipeline: labeled data collection, model training, offline evaluation, deployment, monitoring, and periodic retraining. The data layer dominates the cost structure, because labeling text, images, or events for a specialized task requires human raters whose work must then be audited for consistency. The modeling layer today uses either a transformer backbone or a smaller convolutional or gradient-boosted network, depending on data type and latency budget. The deployment layer wraps the model in an inference service with input validation, output guards, and telemetry so operators can detect drift.
Foundation models have changed how narrow AI is built, but not what it is, because teams now fine-tune or prompt a large pretrained model instead of training from scratch. A customer service team might take an open-weight 70-billion-parameter language model, fine-tune it on 50,000 past tickets, and ship the result as a narrow AI reply assistant for its product. The underlying model has broad linguistic competence, yet the fine-tuned deployment is still narrow because it only serves one domain and one workflow. The reinforcement learning with human feedback technique then tightens the behavior to match the team’s quality bar. Breadth of the backbone and narrowness of the deployment are not in tension, they are the standard pattern.
Model evaluation separates serious narrow AI programs from marketing demos, and the methods are far more rigorous than any chatbot screenshot suggests. Teams build held-out test sets stratified by scenario, measure precision, recall, calibration, and fairness metrics, and track drift against a baseline over months. Adversarial testing probes the model with inputs designed to break it, and the adversarial attacks in machine learning literature catalogs the standard techniques. Narrow AI that passes rigorous evaluation is not weak AI, it is well-scoped AI. Is exactly what makes it safe enough to deploy at scale. The failure modes within the Types of AI: Narrow, General, and Super AI framework almost always trace back to teams skipping or shortcutting this evaluation layer.
What Artificial General Intelligence Would Actually Require
Turning from current practice to the next tier, general AI would require capabilities that no shipping system has demonstrated end to end, despite impressive point advances. A general AI system would need to learn a new domain from a few examples the way a child does, carry goals across weeks of planning. A system would also reason about causes rather than correlations across novel domains. It would also need robust self-knowledge, so it could tell when it did not know something and could explain its own limitations to a user. These capabilities together imply persistent memory, modeling of other agents, and planning horizons measured in months, all of which remain open research problems in 2026.
Benchmarks have been built to measure progress toward general AI, and the results so far suggest the gap is still large even for the best models. The ARC-AGI benchmark from the ARC Prize ARC-AGI benchmark organization tests abstract reasoning on novel visual puzzles. Top frontier models still trail human performance by a wide margin on the hardest tier. The Humanity’s Last Exam benchmark, built by Scale AI and the Center for AI Safety, puts expert-level questions across disciplines in front of models. No current system scores anywhere near a human expert on these cross-disciplinary tests. These benchmarks are not perfect, yet they share a signal that current narrow AI breadth does not add up to depth. General AI is not just a bigger version of what we have today, it is a different research goal inside the Types of AI: Narrow, General, and Super AI ladder.
Types of AI Research: Implementation Paths Toward General Intelligence
Pivoting from the capability gap, researchers are pursuing several concrete pathways that could plausibly close part of the distance to general AI. The scaling pathway continues to make models larger on more data, betting that general capabilities will emerge if enough parameters and tokens are combined. The reasoning pathway explicitly trains models to decompose problems, use tools, and spend more inference compute on hard tasks, which recent OpenAI and Anthropic reasoning models demonstrate. The agent pathway chains language models with memory, planning, and tool use so that a system can carry out multi-step goals in the real or digital world. Each pathway produces different safety concerns, which is why alignment work is tracked in parallel to capability work.
Hybrid architectures combine specialized modules in ways that could, in principle, deliver more general behavior than any one model alone. A planning module can call vision and language subsystems the way a human calls on different cognitive skills, and the orchestration layer tracks progress toward a goal. The mastering agentic AI for smarter workflows deep dive shows how enterprise teams are already stitching narrow components together to approximate agent behavior. These agent systems feel more general to a user, yet their architecture is still a stack of narrow components with an orchestrator. Is why their failure modes resemble narrow AI failures rather than general reasoning errors. Watching how agents behave this year is one of the clearest ways to see where the boundary of narrow currently lies.
Neuroscience-inspired approaches also play a role, with research groups studying how biological brains build world models, use sparse activations, and recover from damage. Some of this work feeds back into deep learning as new architectures, and some of it informs long-horizon theories about what cognition really is. The Anthropic’s safety-first approach emphasizes interpretability as a route to understanding what frontier models actually represent inside their weights. Progress on interpretability is uneven, yet every advance makes it easier to tell whether a model is truly reasoning or just pattern-matching. The pathway toward general AI is not a single highway, it is a bundle of roads, and only some will prove to be the real route.
The AGI Timelines Experts Are Debating This Year
Building on current research pathways, the AGI timeline debate in 2026 has sharpened as frontier labs publish more specific capability claims and research agendas. OpenAI leadership has publicly described reasoning-model progress toward AGI, while Anthropic has emphasized interpretability as a precondition before deploying any system with general-reasoning features. DeepMind’s roadmap for Gemini and successor models frames general capability as a product of better planning, grounding, and multimodal integration rather than one more scaling run. Independent forecasters at Metaculus and the AI Impacts 2023 expert survey project have shortened their median AGI estimates several times since 2022. These shifts matter because they shape investment, hiring, and policy conversations well beyond the labs themselves.
Timelines remain contested because the definition of general AI is itself contested, and small changes to the operational test move the forecast by years. If AGI means a system that matches human experts on standard knowledge benchmarks, several current models are already partway there, and some researchers would call the finish line close. If it means a system that can be dropped into any new job with no retraining, no model in production comes close, and the timeline opens up considerably. If it means a system that explains its reasoning in a way a human can verify, interpretability research has not yet caught up to the capability of the frontier models. Each definition produces a different number, and the public debate often conflates them without saying which test is being measured.
Expert surveys show the range of credible forecasts rather than a single answer, which is useful information for buyers and policymakers who need to plan under uncertainty. The 2024 Expert Survey on Progress in AI, run by AI Impacts, found a median high-level machine intelligence estimate near 2047, down from 2060 in the 2022 edition. Shorter forecasts come from inside major labs, with some researchers suggesting usable general reasoning within a decade. Longer forecasts come from academics who emphasize how many open research problems remain and how slowly transfer-learning benchmarks move. The honest reading is that smart people who look closely at the data disagree by decades, and planning should respect that spread rather than pretend a single date exists.
Policy and investment decisions depend less on exact dates and more on the shape of the transition, especially the pace between leading and trailing systems. If AGI arrives slowly, with many incremental releases, regulators have time to iterate on rules and firms have time to retool workflows. If AGI arrives suddenly from one lab, concentration risk and governance gaps become immediate problems that current institutions are not designed to handle. Buyers can reduce exposure by writing contracts that assume ongoing capability change, with model-version tracking and renegotiation triggers tied to capability milestones. The timeline debate across the Types of AI: Narrow, General, and Super AI ladder is the shared uncertainty that every realistic AI strategy has to price in.
Artificial Superintelligence as a Hypothetical Capability Horizon
Looking past general AI, super AI examples are necessarily hypothetical because no system of that capability has been built or convincingly demonstrated. Superintelligence, in the usage set by Nick Bostrom and still common in alignment research, refers to a system that outperforms the best human experts on effectively every cognitive task. Candidate pathways include a general AI that recursively improves its own training process, a dramatic breakthrough in neuroscience-inspired architectures, or an unknown advance that current researchers have not identified. Each pathway raises its own evidence and safety questions, which is why no one path can yet be ranked above the others. None of these pathways is currently well-enough understood to assign a probability or a timeline with confidence. Treating super AI as inevitable or impossible both overstate what we know, and good analysis keeps the question open.
The policy question about super AI is less about if and more about preparedness, because the costs of being wrong are asymmetric. Preparing for a capability transition that never arrives wastes effort, while being unprepared for one that does arrive could create outcomes that no later remediation can fix. International bodies, including the UK AI Safety Institute, the US AI Safety Institute. The UN High-Level Advisory Body on AI, have begun producing guidance aimed at both the current narrow systems and plausible future general ones. Super AI planning sits inside the broader three-tier capability framework. It is best treated as insurance against a low-probability high-impact event, not as a near-future prediction.
Risks and Alignment Challenges Across All Three AI Types
Pivoting from capability to safety, each type of AI carries a different risk profile that calls for a different response from engineers, operators, and regulators. Narrow AI risks are already material and include dataset bias, distributional drift, adversarial attacks, privacy leakage, and over-automation of decisions that need human judgment. These risks are tractable with the standard controls of data quality, evaluation, monitoring, incident response, and the governance patterns described in AI governance trends and regulations. The challenge is not that we lack mitigations, it is that many deployments ship without applying them. Most AI incidents in production today trace back to that gap between known controls and actual rollout practice.
General AI, if it ever arrives, would introduce goal misspecification and transfer errors that current narrow-AI mitigations do not fully address. A system that can carry a plan across weeks could pursue a stated goal in ways the designers never intended. The real-world consequences of general action are hard to anticipate. Interpretability research tries to close this gap by making the internals of frontier models legible, so operators can catch concerning behavior before deployment. Red-teaming, structured capability evaluations, and staged release protocols add complementary layers to that defense. These controls look overbuilt for current narrow AI, yet they are being developed now because retrofitting them to a more general system under time pressure would be far harder. Starting early also builds the practitioner skill base that any future transition would depend on.
Super AI risks occupy a separate category because loss of meaningful human oversight is the central concern rather than any specific failure mode. The alignment literature frames this as the challenge of specifying what we want precisely enough. A vastly more capable system cannot be allowed to optimize to the letter while betraying the spirit of a goal. Pursuing this problem now, well before any such system exists, lets researchers test ideas on current models where mistakes are affordable. Constitutional AI, scalable oversight, and corrigibility are three such approaches that current labs study together. Risk work across all three capability tiers is naturally cumulative over time and investment. The methods that make narrow AI safer today are the foundations of whatever makes general and super AI governable later.
How to Build an AI Governance Framework for Mixed Capability
Building on that risk framing, operational governance in 2026 covers a portfolio of narrow AI systems. The program leaves room for more capable models to arrive without a full rewrite. A workable framework starts with a model inventory that lists every deployed system, its vendor, its training data provenance, and the business decisions it affects. Each entry carries a capability-tier label, so narrow AI chatbots are not governed the same way as an experimental agentic system that calls external tools. The framework then assigns a human owner, a monitoring plan, and a review cadence tied to the risk tier. Is the same pattern financial controls teams have used for decades.
Technical controls make the policy workable in practice, which is what separates a serious governance program from a slide deck. Access controls restrict which users can call which models with which data, so a general-purpose chatbot cannot quietly become a de facto approval authority. Logging captures prompts, outputs, decisions, and overrides, which later feeds incident response, bias audits, and regulator inquiries. Evaluation harnesses re-test deployed models against fresh scenarios on a monthly or quarterly basis, so drift is detected before it reaches users. AI ethics and laws describes how these controls increasingly align with emerging regulatory expectations in the EU and elsewhere.
People and process close the loop, because tools alone do not create accountability or learning from near misses. Clear escalation paths let frontline users flag concerning model behavior to a review board that can pause or roll back a deployment within hours. Independent red teams probe production systems for exploitable failures, with findings fed back to engineering within a documented service-level agreement. Training programs raise literacy across business, legal, and operational teams, so that the three types of AI become shared vocabulary rather than specialist jargon. Governance built around these three capability tiers scales naturally with capability. Today’s work on narrow AI is the starting line for governing the general systems that may follow.
Sector Impact: Healthcare, Finance, and Education Under Each AI Type
Shifting focus to industry effects, each type of AI changes healthcare, finance, and education differently, which is why generic AI adoption statistics often mislead. Healthcare in 2026 is dominated by narrow AI, with imaging triage, administrative automation. Documentation assistance driving most of the measured productivity gains, as detailed in AI in medical imaging diagnosis. General AI could, in principle, synthesize novel treatment plans across specialties, but current regulatory frameworks have no path to approve such a system without extensive validation. Super AI applications in healthcare are purely speculative, which is why serious investment follows the narrow use cases that can meet existing clinical validation standards.
Finance and education show related but distinct patterns, with narrow AI driving most measurable value today and more general systems arriving as pilots rather than production. Banks use narrow AI for fraud detection, anti-money-laundering screening, and credit scoring, each system audited for fairness and explainability before deployment. Education platforms use narrow AI for adaptive practice, essay scoring, and plagiarism detection, with teachers still responsible for the pedagogical judgment. More general tutoring agents are in trial but have not yet convinced skeptical districts that their failure modes are acceptable at classroom scale. The right mental model is a staircase, with narrow AI handling the current step while general AI capability is tested one grade or one treatment pathway at a time.
Policy and Regulation Shaping Narrow, General, and Super AI
Beyond individual sectors, policy and regulation are reshaping how all three tiers of AI are built, bought, and deployed, with Europe setting most of the pace. The EU AI Act Article 113 entry-into-application timeline entered application in phases, with general-purpose AI model obligations starting on 2 August 2025 and the broader enforcement regime maturing through 2026. The Act classifies AI systems by risk rather than by capability tier. Means a narrow AI used in a high-risk setting carries heavier obligations than a general-purpose model used in a low-risk one. This design forces vendors to document data governance, risk management, logging, human oversight, and post-market monitoring in ways most narrow AI deployments were never built for.
The United States has pursued a different pattern, with executive action, sectoral regulation, and voluntary commitments operating alongside state-level AI laws. The National Institute of Standards and Technology’s AI Risk Management Framework provides a widely adopted structure for narrow AI programs. Large frontier labs have signed voluntary safety commitments covering reporting and red-teaming. Several US states, including California and Colorado, have passed AI-specific statutes that regulate narrow AI deployments in employment, insurance, and other covered sectors. The patchwork creates compliance complexity but also lets jurisdictions learn from each other, which is useful while the technology is still moving. Vendors who track both federal and state frameworks are best positioned to ship across jurisdictions without rework.
International coordination is still catching up with capability, yet several forums have begun producing shared guidance that could matter for general and super AI as those arrive. The UK AI Safety Institute, the US AI Safety Institute, and the EU AI Office have signed memoranda of understanding on frontier model evaluation and incident sharing. The G7 Hiroshima AI Process, the OECD AI Principles, and the UN High-Level Advisory Body all contribute reference points that national regulators can pull from. These efforts matter because capability tiers do not respect borders, and a general AI system released in one country affects every market where it is used. Watching how international coordination evolves is one of the clearest early signals about how prepared the world will be for whatever comes next.
The Economic Shift From Task Automation to Cognitive Automation
Turning to economic impact, the shift from narrow AI task automation to broader cognitive automation is reshaping how firms organize work and how workers plan careers. Narrow AI historically automated discrete tasks, so a knowledge worker whose role contained many such tasks saw productivity gains without losing the job itself. General AI, if it arrives, could automate bundles of related tasks that currently require coordination across people, which changes the economics of entire roles rather than individual activities. A credit analyst, a paralegal, and a radiology technician have different automation profiles under narrow AI than they would under a general reasoner. Employers need both views to plan workforce strategy across the three AI capability tiers.
Macroeconomic forecasts about AI already diverge by orders of magnitude, with some estimating single-digit percent productivity gains and others projecting economy-wide transformation within a decade. The spread reflects underlying uncertainty about which capability tier will dominate deployment during the forecast window, not just differences in modeling assumptions. The AI vs humans, who’s smarter now comparison provides useful texture for how to read these forecasts without being swept up in the extremes. Workforce planning that assumes capability stays near today’s narrow AI will understate risk if general AI arrives, and planning that assumes general AI arrives soon will overstate near-term disruption. Prudent organizations plan for a spread rather than a single scenario.
Labor market data suggest that AI exposure correlates with wage growth rather than wage decline for workers who adopt the tools early, at least in the narrow AI era. Studies from the Bureau of Labor Statistics and private researchers show that complementarity effects, where AI augments rather than replaces human judgment, still outweigh substitution in most roles. The pattern may change as more capable systems ship, which is why worker training and transition support need to scale alongside the technology. Educational institutions and employers who treat AI literacy as a core competency, rather than a specialist concern, position their people best for a transition whose exact timing nobody can predict. The economic story is a race between automation of specific tasks and creation of new roles that use the tools well.
Ethics Beyond Alignment: Fairness, Autonomy, and Consent
Looking past alignment, the ethics of narrow general and super AI extend into fairness, autonomy, and consent in ways that touch every current deployment. Fairness in narrow AI means that models do not systematically disadvantage protected groups. Requires auditing training data, deployment outcomes, and remediation pathways with the attention paid to credit and employment law. Autonomy covers both human autonomy, protected by informed consent to automated decisions, and the agency of AI systems themselves as they take on more complex tasks. Consent means that users understand when they are interacting with an AI, what data the system collects. What recourse they have when things go wrong, as covered in AI ethics and your future path.
These ethics shift as capability grows, because a narrow AI that recommends a movie poses a very different consent question than a general AI that negotiates on a user’s behalf. The AI that replicates personality in 2 hours research shows how quickly personal data can be captured and used to approximate a person, raising novel autonomy questions. Super AI, if it ever existed, would raise questions about moral status that current law does not even frame coherently. Working through these three-tier ethics now builds the muscles society will need. More capable systems may arrive while narrow AI is still the only tier in production. The right time to draft an ethics framework is before the system that stresses it is deployed, not after.
Comparing Narrow, General, and Super AI Across Seven Dimensions
Beyond the narrative, a side-by-side comparison across seven dimensions makes the capability tiers concrete for buyers, operators, and regulators. Each dimension picks up a different operational concern that comes with purchasing or auditing an AI system today. Scope and learning transfer govern what the system can do out of the box, and autonomy decides who holds the next decision. Oversight needs, failure modes, and deployment surface shape the controls and the risk register the operator must maintain. Societal reach captures the second-order effect: how far the system’s outputs ripple into customers, workers, and the public. The table below maps scope, learning, autonomy, oversight, failure modes, deployment surface, and societal reach for the Types of AI: Narrow, General, and Super AI tiers.
| Dimension | Narrow AI (ANI) | General AI (AGI) | Super AI (ASI) |
|---|---|---|---|
| Scope of task | Single task or narrow domain, well-defined inputs and outputs | Broad cross-domain learning, transfers skills to new tasks like a human | Exceeds top human experts on effectively every cognitive task |
| Learning transfer | Poor transfer, needs new labeled data for each new task | Few-shot or zero-shot transfer across domains | Rapid, open-ended learning and self-improvement |
| Autonomy | Low, each decision is scoped by a product team | Moderate to high, carries goals across multi-step plans | Theoretically full, could set and pursue its own goals |
| Oversight needs | Monitoring, drift detection, incident response | Scalable oversight, interpretability, red-teaming | Fundamental alignment problem not yet solved |
| Failure modes | Bias, drift, adversarial inputs, hallucination inside the lane | Goal misspecification, deception, novel-domain errors | Loss of meaningful human oversight entirely |
| Deployment surface in 2026 | Everywhere: inboxes, hospitals, factories, banks, schools | Research prototypes and early agent trials, not production | None, hypothetical capability horizon |
| Societal reach | Already shapes commerce, media, health, and public services | Would reshape labor markets, education, and governance | Would redefine what counts as a human-decidable question |
Real-World Narrow AI Examples at Scale Today
Beyond frameworks, the clearest proof of narrow AI value sits in production deployments at household names like JPMorgan, Walmart, and DeepMind. Each example maps to a different domain: financial contract review, retail supply chain forecasting, and structural biology. Together they cover knowledge work, operational analytics, and frontier scientific research. Readers who want a pattern language for narrow AI deployment should treat these three as templates. The common thread is that every one of them picks one task and does it well. Each example shipped measurable business outcomes using narrow AI, not general reasoning, which is why the Types of AI: Narrow, General, and Super AI distinction matters at purchase time.
JPMorgan Chase COIN for Contract Review
JPMorgan Chase deployed its Contract Intelligence platform, COIN, to parse commercial loan agreements. The system replaced roughly 360,000 lawyer and loan-officer hours a year, as the ABA Journal reported on the COIN rollout. The system is a narrow AI that extracts clauses, parties, and dates from standardized agreements and surfaces them for human review in seconds rather than hours. Measured outcomes include the reclaimed 360,000 hours and a measurable drop in review errors on the specific contract types the model was trained to parse. The limitation is that COIN only handles the standardized loan documents in its training distribution, so novel contract structures still require full human review. The deployment is a textbook example of narrow AI delivering real enterprise value by picking one task and doing it well without pretending to be more.
Walmart Narrow AI for Inventory Forecasting
Walmart has rolled out narrow AI forecasting across its US supply chain. The system predicts demand for roughly 500 million item-store combinations each day, as Walmart’s generative AI tools announcement details. The system is a specialized model trained on historical sales, promotions, weather, local events, and holidays. It feeds replenishment decisions that keep shelves stocked without overstocking. Measurable outcomes include lower stockout rates, improved on-shelf availability during storm events, and reduced write-down of perishable goods. The limitation is that the model still underperforms during truly novel disruptions, which is why human category managers remain in the loop to override during unusual events. Walmart’s deployment shows how narrow AI at hyperscale can shape consumer experience without ever being general or super.
DeepMind AlphaFold for Protein Structure Prediction
DeepMind’s AlphaFold is a narrow AI that predicts the three-dimensional structure of proteins from amino acid sequences. The project has now released over 200 million predicted structures through the AlphaFold Protein Structure Database download portal. The system is purpose-built for structural biology and does not translate text, drive cars, or answer trivia. Is why it is clearly narrow AI despite its revolutionary impact on biology. Measurable outcomes include documented acceleration of structural biology research timelines from months to minutes and adoption by over two million researchers worldwide. The limitation is that structure prediction alone does not solve drug discovery, which requires integrating many additional narrow AI models for binding, pharmacokinetics, and toxicology. AlphaFold is proof that narrow AI, when it fits a well-posed scientific question, can unlock discovery on a scale general AI has not yet matched.
Books that go deeper on the three types of AI
Hand-picked titles that unpack narrow, general, and super intelligence with substance.

Superintelligence: Paths, Dangers, Strategies
Nick Bostrom’s framework for ASI risk is the reference text behind most super AI discussions you will encounter today.
Buy on Amazon
Human Compatible: AI and the Problem of Control
Stuart Russell explains why alignment matters now and how the three capability types map to different control problems.
Buy on Amazon
Artificial Intelligence: A Modern Approach
The standard university textbook that defines narrow, general, and super AI the way most researchers still use the terms.
Buy on AmazonAs an Amazon Associate, AIplusInfo earns from qualifying purchases.