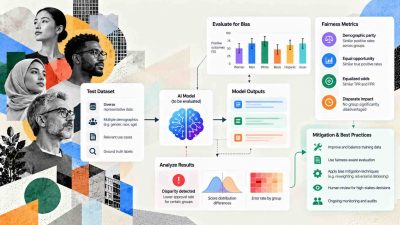
AI Bias Audits: How to Test Models for Fairness
Why it matters: Learn how to run an AI bias audit with the right fairness metrics, runnable Fairlearn code, and legal checklists. Catch model gaps before regulators do.
Everything AI, Robotics, and IoT
Sanksshep Mahendra is a technology executive with success in driving, vision, strategy, design, and execution of software engineering for the web, mobile, apps, social, voice, IoT, applications along with Machine learning and AI. His expertise lies in partnering with business leaders, powering through roadblocks, and leading global teams to deliver disruptive products that advance the organization’s mission and capture game-changing results in the market. Sanksshep Mahendra has a lot of experience in M&A and compliance, he holds a Master's degree from Pratt Institute and executive education from Massachusetts Institute of Technology, in AI, Robotics, and Automation.
Why it matters: Learn how to run an AI bias audit with the right fairness metrics, runnable Fairlearn code, and legal checklists. Catch model gaps before regulators do.
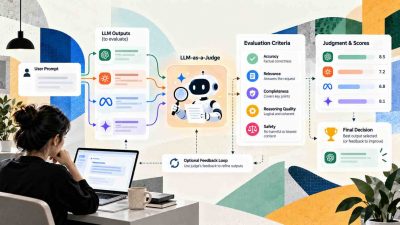
Why it matters: How to evaluate LLM outputs with LLM-as-a-judge: build a rubric, fix judge bias, and prove it against human labels in eight tested steps.
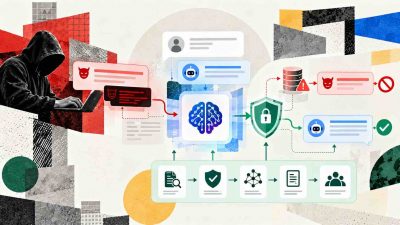
Why it matters: Prompt injection attacks explained and how to defend against them: real incidents, measured results, and a 7-step layered plan with working code.
Why it matters: Learn how to build a RAG chatbot with open source tools: nine tested steps, working Python code, and an evaluation loop that stops hallucinations.
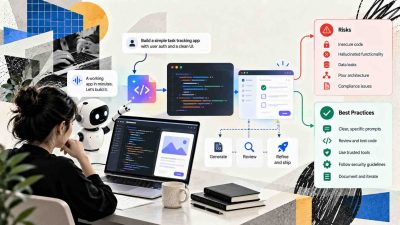
Why it matters: Vibe coding explained: the security flaws, hallucinated packages and agent mishaps behind the hype, plus the best practices that keep AI-generated code safe.
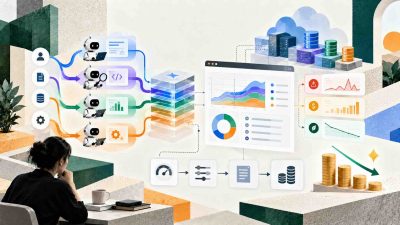
Why it matters: Cut surprise AI bills: FinOps for agentic AI covers token budgets, cost per resolved task, attribution, showback, and guardrails for autonomous agents.
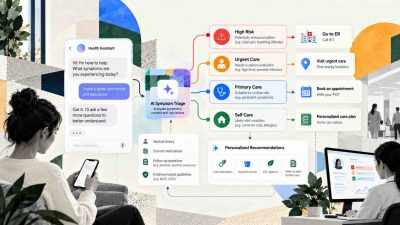
Why it matters: AI symptom triage systems missed over 40% of emergencies in a 2022 retest. See what BMJ, Nature Medicine, the FDA, and WHO say before you trust one.
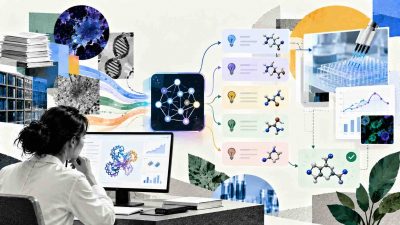
Why it matters: AI for scientific hypothesis generation has lab-proven wins and costly failures. See how it works, where it breaks, and a workflow to try.
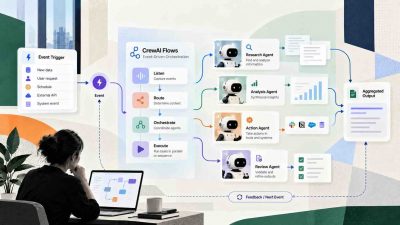
Why it matters: CrewAI Flows explained: how start, listen and router decorators turn improvising agents into deterministic, resumable workflows you can actually audit.
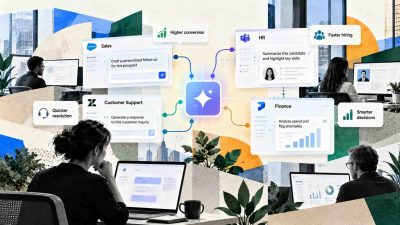
Why it matters: Embedded AI is already inside your CRM and ERP: see what changes for governance, cost, and daily work before your next vendor renewal.