How to Build a Prompt Library for Your Team
Why it matters: Learn how to build a prompt library for your team with templates, testing, versioning, and governance. Includes working code, a seven-step plan, real cases.
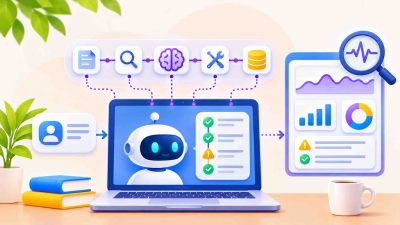
What Is AI Observability and Tracing for LLM Applications
Why it matters: Your LLM app can return a clean 200 and still be wrong. Learn how AI observability and tracing expose bad answers, runaway costs, and silent failures.
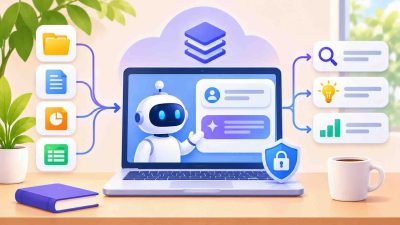
How to Build an Internal AI Assistant Over Company Documents
Why it matters: Stop answering the same questions twice. Learn how to build an internal AI assistant over company documents, with code, permissions, and case studies.
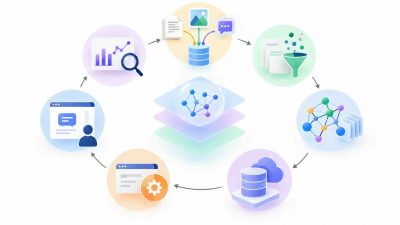
Context Development Lifecycle
Why it matters: Stop shipping untested prompts. Learn the context development lifecycle: generate, evaluate, distribute, and observe agent context, backed by real test data.
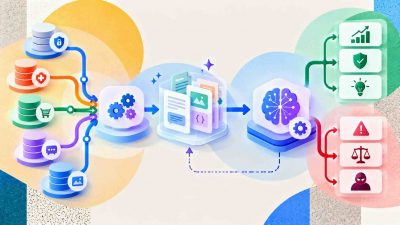
LLM Hallucination Detection Techniques
Why it matters: Which LLM hallucination detection techniques really work? Compare semantic entropy, SelfCheckGPT and groundedness checks, then try our free detector estimator.
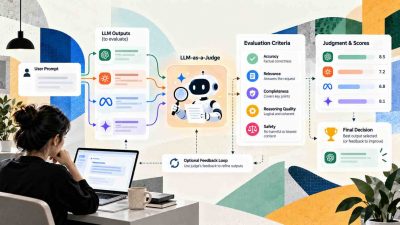
How to Evaluate LLM Outputs With LLM-as-a-Judge
Why it matters: How to evaluate LLM outputs with LLM-as-a-judge: build a rubric, fix judge bias, and prove it against human labels in eight tested steps.
Pydantic AI vs LlamaIndex Workflows for Production Agents
Why it matters: Pydantic AI or LlamaIndex Workflows? Compare durability, human approval, evals and real customer results before you commit your production agents.
