Introduction
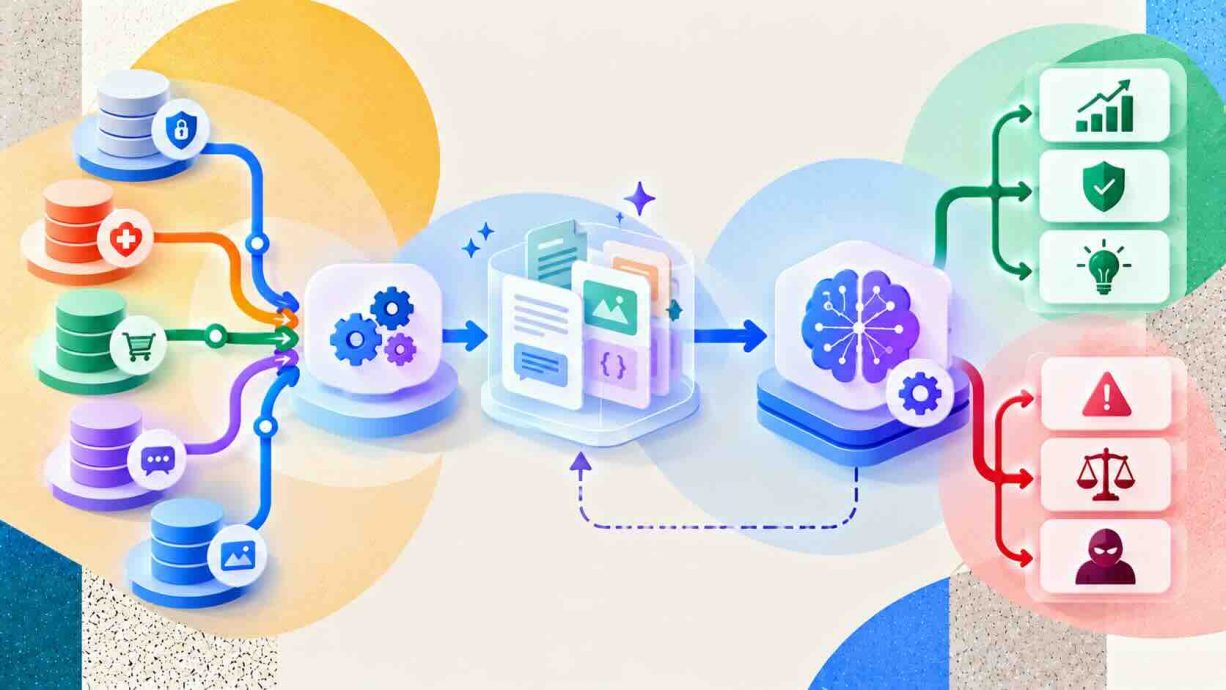
LLM hallucination detection techniques give engineering teams a way to decide whether a fluent answer deserves trust or a second look. Fluency is the core difficulty, because a fabricated citation reads exactly like a real one. The Vectara hallucination leaderboard, last updated in May 2026, reports summarization hallucination rates from 1.8% for the best model to 24.2% for the weakest. That spread proves that model choice matters, yet even the best score leaves a residual error rate that cannot be ignored at production scale. Our earlier ranking of AI models with minimal hallucination rates covered which models err least. This guide covers the next question, which is how to catch the errors that remain. You will learn how consistency checks, semantic entropy, probing, claim verification, groundedness scoring, and trained judges work, where each one breaks, and how to combine them. By the end you will have a layered design, a cost model, and a realistic view of what detection can promise.
Quick Answers on LLM Hallucination Detection Techniques
What are LLM hallucination detection techniques?
LLM hallucination detection techniques are methods that flag likely false or unsupported statements in model output, using sampling consistency, uncertainty estimates, internal probes, evidence checks, or trained judge models.
Which LLM hallucination detection technique works best?
No single technique wins. Semantic entropy averaged 0.79 AUROC in a Nature study, groundedness checks suit retrieval systems, and layered LLM hallucination detection techniques outperform any lone detector.
Can detection eliminate hallucinations?
No. Detection reduces exposure by flagging risky answers, but consistent errors slip past sampling-based detectors, so LLM hallucination detection techniques need retrieval, thresholds, and human review behind them.
Key Takeaways
- Detection works in four families: consistency across samples, uncertainty and internal signals, evidence-based verification, and trained or prompted judges.
- Semantic entropy reached an average AUROC of 0.79 across 30 task and model combinations, beating three common baselines.
- Retrieval-augmented systems need groundedness checks against the retrieved text, because a model can contradict its own sources.
- Every detector has blind spots, so layered LLM hallucination detection techniques with human escalation protect users better than any single score.
Table of contents
- Introduction
- Quick Answers on LLM Hallucination Detection Techniques
- Key Takeaways
- What Is LLM Hallucination Detection and Why It Takes Several Techniques
- Why Language Models Hallucinate in the First Place
- A Working Taxonomy of Hallucinations Worth Catching
- How the Main Families of LLM Hallucination Detection Techniques Compare
- Consistency Checks with SelfCheckGPT and Repeated Sampling
- Semantic Entropy and Uncertainty Estimation
- Reading the Model’s Own Hidden States with Probes
- Verifying Claims Against Evidence with Atomic Fact Checking
- Groundedness and Faithfulness Scoring for RAG Systems
- Trained Detectors and LLM Judges
- Benchmarks and Metrics That Show Whether Detection Works
- Putting LLM Hallucination Detection Techniques Into a Production Pipeline
- Thresholds, Latency, and Cost Budgets
- Where Detection Falls Short: Risks and Blind Spots
- Ethics, Accountability, and Human Oversight
- The Future of LLM Hallucination Detection Techniques
- Key Insights on Detecting LLM Hallucinations
- Side-by-Side Comparison of Detection Approaches
- Real-World Examples of Hallucination Detection in Practice
- Lessons From Case Studies of Hallucinations in the Wild
- Frequently Asked Questions on Detecting LLM Hallucinations
What Is LLM Hallucination Detection and Why It Takes Several Techniques
LLM hallucination detection techniques are methods that score or flag model statements that are false, fabricated, or unsupported by source material, using sampling consistency, uncertainty, internal signals, evidence verification, or trained judges.
An Interactive From AIplusInfo
How Many Hallucinations Would Your Detector Catch?
Pick a detection technique and describe your traffic to estimate how many bad answers are caught, missed, and sent to reviewers each month.
Semantic entropy
200,000
8%
10%
Hallucinated answers
0
per month
Caught
0
0% recall
Missed
0
reach users
Reviewer queue
0
flagged answers
Flag precision
0%
flags that are real
Compute cost
1x
vs one generation
AUROC values are the averages across 30 task and model combinations reported in the Nature semantic entropy study. Recall at your false-alarm budget comes from an equal-variance binormal approximation, so treat it as a planning estimate. The 5 to 10 times sampling overhead comes from the semantic entropy probes paper, and the other compute multipliers are planning assumptions.
Why Language Models Hallucinate in the First Place
A language model is trained to predict the next token, and that objective rewards plausible continuations rather than verified facts. OpenAI’s research on why language models hallucinate argues that arbitrary, low-frequency facts such as a person’s birthday cannot be inferred from patterns. For those facts the model has no signal to separate truth from a convincing guess. Hallucination is therefore a predictable by-product of how models learn, and it is not a rare malfunction. Understanding this origin matters because it tells you which questions deserve the most scrutiny.
The same research points at the way models are scored after training. Accuracy-only leaderboards behave like multiple-choice exams with no penalty for wrong answers, so guessing beats abstaining. In the SimpleQA figures OpenAI published, one smaller reasoning model abstained on 52% of questions and made errors on 26%, while o4-mini abstained on 1% and erred on 75%. The second model scored slightly higher on raw accuracy, yet it produced nearly three times as many confident mistakes. Any detector you build is partly a countermeasure to this incentive problem.
Retrieval does not remove the issue, although it changes where errors come from. A retrieval-augmented system can still ignore a passage, merge two passages into a false claim, or answer from memory instead of the supplied context. Our piece on riskier hallucinations in smarter models shows why stronger reasoning can make wrong answers more persuasive. That persuasiveness is exactly why detection has to be separate from generation. A system that grades its own homework with the same weights and the same blind spots will miss many errors.
A Working Taxonomy of Hallucinations Worth Catching
Not every hallucination is the same failure, and a detector tuned for one type can be blind to another. The first useful split is between factuality errors, where a statement contradicts the world, and faithfulness errors, where a statement contradicts the supplied source. A summary that invents a clause absent from the contract is a faithfulness error even if the clause is legally plausible. A biography that gives the wrong birth year is a factuality error even if no source was supplied. Choosing the right detector starts with naming which of these two failures your product can actually suffer.
A second useful split separates confabulations from systematic errors in model behavior. Confabulations are arbitrary, so the model gives different answers when you ask repeatedly, and that instability is a detectable signal. Systematic errors come from misconceptions in training data or from flawed reasoning that repeats every time. Researchers behind a Nature study on semantic entropy say plainly that their method does not help when a model is consistently wrong. Fabricated references, invented API methods, wrong numbers, and unsupported causal claims each sit somewhere along this spectrum, so detection design must map error types to signals.
How the Main Families of LLM Hallucination Detection Techniques Compare
Stepping back from individual methods, it helps to sort LLM hallucination detection techniques by what they need from the model and from the outside world. Four families cover almost everything in use today: consistency across samples, uncertainty and internal signals, evidence-based verification, and trained or prompted judges. Each family answers a different question, and mixing them up leads to disappointing results. Consistency methods ask whether the model agrees with itself, while evidence methods ask whether the text agrees with a document. Judge methods ask whether a second model believes the first one, and probes ask whether the hidden state looks like a truthful one.
The second dividing line is the level of access you have to the model. Black-box methods work through an ordinary API and need only the generated text, which covers sampling, claim verification, and judges. Grey-box methods need token probabilities, which many hosted models expose only partially. White-box methods need hidden states or weights, so they suit open models you host yourself. This access question often decides the shortlist before accuracy even enters the discussion.
Cost is the third dividing line, and it separates the families sharply. Sampling-based detectors multiply inference spend because they generate several extra answers for every question you want to check. Researchers who proposed semantic entropy probes put that overhead at roughly 5 to 10 times the cost of a single generation. Evidence-based checks add retrieval and an entailment or judge call, which is cheaper but not free. A useful survey of simpler baselines is Galileo’s overview of five detection techniques, which includes log probability, sentence similarity, SelfCheckGPT, GPT-4 prompting, and G-Eval.
The last dividing line is the type of error each family can see. Consistency and entropy methods catch confabulations, meaning arbitrary answers that change from sample to sample. Grounding checks catch faithfulness errors, where the answer departs from the supplied document. Only external evidence can catch a systematic error, because the model repeats the same wrong claim every time it is asked. Our guide to evaluating outputs with LLM as a judge explains the judge family in more depth, and the sections below take the remaining families one by one.
Consistency Checks with SelfCheckGPT and Repeated Sampling
Building on that map, the simplest family to understand relies on a single observation about how models behave. When a model genuinely knows a fact, repeated samples tend to repeat it, but when the model is guessing, the details drift between samples. The SelfCheckGPT paper turned this into a zero-resource, black-box method that needs no probabilities and no external database. You generate several extra responses to the same prompt, then measure how well each sentence of the original answer is supported by those samples. Sentences that the samples contradict or fail to support are the likely hallucinations.
The comparison step can be implemented in several ways, and the choice changes both accuracy and cost. The original work used BERTScore similarity and a question-answering variant, and later practitioners added entailment models and LLM prompts as the comparison engine. Researchers evaluated the idea on passages about individuals from the WikiBio dataset, which GPT-3 generated and humans annotated for factuality. In that setting the sampling approach achieved considerably higher sentence-level detection scores than the grey-box baselines it was compared with. Because the method works at sentence level, it can also highlight which part of a long answer deserves review.
The weaknesses of this approach are practical, and they are worth planning around from the start. Every check multiplies generation cost, so teams usually reserve it for high-stakes answers or run it asynchronously on a sample of traffic. Low sampling temperature shrinks diversity and weakens the signal, while very high temperature creates noise that looks like hallucination. The method also cannot see an error the model makes consistently, which is the central blind spot of this whole family. For that reason sampling works best as one layer inside a larger design, with grounding and human review behind it.
Semantic Entropy and Uncertainty Estimation
Beyond simple agreement scores, the strongest published uncertainty method measures disagreement in meaning rather than in wording. A model can phrase the same answer in many ways, so naive entropy over token sequences treats harmless paraphrases as uncertainty. Researchers at Oxford, writing in Nature, sample multiple answers, group them by bidirectional entailment, and compute entropy over the resulting meaning clusters. When the clusters are many and evenly weighted, the model is probably confabulating, and when one cluster dominates, the answer is probably stable. The paper used ten generations per question and required no task-specific training data.
The reported numbers explain why the method attracted so much attention. Averaged across 30 combinations of tasks and models, semantic entropy reached an AUROC of 0.790, compared with 0.698 for P(True), 0.691 for naive entropy, and 0.687 for embedding regression. Performance stayed between 0.78 and 0.81 across LLaMA, Falcon, and Mistral families and across sizes from 7 billion to 70 billion parameters. The evaluation spanned trivia, reading comprehension, biomedical questions, and math word problems, plus a small set of generated biographies for paragraph-length checks. Those results justify treating semantic entropy as a strong baseline for any open-ended question answering system.
The limitations are just as important as the headline score. The authors state that the method does not help when a model is systematically wrong, for example because of misconceptions in its training data. Clustering can be oversensitive, since a precise date and a bare year may be treated as different answers and inflate the entropy. Results also depend on the entailment estimator, and the authors chose GPT-3.5 after comparing several options. Lead author Sebastian Farquhar summarized the scope plainly by saying that semantic uncertainty helps with specific reliability problems but is only part of the story.
Cost remains the biggest practical obstacle when teams try to use this method in production. Oxford’s own announcement notes that the method can be several times more expensive than a single call to the generating model. A follow-up on semantic entropy probes trains lightweight classifiers on hidden states to approximate the score from one generation. The authors report that this removes the 5 to 10 times sampling overhead while keeping strong detection performance and better generalization to new data. If you host open models, probes are the natural next step after you validate the idea with full sampling.
Reading the Model’s Own Hidden States with Probes
Turning to white-box access, a different line of research asks whether the network already knows when it is wrong. Researchers behind LLMs Know More Than They Show found that truthfulness information is concentrated in the exact answer tokens, not spread evenly across the output. Training a classifier on the activations at those positions noticeably improved error detection compared with using other positions. This means a model can hold the right answer internally while still generating a wrong one. That mismatch between internal knowledge and external behavior opens the door to detectors that look inside instead of reading only the text.
The same study delivers a caution that every practitioner should absorb. Error detectors did not generalize well across datasets, which suggests that truthfulness is encoded in several task-specific ways instead of one universal direction. A probe trained on trivia questions may therefore fail on code generation or on medical summaries. The practical rule is to train and validate probes on data that resembles your own traffic, and to retrain when the domain shifts. For a broader view of why internal signals matter for trust, see our explainer on why explainable AI is important.
Verifying Claims Against Evidence with Atomic Fact Checking
Moving on from signals inside the model, evidence-based verification checks the answer against something external. The most influential idea here is to decompose a long answer into atomic facts, because a paragraph that mixes true and false claims cannot be graded pass or fail. The FActScore method splits generated text into small claims and reports the share that a trusted knowledge source supports. Scoring claims one by one turns a vague worry about accuracy into a number you can track over time. In its original study, ChatGPT reached only 58% factual precision on biographies, which shows how much hidden error a fluent answer can carry.
Verification can also run inside the generation loop instead of after it. The Chain-of-Verification method has the model draft an answer, plan verification questions, answer those questions independently so earlier mistakes do not bias them, and then write a final verified response. The authors report fewer hallucinations on list questions, closed-book question answering, and long-form generation. A related benchmark paper, HaluEval, found that giving models external knowledge or asking them to reason step by step helps them recognize hallucinated text. These results suggest that evidence and reasoning improve detection even when the detector is itself a language model.
Everything in this family depends on the quality of the knowledge source behind the check. A stale index, an incomplete wiki, or a noisy web search will mark correct claims as unsupported and let outdated claims pass. Structured sources can help, and our comparison of GraphRAG against traditional RAG shows how graph retrieval changes what evidence is available. Teams should also decide in advance how to treat claims for which no evidence exists, because absence of proof is not proof of error. A three-way label of supported, contradicted, and unverifiable is more honest than a binary flag.
Groundedness and Faithfulness Scoring for RAG Systems
Looking at retrieval-augmented products specifically, the most useful question is whether each claim in the answer is backed by the retrieved passages. The Ragas faithfulness metric answers it by splitting a response into claims, checking each against the context, and dividing the supported count by the total. Its documentation gives a clean example in which a birth date contradicted by the context drops the score from 1.0 to 0.5. Faithfulness is the single most direct health metric for a RAG chatbot, because it measures the exact promise the product makes. A free variant of the metric swaps the LLM claim check for Vectara’s open HHEM classifier, which runs on a CPU.
Managed cloud services package the same underlying idea behind a simple and convenient API. Azure AI Content Safety groundedness detection takes the generated text plus the grounding sources and flags segments that are ungrounded. It offers a non-reasoning mode for low-latency binary results and a reasoning mode that explains each flagged segment for debugging. Settings for domain and task, such as medical or generic and summarization or question answering, tune the sensitivity to the vocabulary in use. A preview correction feature can rewrite an ungrounded phrase, so a sample request that said Kevin is corrected to match a source that said Jane.
Grounding checks carry their own limits that deserve a plain statement. The Microsoft documentation notes that the service is optimized for English and available only in certain regions. The quality of the verdict also depends on accurate, current source documents, which matters most in healthcare and finance. A grounded answer can still be wrong when the retrieved passage itself is wrong or when retrieval missed the right document entirely. For deeper agent-level evaluation, our walkthrough on evaluating agents with Ragas shows how these metrics extend to multi-step workflows.
Trained Detectors and LLM Judges
Choosing among learned approaches, the question is whether to prompt a general model or to train a specialist. Prompted judges are the fastest to start, since you describe the criteria and ask a strong model to grade each answer against the source. Specialist detectors are smaller, cheaper to run at scale, and can be tuned on labeled examples of your own failures. The Lynx model was built for retrieval-augmented hallucination detection and released together with HaluBench, a benchmark of about 15,000 samples from varied domains. According to its authors, Lynx outperformed GPT-4o and other judge models on that benchmark, which shows that a focused small model can beat a general giant.
Data is what makes specialists possible, and RAGTruth is the reference corpus for the task. It holds nearly 18,000 naturally generated responses with expert labels at the case level and the word level, plus severity ratings. The authors report that a relatively small model fine-tuned on this corpus detects hallucinations about as well as prompt-based detectors built on GPT-4. Judges still inherit the weaknesses of any language model, including sensitivity to prompt wording and a tendency to favor fluent answers. Calibrate every judge against human labels from your own domain before trusting its scores, and recheck after each model update. Our guide to LLM-as-a-judge evaluation shows how to run that calibration.
Benchmarks and Metrics That Show Whether Detection Works
Next, the evidence for any detector starts with choosing the right metric. AUROC measures how well a score separates hallucinated from faithful answers across all thresholds, which makes it useful for comparing methods but not for setting an operating point. Precision and recall at a chosen threshold describe what users and reviewers will actually experience. In a monitoring setting, recall tells you how many bad answers slip through, and precision tells you how many reviewer hours you waste on false alarms. A detector with a great AUROC can still be useless if its false-alarm rate at your required recall is too high.
Several public datasets let you compare detectors without building your own labels. The HaluEval benchmark reported that ChatGPT fabricated unverifiable information in about 19.5% of responses on specific topics and that models struggle to recognize hallucinations. RAGTruth supplies word-level labels for retrieval-augmented generation, and HaluBench supplies roughly 15,000 samples for judge evaluation. Vectara’s leaderboard uses its HHEM evaluator over more than 7,700 articles to rank models by summarization hallucination rate. Each dataset targets a different task, so the benchmark you pick should match the product you ship.
Every benchmark also carries caveats that should shape how you read the scores. Vectara states that its metric measures consistency with the source, not summary quality, and that copying the source text could game the number. Its document set is private to reduce overfitting, which also means outsiders cannot reproduce the results directly. OpenAI’s argument about evaluation incentives adds a further warning, because accuracy-only scoreboards reward guessing over abstaining. For a broader sanity check on vendor claims, see our analysis of AI accuracy, hype versus reality.
Putting LLM Hallucination Detection Techniques Into a Production Pipeline
In practice, the winning design is a funnel in which cheap checks run on everything and expensive checks run on a fraction. The first layer sits upstream of generation, where retrieval quality, prompt constraints, and instructions to abstain reduce the number of errors that need detecting. The second layer applies deterministic and cheap checks, such as schema validation, citation existence tests, and log-probability thresholds. Our piece on deterministic guardrails for AI agents describes this style of rule-based protection. Cheap, deterministic checks should block the obvious failures before any model-based detector spends a token.
The third layer scores groundedness for every answer that uses retrieved context. Claim-level faithfulness gives you an interpretable number, and the claim list shows reviewers exactly which sentence failed. When a claim fails, the system can regenerate with the failing evidence highlighted, return a hedged answer, or route the case to a person. Building the retrieval side well is a prerequisite, so teams starting from scratch can follow our walkthrough on how to build a RAG chatbot with open-source tools. Logging every claim score creates the dataset you need to improve the detector later.
The fourth layer applies the more expensive methods selectively, only where the risk justifies the spend. Semantic entropy or sampling consistency can run only on answers that triggered a medium risk score or that touch regulated topics. Because sampling multiplies cost, many teams run it asynchronously on a percentage of production traffic and use the results to tune the cheaper layers. Estimates from this slice also give you a running hallucination rate that you can report to stakeholders. The key design principle is that no single layer has to be perfect, since the layers fail in different ways.
The final layer is the human loop and the feedback cycle. Reviewers need a queue that surfaces the flagged claim, the evidence, and the score, and they need a one-click way to label the outcome. Those labels feed threshold calibration, detector fine-tuning, and regression tests that run before each model or prompt change. Treat the detector as a product with its own version history, owners, and service level objectives. Without this operational discipline, even an excellent detector slowly decays as traffic and models change.
Thresholds, Latency, and Cost Budgets
Given the layered design, the next decision is where to set thresholds and how much to spend. Start by writing down the cost of a missed hallucination and the cost of a false alarm in your own units, such as refunds, reviewer minutes, or legal exposure. The ratio between those costs fixes the operating point more reliably than any benchmark score. Giskard’s 2026 buyer guide recommends testing candidate tools on about 50 real production questions from your own logs. Your own traffic is the only benchmark that predicts your own results.
Latency and compute set the second constraint on how much detection you can afford per request. Sampling-based detection adds several full generations, so it rarely fits in an interactive path unless the product tolerates a pause. Groundedness classifiers and small trained detectors add far less delay and can run in parallel with response streaming. Use the interactive estimator earlier in this article to see how technique choice, volume, base error rate, and false-alarm tolerance change the number of missed and flagged answers. Pair it with a human review plan, because the loop described in our guide to human-in-the-loop expert review determines what happens after a flag.
Where Detection Falls Short: Risks and Blind Spots
Despite the progress, the most serious risk is a false sense of safety. Sampling and entropy methods are blind to consistent errors, so a model that confidently repeats a misconception will receive a clean bill of health. Probes trained on one dataset may fail on another, and LLM-based judges can share the same blind spots as the model they grade. A green dashboard means only that the detector found nothing, and it does not mean that nothing is wrong. Teams should therefore pair automated scores with periodic human audits of passed answers, not only flagged ones.
Retrieval-based products are not immune either, even when vendors say they are. A Stanford study of commercial legal research tools found that Lexis+ AI and Westlaw’s AI products hallucinated between 17% and 33% of the time despite marketing that suggested otherwise. The authors argue that claims of eliminating hallucination are overstated and that supervision remains essential. That finding is a reminder to measure your own system rather than trust a vendor label, and the Stanford legal AI study is worth reading in full. Adversarial inputs add another risk, because poisoned documents in the retrieval index can make a false claim look grounded.
Operational risks complete the picture, and they tend to appear slowly after launch. Detectors drift when models, prompts, or user behavior change, and thresholds tuned last quarter may be wrong today. False positives erode user trust and reviewer morale, which can cause teams to quietly raise thresholds until the system catches little. Benchmarks can be gamed, and a vendor that optimizes for a public leaderboard may not improve your use case. Structured adversarial testing, as covered in our guide to red teaming AI for safer models, helps expose these weaknesses before customers do.
Ethics, Accountability, and Human Oversight
Looking at the human consequences, detection is an ethical obligation as much as a technical feature. In the Moffatt case against Air Canada, a British Columbia tribunal ruled in February 2024 that the airline was responsible for what its chatbot told a customer about bereavement fares. The tribunal rejected the idea that a correct policy page elsewhere on the site excused the error. It awarded a total of $812.02, as reported in this account of the decision. Organizations cannot disclaim responsibility for what their own AI systems tell customers. The amount was small, but the principle of liability applies to far larger decisions.
Professional settings raise the stakes even further for teams that rely on generated text. In the Mata case against Avianca, a federal judge sanctioned two lawyers and their firm with a $5,000 penalty. They had submitted fake cases generated by ChatGPT and then stood by them, as the Steptoe summary of the sanctions explains. The judge found bad faith in the lawyers’ conscious avoidance and misleading statements, not in the use of the tool itself. For deployers, the lesson is that verification is a professional duty, and automated detection supports that duty without replacing it. The same logic applies to every team that lets generated text reach a customer, a court, or a regulator.
Good governance turns these hard lessons into everyday practice across the whole organization. Disclose when answers are machine generated, state known limits, and give users a path to a human. Log detector decisions so that auditors can reconstruct why a risky answer was allowed or blocked, while protecting the personal data those logs contain. Test detectors for uneven performance across languages, dialects, and topics, because a detector that flags some communities more often creates its own fairness problem. Written policies, named owners, and periodic reviews anchor these duties so they survive staff turnover.
The Future of LLM Hallucination Detection Techniques
Looking ahead, the clearest trend is the move from expensive sampling toward cheap, single-pass signals. Semantic entropy probes already approximate a multi-sample score from hidden states, and research on truthfulness tokens suggests more targeted probes are possible. If these methods mature, detection could become a near-zero-cost feature that ships inside open models rather than a separate service. Hosted models may expose richer confidence signals through their APIs, which would bring grey-box methods to more teams. Until then, black-box methods will remain the practical choice for closed models.
Evaluation practices will also change as detection becomes a standard part of deployment. OpenAI argues that leaderboards should penalize confident errors more than abstentions and give credit for appropriate uncertainty, which would reward models that know their limits. Detection research is moving toward agents, where a hallucinated tool result or invented intermediate step can corrupt an entire workflow. Regulation and procurement will likely ask for documented error rates and monitoring, in line with the governance trends and regulations already shaping enterprise AI. Teams that adopt responsible AI governance frameworks now will adapt fastest when those requirements arrive.
Chart From AIplusInfo
How well do uncertainty detectors separate hallucinations?
AUROC averaged over 30 task and model combinations. A score of 0.5 is chance and 1.0 is perfect separation.
Source: Farquhar et al., Detecting hallucinations in large language models using semantic entropy, Nature.
Key Insights on Detecting LLM Hallucinations
- The Vectara hallucination leaderboard measured summarization hallucination rates between 1.8% and 24.2% in May 2026, so model choice alone cuts errors but never removes the need for detection.
- Semantic entropy reached an average AUROC of 0.790 across 30 task and model pairs in Nature, well ahead of P(True) at 0.698, which makes it the strongest uncertainty baseline.
- Semantic entropy probes remove the 5 to 10 times sampling overhead of semantic entropy by reading hidden states from one generation, which makes cheap detection plausible for self-hosted models.
- A Stanford evaluation found commercial legal research tools hallucinating between 17% and 33% of the time, which shows retrieval alone does not guarantee faithful answers.
- The RAGTruth corpus contains nearly 18,000 annotated responses, and a small fine-tuned model matched GPT-4 prompts on detection, so specialist detectors can be both cheap and accurate.
- In OpenAI's SimpleQA figures, one model abstained 52% of the time and erred 26%, while another abstained 1% and erred 75%, so abstention behavior matters as much as accuracy.
- The FActScore study put ChatGPT at 58% factual precision on biographies and estimated that human evaluation of 6,500 generations would have cost about $26,000, so automated scoring is essential.
Taken together, these figures describe a field where detection is genuinely useful yet never complete. Model selection narrows the error rate, but the spread between the best and worst leaderboard entries shows how much risk remains. Uncertainty methods such as semantic entropy catch arbitrary answers, and cheaper probes may soon deliver similar signals from a single pass. Retrieval and legal studies show that grounding is necessary, although a retrieval-augmented tool can still fail between 17% and 33% of the time in a hard domain. Specialist detectors trained on corpora like RAGTruth, together with claim-level scoring such as FActScore, give teams interpretable numbers they can monitor over time. The practical conclusion is a layered system with measured thresholds, abstention behavior, and human review, because every layer fails in a different way.
Side-by-Side Comparison of Detection Approaches
Moving on from the individual methods, a side-by-side view makes the trade-offs between the six main approaches easier to see. The table below compares them across eight practical dimensions, from access requirements to the types of error each approach can see. No column wins every row, which is the strongest argument for combining LLM hallucination detection techniques instead of betting on one. Read the access and cost rows first, because they usually eliminate options before accuracy even matters. Read the blind spot row last, because it tells you which other layer must cover the gap. The entries summarize the published work discussed above and the documentation of the named tools.
| Dimension | Sampling consistency | Semantic entropy | Hidden-state probes | Atomic claim checks | Groundedness scoring | Trained or LLM judges |
|---|---|---|---|---|---|---|
| Access needed | Black-box text only | Samples plus an entailment model | Open weights or hidden states | Text plus a knowledge source | Text plus retrieved passages | Text, sources, and a judge model |
| Needs reference text | No | No | No | Yes | Yes | Usually yes |
| Extra generations per answer | Several | Several (ten in the Nature study) | None at test time | None | None | None |
| Extra model calls | Comparison model | Entailment model for clustering | Lightweight classifier | Claim extractor and verifier | Claim check or classifier | One judge call |
| Catches consistent errors | No | No | Sometimes | Yes, if evidence exists | Only if the sources are right | Depends on the judge |
| Best suited to | Black-box APIs and sentence-level review | Open-ended questions | Self-hosted models | Long-form factual text | RAG chatbots and summaries | Scalable triage with human labels |
| Main blind spot | Cost and repeated errors | Cost and clustering sensitivity | Poor transfer across datasets | Depends on knowledge quality | Retrieval errors pass as grounded | Judge bias and drift |
| Representative work | SelfCheckGPT | Nature 2024 | Orgad et al. 2025 | FActScore | Ragas and Azure | Lynx and HHEM |
Real-World Examples of Hallucination Detection in Practice
Beyond the theory, three public implementations show how detection is measured and used day to day. Each example below comes from a published project with its own documentation, so you can inspect the method and the limits yourself. The common thread is that every working system turns a fuzzy worry about accuracy into a number that can be tracked. Examples like these matter because a single production failure, such as a chatbot that cited a fake legal case, can undo months of trust. The first example ranks models, the second scores a retrieval pipeline, and the third scores long-form text claim by claim.
Vectara's HHEM Hallucination Leaderboard
Vectara built the Hallucination Evaluation Model and used it to rank language models on how often they add unsupported facts when summarizing documents. The team ran every model over a private set of more than 7,700 articles, telling each one to use only facts from the source. As of the May 2026 update, the best model showed a 1.8% hallucination rate with a 99.5% answer rate, while the weakest listed model reached 24.2%. That roughly thirteen-fold spread gives buyers a concrete, comparable number before they commit to a model. The limitation is that the score measures consistency with the source, not overall summary quality or every form of hallucination. The authors also warn that an LLM-based evaluator grades the models, that the private dataset blocks outside replication, and that copying the source text could game the metric. Use the leaderboard as a screening input and still run your own tests on your own documents.
Ragas Faithfulness Scoring in a RAG Pipeline
Teams running retrieval-augmented chatbots have adopted the Ragas faithfulness metric to turn groundedness into a number. The implementation splits each answer into individual claims, checks every claim against the retrieved context, and divides the supported claims by the total. In the Ragas documentation example, an answer giving the correct birth date and place scores 1.0, while an answer with a wrong date scores 0.5. That 50% drop shows how a single contradicted claim can halve the score of a short answer. A variant of the metric replaces the LLM claim check with Vectara's open HHEM-2.1-Open classifier, which runs on a CPU by default. The limitation is that a score of 1.0 only proves agreement with the retrieved text, so a wrong or incomplete retrieval can still produce a confident, fully faithful error. Teams therefore pair faithfulness with retrieval metrics and spot checks by reviewers.
FActScore Atomic Fact Scoring of Biographies
Researchers behind FActScore implemented atomic fact scoring by splitting each generated biography into small claims and checking them against a trusted knowledge source. They used the method to evaluate 6,500 generations from 13 recent language models, which would have cost about $26K to assess with human annotators. According to the FActScore paper, ChatGPT reached only 58% factual precision, and the automated estimator showed an error rate below 2%. This outcome let the team rank models by the share of supported facts instead of a vague overall impression. The main limitation is that the evaluation covered people biographies, so the numbers may not transfer to code, medicine, or finance. The scores also depend on the reliability of the knowledge source, since a gap in that source makes a true claim look unsupported. Production teams still need to validate the approach on their own domain before relying on it.
Recommended by AIplusInfo
Books to go deeper on evaluation and LLMs
Two practitioner titles that support the measurement habits described in this guide.
As an Amazon Associate, AIplusInfo earns from qualifying purchases.

Book
AI Engineering: Building Applications with Foundation Models
Covers evaluating foundation model applications, which supports the measurement and monitoring practices recommended in this guide.
Buy on Amazon
Book
Hands-On Large Language Models: Language Understanding and Generation
A visual, code-first tour of how language models work, useful for understanding why hallucinations arise and how detectors read model signals.
Buy on AmazonLessons From Case Studies of Hallucinations in the Wild
Shifting from tools to outcomes, three cases show what happens when detection works, when it is missing, and when marketing outruns measurement. Each case follows the same arc of problem, response, measurable impact, and limitation, so you can compare them directly. The pattern across all three is that fluent output was trusted before anyone verified it. The first case covers the research that created the strongest uncertainty baseline. The second covers a consulting deliverable that reached a government with fabricated citations. The third covers an independent audit of products sold as safe for professional use.
Case Study: Oxford's Semantic Entropy Research
The problem facing the Oxford team was that language models often produce confident answers that are arbitrary, and existing uncertainty measures treated harmless rewording as real doubt. Researchers needed a detector that worked without task-specific data and across very different question types. Their solution was to sample multiple answers, cluster them by meaning using bidirectional entailment, and compute entropy over the clusters, as described in the Nature paper. Averaged over 30 task and model combinations, the method reached an AUROC of 0.790, compared with 0.698 for the next best baseline. That is a lift of about 13 percent in relative terms, and it held between 0.78 and 0.81 from 7 billion to 70 billion parameters. The team also applied the idea to paragraph-length biographies by breaking them into claims first.
The limitations are well documented by the authors of the study themselves. Semantic entropy does not catch consistent mistakes, which the researchers identify as potentially the most dangerous failures. Oxford's announcement adds that the method can cost several times more than a plain model call, which restricts it to higher-risk uses. Clustering can also split answers that differ only in precision, such as a full date and a bare year, and the entailment judge introduces its own errors. A later effort on semantic entropy probes tried to cut the overhead by learning the signal from hidden states. The practical takeaway is to treat the score as a strong warning light for confabulation and to keep other layers for everything it cannot see.
Case Study: Deloitte's Government Welfare Report
Deloitte Australia faced a serious problem when a report it delivered to the Australian government for about AU$440,000 on a welfare compliance system was found to contain fabricated citations. The errors came from GPT-4o, which had been used in drafting, and no step in the review process caught the invented references before delivery. The remedy Deloitte adopted was to correct the report, disclose the use of generative AI, and repay part of the fee. OECD.AI's incident entry records the case and notes that one headline reported a repayment of almost $98,000 against the $440,000 fee. That figure equals roughly 22 percent of the contract value, which is a meaningful financial and reputational cost for an unchecked citation list. Deloitte said that the main findings of the report did not change after the corrections.
The episode exposed a limitation in how consulting deliverables are reviewed, because fluent text was accepted without checking whether each citation existed. A simple citation existence test, a deterministic check against a bibliography database, would have flagged the fabricated references automatically. Claim-level verification against retrieved sources would have added a second layer for statements that were not citations. The controversy also shows that disclosure after the fact is costly, while detection before delivery is cheap by comparison. Buyers who commission AI-assisted work have good reason to ask how generated content is verified. The concern for every deployer is that a report with an unchecked reference list carries the same hidden exposure.
Case Study: Stanford's Audit of Legal Research Tools
Lawyers faced a real problem because vendors marketed retrieval-augmented legal research tools as free of hallucinations, while earlier evidence involving general chatbots had already led to sanctions. Stanford researchers built a preregistered dataset of legal queries and a typology that separates hallucinated answers from accurate ones. They ran Lexis+ AI and Westlaw's AI-assisted tools through that benchmark and compared them with a general model, as reported in the Stanford study. The tools hallucinated between 17% and 33% of the time, which is lower than general-purpose chatbots but far from zero. Those figures contradict vendor claims of eliminating hallucinations and show that retrieval alone does not guarantee faithful answers.
The limitations of the study matter a great deal for how its numbers should be interpreted. It covers one domain, a specific set of tools at one point in time, and researcher-designed queries, so results may differ for newer versions. The authors also found substantial differences between systems in both responsiveness and accuracy, which means the average hides important variation. Because the definition of a hallucination in legal work involves judgment, reasonable experts can still argue about edge cases. The lasting lesson for any team is to measure its own system, supervise outputs, and treat vendor claims as hypotheses to test.
Frequently Asked Questions on Detecting LLM Hallucinations
LLM hallucination detection techniques are methods that flag false, fabricated, or unsupported statements in model output. They fall into four families: sampling consistency, uncertainty and internal signals, evidence verification, and judge models. Each family needs different inputs and catches a different mix of errors. Most production systems combine several of these families in one layered design.
SelfCheckGPT generates several extra responses to the same prompt and compares them with the original answer. Facts the model knows tend to repeat across samples, while invented details change or contradict each other. The method works on black-box models and needs no probabilities. Its main cost is the extra generations, and it cannot see errors the model repeats every time.
Semantic entropy samples several answers, groups those that mean the same thing, and measures uncertainty over the groups. Grouping by meaning prevents harmless rewording from looking like doubt. In the Nature study it averaged an AUROC of 0.790 across 30 task and model combinations. It does not catch systematic mistakes, and it can cost several times more than a single call.
Deterministic checks such as citation existence tests and schema validation cost almost nothing and should run first. Small trained classifiers and groundedness models add little latency compared with sampling. Semantic entropy probes aim to approximate sampling-based scores from one generation, removing a 5 to 10 times overhead. Methods that need many generations are usually the most expensive.
Score faithfulness by splitting each answer into claims and checking whether the retrieved passages support them. The Ragas faithfulness metric and Azure groundedness detection both follow this pattern. Add retrieval metrics too, because a faithful answer built on the wrong passage is still wrong. Route low-scoring answers to regeneration or to a human reviewer.
A judge can work well when you give it the source text and clear criteria. Specialist models such as Lynx were reported by their authors to outperform GPT-4o on the HaluBench benchmark. Judges still inherit biases, so calibrate them against human labels from your own domain. Recheck calibration whenever the judge model or your prompts change.
Use AUROC to compare detectors across all thresholds, then choose an operating point using precision and recall. Recall tells you how many hallucinations slip through, and precision tells you how much reviewer time false alarms waste. Public datasets such as RAGTruth and HaluBench help with comparison. Your own labeled production questions are the best final test.
Many detectors depend on the model disagreeing with itself, so a consistent error looks like confidence. Probes can fail to transfer when the domain changes, and judges can share the blind spots of the model they grade. Grounding checks pass answers that faithfully repeat a wrong source. For these reasons, detection should be layered and audited by people regularly.
There is no universal number, because the right count depends on the task and your budget. The Nature study on semantic entropy used ten generations per question. More samples usually give a steadier signal at proportionally higher cost. Test a few settings on your own data and keep the cheapest one that meets your recall target.
Black-box methods do, because they need only the generated text. Sampling consistency, claim verification, groundedness scoring, and judge models all work through a standard API. Probes and some uncertainty methods need hidden states or token probabilities, which closed models may not expose. Hosted models with partial probability access support a limited set of grey-box checks.
The organization that deploys the chatbot is generally responsible for what it tells customers. In the Air Canada case, a Canadian tribunal ruled in 2024 that the airline could not disclaim its chatbot's bereavement fare advice. It awarded the customer a total of $812.02 in damages, interest, and fees. Professional users also face duties, as the $5,000 sanction in the Mata case showed.
Retune whenever the generating model, the prompts, or the retrieval index changes, and at least on a regular schedule. Keep a labeled sample of recent production traffic to measure precision and recall over time. Rising false-alarm rates or falling recall are signs of drift. Treat every threshold change like a software release with tests.
Detection is unlikely to become unnecessary in the near term. OpenAI argues that accuracy cannot reach 100% because some questions are unanswerable, though models can learn to abstain. Public leaderboards still show large gaps between the best and worst models. Better models reduce the error rate, but high-stakes uses will keep needing detection and human review.