Why it matters: How to choose a vector database for production RAG: compare HNSW, pgvector, Pinecone and Qdrant with real benchmarks, costs and a 7-step plan.
Why it matters: Stop answering the same questions twice. Learn how to build an internal AI assistant over company documents, with code, permissions, and case studies.
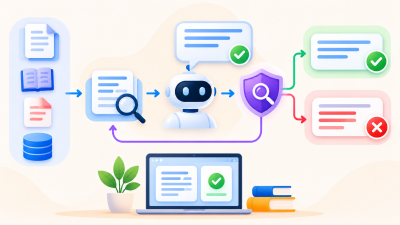
Why it matters: Retrieval does not stop hallucinations. Learn the detectors, metrics, and Python code that catch unsupported claims in RAG answers before users do.
Why it matters: Stop shipping untested prompts. Learn the context development lifecycle: generate, evaluate, distribute, and observe agent context, backed by real test data.
Why it matters: Learn how to build a RAG chatbot with open source tools: nine tested steps, working Python code, and an evaluation loop that stops hallucinations.
Why it matters: See how a semantic knowledge graph for LLM agents slashes hallucinations, adds memory, and lifted answer accuracy from 17 to 54 percent in tests.
Why it matters: Context rot makes LLMs fail long before the window fills. See why, how to measure it, and the context engineering fixes that keep answers reliable.
Why it matters: GraphRAG vs traditional RAG compared: accuracy, cost, latency, and real case studies to help you pick the right retrieval method for your data.
Why it matters: Reddit’s share soar with AI-powered answers that boost user engagement, revolutionize social media, and drive its stock to new heights.