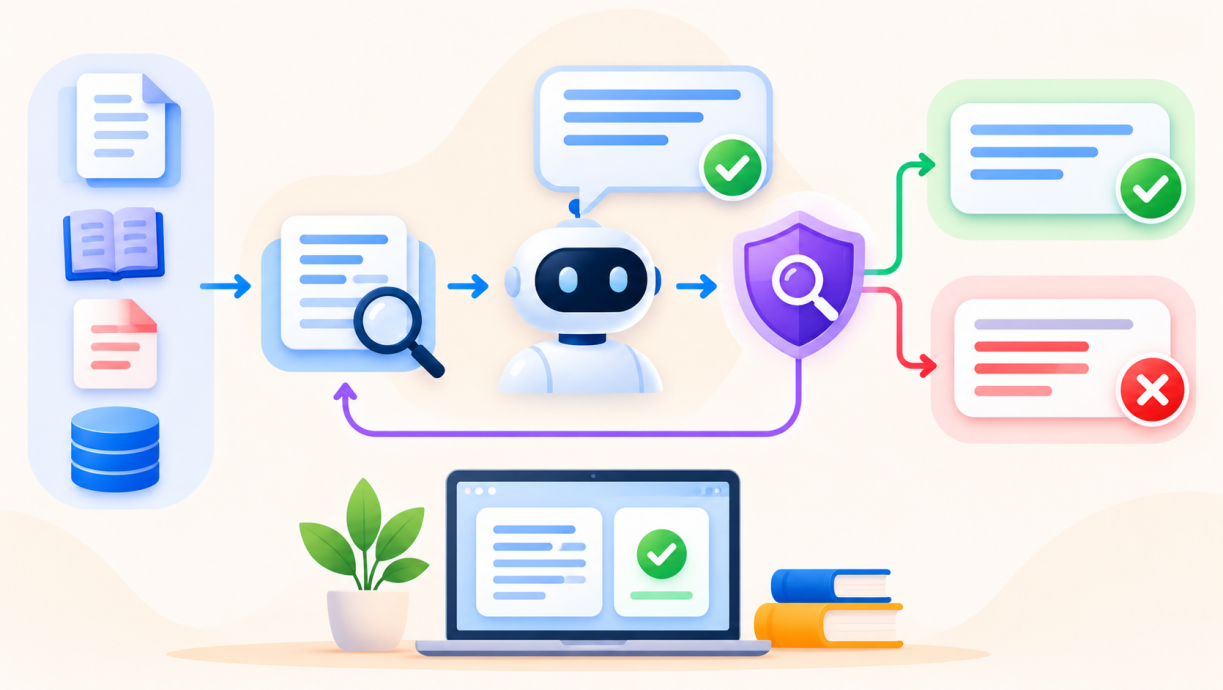

Introduction
Learning how to detect hallucinations in RAG pipelines has become a core skill for any team that ships a grounded chatbot. A Stanford study found that commercial legal research tools built on retrieval still hallucinated on 17 to 33 percent of queries. Some vendors had claimed that retrieval eliminates hallucination, and the data did not support them. Retrieval augmented generation gives a language model real documents before it answers, yet the model still chooses which facts to repeat and which to invent. A fluent answer that cites a real source can still contradict that source, and nothing in the user interface will reveal the gap. Detection is therefore a measurement discipline that sits beside retrieval and generation, and it must run on every release. This guide explains the failure modes, the detector families, the metrics, and the operating habits behind a reliable detection layer. It ends with a working implementation, real incidents, and answers to the questions engineers ask most often.
Quick Answers on How to Detect Hallucinations in RAG Pipelines
How do you detect hallucinations in RAG pipelines?
To learn how to detect hallucinations in RAG pipelines, split each answer into claims and verify every claim against the retrieved context using an entailment classifier or an LLM judge. Flag any unsupported or contradicted claim.
What is a faithfulness score in RAG?
A faithfulness score is the share of claims in a generated RAG answer that the retrieved context supports. It ranges from zero to one, and higher values mean fewer unsupported or contradicted statements.
Does retrieval stop hallucination?
No. Retrieval reduces invention but does not remove it, because the generator can still ignore, blend, or distort passages. A Stanford study found legal RAG tools still hallucinated on 17 to 33 percent of queries.
Key Takeaways
- Retrieval narrows hallucination but never eliminates it, so every RAG answer needs a faithfulness check against the exact context the model received.
- Claim-level verification, entailment classifiers, and calibrated LLM judges each fit a different budget, and the strongest systems layer them.
- Score retrieval precision, retrieval recall, faithfulness, and answer quality separately so that each failure points to the right component.
- Production monitoring, human review, and source trust controls turn a one-time evaluation into a lasting safety practice.
Table of contents
- Introduction
- Quick Answers on How to Detect Hallucinations in RAG Pipelines
- Key Takeaways
- What Is Hallucination Detection in RAG Pipelines?
- Why Retrieval Does Not Eliminate Hallucination
- The Anatomy of a RAG Failure
- Faithfulness, Groundedness, and Relevance Compared
- Building a Golden Dataset for Hallucination Testing
- Claim Extraction and Verification Methods
- Natural Language Inference Detectors and HHEM-Style Classifiers
- LLM Judges and Their Biases
- Measuring Retrieval Quality Separately
- Citation and Attribution Checks
- Uncertainty Signals and Self-Consistency Sampling
- Detection in Multi-Hop and Agentic Pipelines
- Industry Risk Profiles for Grounded Answers
- Production Monitoring and Alerting
- Thresholds, Cost, and Latency Tradeoffs
- Human Review Loops That Scale
- Security and Adversarial Failure Modes
- Ethics, Accountability, and Disclosure
- Common Mistakes Teams Make
- The Future of Hallucination Detection
- How to Detect Hallucinations in RAG Pipelines: A Working Implementation
- Step 1 – Prepare the environment
- Step 2 – Capture the full trace of every request
- Step 3 – Split the answer into atomic claims
- Step 4 – Score each claim with an entailment classifier
- Step 5 – Send borderline claims to an LLM judge
- Step 6 – Aggregate verdicts into a faithfulness score
- Step 7 – Validate the detector on the golden dataset
- Step 8 – Wire detection into the request path
- Key Insights
- Real-World Examples of RAG Hallucination Detection
- Case Studies in Grounded Answers Gone Wrong
- Frequently Asked Questions on How to Detect Hallucinations in RAG Pipelines
What Is Hallucination Detection in RAG Pipelines?
Knowing how to detect hallucinations in RAG pipelines means measuring whether each claim in a generated answer is supported by the retrieved documents. Detection combines claim verification, retrieval metrics, and monitoring so unsupported or contradicted statements are flagged before users rely on them.
An Interactive From AIplusInfo
How Much Hallucination Does Your RAG Pipeline Let Through?
Adjust retrieval quality, answer length, and detection strategy to see how many unsupported answers reach your users.
70%
8 claims
No detection
0%
Answers with an unsupported claim
0%
Still reaching users after detection
0 s
Worst-case added latency per answer
Model: each claim is unsupported with probability 1% plus 6% times the share of irrelevant passages, so the defaults land inside the 17 to 33 percent range that Stanford researchers reported for commercial legal RAG tools. Detector recall values (70, 84, and 90 percent) are illustrative assumptions anchored loosely to the 68.8 and 84.0 percent balanced accuracy figures in the FaithBench study. Latency figures come from Vectara’s HHEM-2.1 write-up, and the hybrid figure assumes that 30 percent of answers need the judge. Replace every assumption with values measured on your own data.
Why Retrieval Does Not Eliminate Hallucination
Retrieval augmented generation promised to fix hallucination by handing the model real documents before it answers. That promise holds only in part, because the generator still decides which facts to repeat, which to ignore, and which to fabricate. Marketing claims often blur this point, so buyers assume that a grounded system cannot invent anything. The Stanford legal research study showed otherwise when it measured commercial tools that hallucinated on 17 to 33 percent of queries even with retrieval in place. Teams that understand how to detect hallucinations in RAG pipelines therefore treat grounding as a property to be measured and never as a guarantee.
A grounded system can fail in two separate places, and each place needs its own diagnosis. Retrieval can return the wrong passages, an incomplete set of passages, or passages that conflict with one another. Generation can then ignore good evidence, blend two sources into a false claim, or add detail that no source supports. Because the two failures look identical in the final answer, a detection program has to inspect the retrieved context as well as the text the user sees. Without that inspection, engineers waste weeks tuning prompts when the real defect lives in the index.
The distinction between closed-book and open-book hallucination also matters for planning. A closed-book model invents facts from its training weights, which makes its errors hard to predict but easy to describe. An open-book RAG system makes subtler errors, such as citing a real document for a claim the document never makes. The site already covers the wider catalogue of LLM hallucination detection techniques, and this guide narrows that view to pipelines that retrieve before they generate. Planning a detection suite around the open-book pattern keeps the checks focused on the failures that retrieval actually creates.
The Anatomy of a RAG Failure
A typical RAG request passes through six stages: query rewriting, retrieval, reranking, context assembly, generation, and post-processing. Each stage can introduce a defect that surfaces later as a hallucination. Query rewriting may drop a qualifier such as a date or a jurisdiction, which changes the meaning of the question. Retrieval may surface a passage that is topically close but factually wrong for the case at hand. Reranking may push the one correct passage below the cutoff that the context window allows.
Context assembly deserves special attention because it is where silent truncation happens. When the assembled prompt exceeds the window, the framework may cut passages from the end without warning. The generator then answers from partial evidence and fills the missing pieces from memory. Logging the exact context that reached the model is the single most useful habit for debugging these cases. Researchers describing context rot in large language models show that quality can decay even when everything fits, which makes the log even more valuable.
Generation failures fall into three families that the later sections will test separately. The model may add information that appears nowhere in the context, which engineers call an unsupported claim. It may contradict the context, for example by reversing a negation or swapping two numbers. It may also leap beyond the evidence by drawing a conclusion the passages only hint at. Naming these families early lets a team build detectors that target each one instead of chasing a vague notion of wrongness.
Faithfulness, Groundedness, and Relevance Compared
Three words dominate evaluation discussions, and they are often used loosely. Faithfulness asks whether every claim in the answer is supported by the retrieved context. Groundedness is a near synonym in most tools, although some vendors use it to mean the answer cites a source at all. Relevance asks whether the answer addresses the user question, regardless of whether it is supported. Defining each term in writing before any dashboard is built prevents arguments about what a score actually means.
These properties are independent, which means an answer can score well on one and badly on another. An answer can be faithful but irrelevant when the model summarizes the context accurately while ignoring the question. It can be relevant but unfaithful when the model answers helpfully with facts it invented. Traceloop’s guide to automatic hallucination detection makes the same point and defines unfaithful output as information absent from the sources, contradiction of the context, or an unwarranted leap. A hallucination detector should therefore score faithfulness on its own axis and never fold it into a single quality number.
Suppose a user asks about a refund window and the retrieved policy page says thirty days. A faithful and relevant answer simply states that the window is thirty days. A faithful but irrelevant answer describes the shipping policy from the same page. An unfaithful but relevant answer claims sixty days, which sounds helpful and is simply wrong. Walking through examples like these with stakeholders makes the abstract metrics concrete.
Correctness adds a fourth axis that many teams forget to track until a customer complaint arrives. A fully faithful answer can still be wrong if the source document is outdated or mistaken. Faithfulness measures fidelity to the context, not fidelity to the world, so a stale policy page will produce confident and faithful errors. Separating these axes tells an engineer whether to fix the generator, the retriever, or the knowledge base itself. Reviewing the age of the top cited documents each month catches this class of error before users do.
Building a Golden Dataset for Hallucination Testing
Building on that vocabulary, the first practical step is a labelled dataset that reflects real traffic. Start by sampling several hundred production questions, stratified by topic and by difficulty. Include questions the corpus cannot answer, because a trustworthy system must abstain on those. Add adversarial cases such as questions containing false premises, ambiguous entities, and requests for numbers that appear in several conflicting documents. Rare but severe question types deserve extra weight, since they drive most of the real-world risk.
Each row needs the question, the gold passages, a reference answer, and a label for whether the question is answerable. Domain experts should write or approve the reference answers, since model-generated references inherit the errors you are trying to catch. Keep a record of which corpus version each row was built against, because a document update can silently invalidate a label. A golden set of two to three hundred carefully labelled rows beats ten thousand unreviewed ones for catching regressions. Teams that follow a RAG chatbot build with open source tools can reuse their ingestion logs to seed this dataset.
Version the dataset like code, and review every change in a pull request. Add each production incident as a new row so the same failure cannot return unnoticed. Hold out a slice that engineers never tune against, which gives an honest estimate of live performance. Over a few months this living set becomes the most valuable asset in the whole evaluation stack. Reviewers should also retire rows whose gold passages no longer exist in the corpus.
Claim Extraction and Verification Methods
Moving on from the dataset to the detector, the most widely used method is claim-level verification. A model splits the answer into atomic statements, and each statement is checked against the retrieved context. Traceloop describes the same three steps: extract claims, verify each one against the sources, and aggregate the verdicts. The answer counts as faithful only when every claim is supported, so a single unsupported claim flags a hallucination. This structure also gives engineers an exact list of failing claims, which is far more useful than a single pass or fail.
The approach works because long answers hide small errors that a holistic judge tends to overlook. One sentence often contains several checkable facts, such as a name, a date, and a figure. Splitting them lets the verifier catch a wrong date inside an otherwise correct sentence. Claim extraction turns a vague question about answer quality into many small questions that a verifier can settle reliably. The cost is higher latency, since each claim needs its own check, which the later section on tradeoffs addresses.
Verdict labels should be richer than a simple binary pass or fail flag. A practical scheme uses supported, contradicted, unsupported, and not factual, where the last label covers advice and formatting that the context cannot judge. The score is the number of supported claims divided by the number of scorable factual claims. OneUptime’s guidance on measuring faithfulness separately recommends reporting judge coverage next to the score, because missing verdicts can hide inside an average. Keeping the unscorable cases visible prevents a broken parser from quietly inflating the average.
Natural Language Inference Detectors and HHEM-Style Classifiers
Shifting from LLM-based verification, a second family uses small classifiers trained on natural language inference. These models take a premise and a hypothesis and return the probability that the premise supports the hypothesis. In RAG detection the retrieved context is the premise and the generated claim is the hypothesis. Vectara’s Hughes Hallucination Evaluation Model, known as HHEM, is the best-known example and returns a factual consistency score between zero and one. Because these models are small, they can be fine-tuned on a few thousand in-domain examples when the public checkpoints fall short.
The main advantage of a small classifier is its speed in production. Vectara reports that HHEM-2.1 runs in about 0.6 seconds on a consumer RTX 3090 GPU. An LLM-based RAGAS faithfulness check with GPT-4 can take up to 35 seconds for a 4096-token context. A classifier of this size can run on every production response, which an expensive judge rarely can. That latency gap is why many teams run a small classifier on all traffic and reserve the large judge for a sampled slice. The open variant also runs on modest hardware, so privacy-sensitive teams can keep the check inside their own network. Operators should confirm the figures on their own hardware before planning capacity.
How the premise is built affects the score more than most teams expect. Concatenating every passage gives the classifier everything but dilutes the salient evidence. Selecting only the cited passages focuses the check but misses claims that drew on uncited text. Many teams therefore score against the full context first and fall back to cited passages for diagnosis. Whichever approach you choose, record it in the evaluation configuration so that scores remain comparable. Changing the premise format between releases is a common source of phantom regressions.
Classifiers have limits that every careful team should respect before deployment. Training data shapes what they notice, so a model tuned on news summaries may miss errors in medical text. Scores are probabilities, not verdicts, which means each deployment needs a threshold chosen on its own labelled data. English dominates the published benchmarks, so multilingual deployments need their own validation before anyone trusts a score. Monitoring the score distribution over time reveals drift long before users notice a change in answer quality.
LLM Judges and Their Biases
Looking at the alternative, a large language model can act as a judge that reads the context and the answer and returns a verdict. The method is flexible because a prompt can encode any rubric, including domain rules that no classifier has seen. The site’s walkthrough of evaluating outputs with an LLM judge covers the prompt patterns in depth. In RAG work the judge usually receives one claim at a time, which keeps its task narrow and its verdicts consistent. Pinning the judge model version in configuration keeps scores comparable from one release to the next.
Judges carry biases that engineers must measure rather than assume away. They tend to favour longer answers, to prefer outputs from their own model family, and to be swayed by confident phrasing. Research on the FaithBench benchmark found that even strong zero-shot detectors averaged below 78 percent balanced accuracy across four datasets. A judge is an instrument that needs calibration against human labels, just like any other measurement device. Calibrating on two hundred human-labelled claims is usually enough to reveal whether a judge over-flags or under-flags.
Few-shot examples improve judge sensitivity, and the same study showed that adding annotated examples raises detection of true hallucinations. The FaithJudge approach, which uses an o3-mini-high judge with human-annotated examples, reached 84.0 percent balanced accuracy against 68.8 percent for the best zero-shot detector. That gain shows how much a careful prompt and good examples can matter. Teams should still keep a human-labelled holdout so they can notice when a judge update changes its behaviour. Reporting both the judge name and its version in every evaluation report avoids confusing comparisons later.
Measuring Retrieval Quality Separately
Stepping back from generation, a faithful answer cannot rescue a bad retrieval. Retrieval metrics belong in the same dashboard as faithfulness, because the two together reveal where a failure began. Precision at k measures how many of the retrieved passages are relevant, while recall measures whether the passages needed for the answer were retrieved at all. Both need gold relevance labels, which the golden dataset provides. Teams without gold labels can start with a small manually judged sample and expand from there.
Reading the two numbers together produces a simple diagnostic table. High recall with low faithfulness points at the generator, which ignored or distorted good evidence. Low recall with high faithfulness means the generator faithfully repeated incomplete context. OneUptime recommends scoring four dimensions separately: retrieval precision, retrieval recall, faithfulness, and answer quality. Collapsing those four numbers into one average destroys the diagnostic signal that makes detection actionable.
Ablation tests sharpen the diagnosis by isolating one component at a time. Feeding the generator the gold passages shows whether it can be faithful when retrieval is perfect. Feeding it deliberately noisy context shows whether it abstains or bluffs. Teams that rely on GraphRAG-style retrieval instead of plain vector search should run the same ablations, since graph traversal introduces its own failure modes. Each ablation takes minutes to run once the golden dataset and the logging are in place.
Citation and Attribution Checks
Turning to the output format, many RAG products show inline citations, and those citations deserve their own verification. A citation can fail in three distinct ways that each need a different check. The cited document may not exist, the cited passage may not contain the claim, or the claim may be supported by a different document than the one cited. Each failure erodes user trust faster than an uncited error, because the citation signals a verification that never happened. Verifying citations is therefore not optional for any product that displays them.
A mechanical check handles the first failure: confirm that every cited identifier exists in the retrieved set. The second check uses the same entailment machinery as faithfulness but scoped to the cited passage alone. A claim that is entailed by the full context but not by its cited passage is a misattribution, and it should count as an error. Precision of attribution is a separate metric from faithfulness, and products that display citations should report both. The incident described in the AI chatbot that cited a fake legal case shows the damage a fabricated citation can cause.
Interface design also shapes how users treat the citations they see. A citation that opens the exact passage with the supporting sentence highlighted invites verification, while a bare footnote number invites blind trust. Showing the quote is helpful, whereas showing a raw support score to users is risky. Teams can also display a gentle warning when a claim lacks a supporting span. These design choices change user behaviour, so test them with real readers before launch. Combine design tests with the mechanical checks above so that the interface and the verifier reinforce each other.
Recall of citations matters too, because an uncited claim cannot be audited. Track the share of factual sentences that carry a citation, and set a policy for sentences that do not. Some teams strip uncited claims, others flag them for review, and others require abstention. The right policy depends on the cost of an error in your domain. Whatever the policy, log every uncited sentence so reviewers can audit the decision later.
Uncertainty Signals and Self-Consistency Sampling
Beyond verification against context, a detector can watch the model itself for signs of uncertainty. Token-level probabilities offer one signal, since low confidence on key tokens often accompanies invented details. Entropy over the answer distribution offers another, though providers that hide log probabilities make both harder to use. When the model is accessible, these signals cost almost nothing to collect. Providers differ widely in what they expose, so confirm the available signals before designing around them.
Self-consistency sampling provides a signal that works through any API. The system asks the same question several times at a nonzero temperature and compares the answers. Claims that appear in every sample are more likely to be grounded, while claims that vary between samples are suspect. Disagreement between samples is a cheap hallucination alarm, although agreement alone never proves that an answer is correct. A model can repeat the same wrong claim every time when the context itself is misleading.
Use these signals as triage rather than as final verdicts. A high uncertainty score can route a response to the heavier claim-level verifier, which saves cost on the confident majority. A low uncertainty score does not clear a response, so keep a random sample flowing through the full verifier regardless. This layered design keeps the evaluation spend proportional to the risk of each response. Readers who want related dashboards can consult the guide to reducing LLM hallucinations in production for more patterns.
Detection in Multi-Hop and Agentic Pipelines
From there, the problem grows harder when a pipeline retrieves more than once before answering. Multi-hop questions require the system to find one fact, use it to form a second query, and combine the results. An error in the first hop contaminates every later hop, and the final answer may look coherent while resting on a false premise. Faithfulness scoring against the final context alone can miss this, because the early mistake sits in an intermediate step. Trace-level evaluation, which scores each hop, is the safer approach.
Agentic systems add tool calls, planning, and memory to the mix. An agent may summarize a document, store the summary, and later treat that summary as ground truth. Any stored summary is a derived claim, and it should carry a pointer back to the source passages so detectors can re-verify it. The walkthrough on evaluating Amazon Bedrock agents with RAGAS shows how trace data can feed these checks. Teams that skip provenance find that a single bad memory entry keeps resurfacing in later answers.
Structured knowledge can reduce a meaningful share of this risk in some domains. When facts live in a graph with typed relations, a verifier can check a claim against an explicit edge instead of a paragraph. The overview of a semantic knowledge graph for LLM agents explains the pattern and its costs. Graph checks do not replace text verification, but they give a second, independent opinion on high-stakes facts such as dosages, prices, and legal thresholds. Maintaining the graph costs effort, so reserve it for the facts that justify the investment.
Industry Risk Profiles for Grounded Answers
In practice, the right detection budget depends on what a wrong answer costs. A recipe assistant that misstates a cooking time creates a mild annoyance. A clinical assistant that misstates a dosage can injure a patient. Mapping each use case to a severity tier lets a team spend heavy verification where it matters and light checks elsewhere. The tiers should be written down and reviewed by someone who owns the risk.
Healthcare and life sciences sit at the top of most severity maps. Answers often involve doses, contraindications, and eligibility rules where a single digit changes the meaning. Detectors in this domain should verify every numeric claim against the source passage and abstain when the passage is ambiguous. High-severity domains should default to refusing an answer rather than risking an unsupported one. Human review remains essential, as the discussion of human-in-the-loop accuracy boosts explains.
Legal and compliance work carries a different hazard, which is fabricated authority. The Stanford findings on legal research tools showed that retrieval alone did not remove errors from legal answers. Finance adds time sensitivity, since a correct rate from last quarter becomes a wrong answer today. Both domains benefit from attribution checks and from stamping each retrieved passage with its effective date. Stamping dates on passages also lets the generator prefer the newest guidance when two documents disagree.
Public-sector and customer-support deployments sit in the middle but carry reputational weight. Citizens and customers treat an official channel as authoritative, which raises the harm of any mistake. Broader evidence in the piece on AI accuracy, hype versus reality suggests that confidence in these tools often outruns their measured reliability. A modest, visible disclaimer paired with a strong detector is better than either alone. Public agencies should publish the known limits of the system on the same page as the chat window.
Production Monitoring and Alerting
Setting offline testing aside, live traffic needs continuous monitoring because corpora, prompts, and models all change. Sample a fixed percentage of responses, run the full verifier on them, and plot the unsupported-claim rate over time. Alert on sudden jumps and on slow upward drift, since each points to a different cause. A jump often follows a deployment or a re-index, while drift usually reflects a changing question mix. Dashboards should show the rate by topic as well as overall, since averages hide local failures.
Log enough detail to reproduce every flagged case on a developer machine. Store the query, the rewritten query, the retrieved passages with ids and versions, the final prompt, the answer, and the detector verdicts. A hallucination you cannot reproduce is a hallucination you cannot fix. Teams that already use deterministic guardrails for AI agents can attach detector verdicts to the same event stream. Reviewing the top flagged cases weekly turns monitoring into a steady source of new test rows.
Thresholds, Cost, and Latency Tradeoffs
Weighing the options, every detector trades accuracy against cost and speed. A small classifier is fast and cheap but less flexible. An LLM judge is flexible and often more accurate but slower and more expensive per call. Vectara’s published comparison shows the gap clearly, with HHEM-2.1 near 0.6 seconds per check on a consumer GPU against up to 35 seconds for a GPT-4 faithfulness check. Most production systems end up combining both styles rather than choosing a single winner.
Thresholds convert scores into decisions, and they should be set from data. Plot precision and recall for the detector across thresholds on the golden dataset, then pick the point that matches your risk tolerance. A medical assistant might accept many false alarms to catch nearly every real hallucination. A casual assistant might prefer fewer false alarms so that users are not constantly refused. There is no universal threshold, only the one that matches the cost of each kind of error in your product.
Latency budgets decide where detection can sit in the request path. Blocking detection delays the answer but can stop a bad response from reaching the user. Asynchronous detection adds no delay but can only flag or retract after the fact. Many teams combine both, running a fast classifier inline and a thorough judge in the background on a sample. Whichever mix you choose, record the added latency in your service level objectives.
Human Review Loops That Scale
Given the limits of automated detectors, human review remains the ground truth for calibration. Reviewers are expensive, so the system should send them only the cases where their judgment adds the most value. Good candidates include responses the detector marked uncertain, responses in high-severity topics, and a random sample for unbiased measurement. Each reviewed case should flow back into the golden dataset. A weekly review session of thirty minutes is often enough to keep the loop healthy. Practical mitigation steps are collected in the guide to reducing LLM hallucinations in production.
Interface design affects review quality more than most teams expect. Show the claim, the retrieved passages, and the detector verdict side by side, and let the reviewer highlight the supporting span. Reviewers who can see the evidence next to the claim agree with each other far more often than reviewers who see only the final answer. Measure inter-reviewer agreement regularly, and retrain the guidelines when it drops. Clear labels for supported, contradicted, and unsupported keep the data usable.
Reviewer feedback should also improve the detector itself over successive release cycles. Use disagreements between humans and the detector to find systematic blind spots, such as negation or numeric ranges. Add targeted examples to the judge prompt or fine-tune the classifier on the hard cases. Over time the detector learns the quirks of your domain, and the review queue shrinks. Track the shrinking queue as a leading indicator that the whole system is maturing.
Security and Adversarial Failure Modes
Beyond accidental errors, an attacker can cause hallucination on purpose. Corpus poisoning inserts a document with false claims, so the retriever faithfully returns it and the generator faithfully repeats it. A faithfulness detector will pass such an answer, because it is supported by the retrieved context. Faithfulness protects against model invention but not against a malicious or mistaken source, so it must be paired with source trust controls. Provenance tags, document signing, and review of new content address the root cause.
Prompt injection offers an attacker a second route to the same outcome. Instructions hidden inside a retrieved page can steer the generator away from the real question. The guide to prompt injection defenses describes the patterns in detail. Detection should therefore include checks for answers that follow instructions found inside documents, and ingestion should strip or quarantine suspicious content before it reaches the index. Red team exercises that plant such pages in a test corpus reveal how exposed the pipeline really is.
Ethics, Accountability, and Disclosure
Stepping back to the human side, detection is partly an ethical commitment. Users deserve to know when they are reading machine-generated text and how reliable it is. A published accuracy figure, even an imperfect one, is more honest than an implied promise of correctness. Organizations should decide in advance who is accountable when a grounded answer causes harm. Courts and regulators have already shown that the company, not the chatbot, bears that responsibility.
Fairness enters the picture when error rates differ noticeably across user groups. A system trained mostly on English documents may hallucinate more often for questions about minority languages or regional rules. Slice every metric by language, region, and topic to find these gaps. Reporting a single average hides the groups that the system serves worst. Where gaps appear, invest in better corpora and in-language evaluation before expanding the audience.
Transparency also means telling users what to do with an uncertain answer. Provide links to the underlying passages, offer a way to report errors, and make escalation to a person easy. Rankings such as the top AI models with minimal hallucination rates help in model selection, but they never remove the need for your own measurement. Keep an incident log and share lessons internally so the same mistake does not recur. Review that log quarterly with legal and product leaders in the same room.
Common Mistakes Teams Make
Looking across many deployments, the most common mistake is trusting a single aggregate score. A faithfulness average of ninety percent can hide a cluster of severe errors in one topic. Another mistake is evaluating only on easy questions, which flatters the system and misses the hard cases. A third is tuning the prompt against the same examples used for evaluation, which inflates results through overfitting. Every one of these mistakes comes from measuring what is convenient instead of what is risky.
Teams also confuse retrieval fixes with generation fixes when diagnosing a failure. Adding more documents often raises recall but also adds conflicting passages, which can lower faithfulness. Fine-tuning the model may reduce some invention but cannot update facts that change weekly, a tradeoff covered in the comparison of retrieval augmented generation versus fine-tuning. Finally, many teams ship without an abstention path, so the model feels pressure to answer even when the context is empty. Knowing how to detect hallucinations in RAG pipelines includes knowing when the correct output is no answer.
The Future of Hallucination Detection
Looking ahead, detection is moving toward cheaper and more accurate specialized models. The FaithBench work found that HHEM-2.1-open, a model of only 110 million parameters, outperformed several much larger models. If that trend continues, strong detectors will run on a laptop or inside a browser. That would make universal, inline checking affordable for even small teams. Vendors will likely bundle such detectors into frameworks, which lowers the barrier further.
Better benchmarks will also shape how the field measures progress. Human-annotated leaderboards now cover more than 130 language models, and judge-based methods such as FaithJudge reach 84.0 percent balanced accuracy on hard cases. Expect richer labels that separate harmless paraphrase from true error, since benign differences are where current judges struggle. The next gains will come from detectors that understand intent and materiality, not only literal agreement. Work on context engineering, such as the analysis of context engineering for LLM agents, will reduce errors before detection is even needed.
Regulation and procurement are likely to push measurement into the standard toolkit. Buyers already ask vendors for accuracy evidence, and public failures have made that question routine. Teams that publish their methods and results will earn trust faster than those that rely on marketing claims. Mastering how to detect hallucinations in RAG pipelines today is the best preparation for that more demanding environment. Early preparation also shortens the audit cycle when a customer or regulator eventually asks for evidence.
Chart From AIplusInfo
How well detectors catch hallucinations
Balanced accuracy on FaithBench, in percent. Higher is better.
Source: Benchmarking LLM Faithfulness in RAG with Evolving Leaderboards. The top zero-shot bar shows the reported ceiling for average balanced accuracy across four datasets.
How to Detect Hallucinations in RAG Pipelines: A Working Implementation
This walkthrough builds a compact detection layer in Python that you can attach to almost any retrieval pipeline. It uses an open entailment classifier for fast claim checks and a language model for claim extraction and borderline judgments. Every component sits behind a small function, so you can swap providers without rewriting the logic. The code is deliberately short and favours clarity over cleverness. Treat it as a reference design to adapt, and validate each part on your own labelled data before relying on it.
Step 1 - Prepare the environment
Start with a clean virtual environment so the detector's dependencies stay isolated from the application. You need the Transformers library for the entailment model, PyTorch as its backend, and your language model provider's client. The open HHEM-2.1 checkpoint is published under the Apache 2.0 license on the Hugging Face model card, which also documents the expected inputs. A consumer GPU speeds scoring noticeably, though the model also runs on a CPU for modest volumes. Pro tip: pin exact library versions in a requirements file, because detector scores can shift slightly between releases.
python3 -m venv .venv
source .venv/bin/activate
pip install transformers torch
pip freeze > requirements.txt
Step 2 - Capture the full trace of every request
Detection is only as good as the evidence you keep, so define a trace record before writing any checks. The record holds the user question, the rewritten query, the retrieved passages with identifiers, the final prompt, and the generated answer. Storing the passages exactly as the generator saw them matters more than any other field. Include a corpus version so that a later re-index cannot change the meaning of an old trace. Capture all five fields for 100 percent of requests, even when only 5 percent will later receive the full judge. Keep the record immutable once written, and append detector results as separate fields.
from dataclasses import dataclass, field
from typing import List, Dict, Any

@dataclass
class Passage:
    doc_id: str
    text: str
    version: str = "v1"

@dataclass
class RagTrace:
    question: str
    rewritten_query: str
    passages: List[Passage]
    prompt: str
    answer: str
    verdicts: List[Dict[str, Any]] = field(default_factory=list)

    def context(self) -> str:
        return "\n\n".join(p.text for p in self.passages)
Step 3 - Split the answer into atomic claims
Claim extraction converts a paragraph into short statements that a verifier can judge one at a time. A language model does this well when the prompt demands self-contained claims that resolve pronouns and keep numbers intact. Ask for strict JSON output so that the parser never has to guess where a claim ends. Reject and retry any response that fails to parse, up to 2 more attempts, and log the failure so that parsing errors do not silently shrink the claim set. Keep each call under roughly 500 words of answer text, and split longer responses by paragraph so that no claim is lost. Pro tip: tell the model to skip advice, greetings, and formatting, since those statements cannot be checked against the context.
import json

CLAIM_PROMPT = """Split the answer into atomic factual claims.
Each claim must stand alone, keep all numbers and names,
and replace pronouns with the entity they refer to.
Ignore greetings, advice, and formatting.
Return only a JSON list of strings.

Answer:
{answer}
"""

def call_llm(prompt: str) -> str:
    # Replace with your provider client. Must return plain text.
    raise NotImplementedError

def extract_claims(answer: str, retries: int = 2) -> list:
    for _ in range(retries + 1):
        raw = call_llm(CLAIM_PROMPT.format(answer=answer))
        try:
            claims = json.loads(raw)
            if isinstance(claims, list):
                return [c for c in claims if isinstance(c, str) and c.strip()]
        except json.JSONDecodeError:
            continue
    return []
Step 4 - Score each claim with an entailment classifier
The classifier receives the retrieved context as the premise and one claim as the hypothesis. It returns a score between zero and one, where higher means the context supports the claim. The model card notes that detection is asymmetric, so always keep the evidence in the premise slot. Score all claims in a single batch to use the hardware efficiently. Vectara reports about 0.6 seconds per check on a consumer GPU, which keeps small batches practical for interactive use. Store the raw scores, because you will need them to tune thresholds later.
Long contexts deserve a moment of careful thought before you deploy. The model accepts long inputs, yet very long premises can dilute the signal for a claim that depends on one sentence. A practical compromise scores each claim against the full context and again against the top few passages, then keeps the higher score. This costs a second call but reduces false alarms on long documents. Compare both variants on your golden dataset before adopting the extra step.
from transformers import AutoModelForSequenceClassification

_model = AutoModelForSequenceClassification.from_pretrained(
    "vectara/hallucination_evaluation_model", trust_remote_code=True
)

def entailment_scores(context: str, claims: list) -> list:
    pairs = [(context, c) for c in claims]
    scores = _model.predict(pairs)
    return [float(s) for s in scores]
Step 5 - Send borderline claims to an LLM judge
Scores near the middle of the range are the least trustworthy, so route them to a stronger judge. Define a band such as 0.35 to 0.65 and call the judge only for claims that fall inside it. The judge prompt should show the context, the claim, and a fixed set of allowed labels. Ask for a one-sentence reason along with the label, since reasons make human review much faster. This hybrid design keeps average cost low while giving the hardest cases a second opinion. Expect roughly 30 percent of claims to land inside such a band at first, and tighten it as the classifier improves.
JUDGE_PROMPT = """You are checking one claim against a context.
Label it SUPPORTED, CONTRADICTED, or UNSUPPORTED using only the context.
Reply as JSON: {{"label": "...", "reason": "..."}}

Context:
{context}

Claim:
{claim}
"""

def judge_claim(context: str, claim: str) -> dict:
    raw = call_llm(JUDGE_PROMPT.format(context=context, claim=claim))
    try:
        return json.loads(raw)
    except json.JSONDecodeError:
        return {"label": "UNSCORABLE", "reason": "parse failure"}
Step 6 - Aggregate verdicts into a faithfulness score
Combine the classifier scores and judge labels into one verdict per claim, then compute the share of supported claims. Choose a support threshold from your labelled data and record it in configuration rather than in code. Keep unscorable claims out of the denominator but report their count next to the score. A support threshold near 0.9 is a common starting point, and high-severity topics usually require 0 contradicted claims. An answer passes only if its score clears the bar and no claim is marked contradicted. Pro tip: treat contradicted claims as a hard failure regardless of the overall score, because they carry the highest risk.
SUPPORT_T = 0.5
BAND = (0.35, 0.65)

def verify(trace: RagTrace) -> dict:
    claims = extract_claims(trace.answer)
    ctx = trace.context()
    scores = entailment_scores(ctx, claims) if claims else []
    supported, contradicted, unscorable = 0, 0, 0
    for claim, s in zip(claims, scores):
        label = "SUPPORTED" if s >= SUPPORT_T else "UNSUPPORTED"
        if BAND[0] <= s <= BAND[1]:
            verdict = judge_claim(ctx, claim)
            label = verdict.get("label", "UNSCORABLE")
        trace.verdicts.append({"claim": claim, "score": s, "label": label})
        supported += label == "SUPPORTED"
        contradicted += label == "CONTRADICTED"
        unscorable += label == "UNSCORABLE"
    scorable = max(len(claims) - unscorable, 1)
    faithfulness = supported / scorable
    return {"faithfulness": faithfulness, "contradicted": contradicted,
            "unscorable": unscorable, "claims": len(claims),
            "passed": faithfulness >= 0.9 and contradicted == 0}
Step 7 - Validate the detector on the golden dataset
A detector that has never been tested against human labels is just another source of unverified numbers. Run the pipeline over every golden row and compare the verdicts with the reviewers' claim labels. Aim for at least 200 labelled claims so that the precision and recall estimates are stable. Compute precision, which tells you how many flagged claims were truly unsupported, and recall, which tells you how many true errors were caught. Plot both across thresholds and choose the operating point that suits your risk tolerance. The earlier discussion of LLM-as-a-judge evaluation guide explains how to check judge agreement in the same pass.
def detector_report(rows, threshold=0.5):
    tp = fp = fn = 0
    for row in rows:  # row: {"claims": [{"score": float, "human_unsupported": bool}]}
        for c in row["claims"]:
            flagged = c["score"] < threshold
            tp += flagged and c["human_unsupported"]
            fp += flagged and not c["human_unsupported"]
            fn += (not flagged) and c["human_unsupported"]
    precision = tp / max(tp + fp, 1)
    recall = tp / max(tp + fn, 1)
    return {"precision": round(precision, 3), "recall": round(recall, 3)}
Step 8 - Wire detection into the request path
Production wiring decides whether the detector protects users or merely produces reports. Run the fast classifier inline on every response and block or soften answers that fail. Push a random sample through the full pipeline with the judge, and store the results for dashboards and weekly review. When an answer fails, return a safe fallback such as a refusal with links to the retrieved sources. Start with a sampling rate near 5 percent for the full pipeline, and raise it whenever incident counts increase. Pro tip: never show users the raw detector score, because it invites false precision and confuses support teams.
Finally, make the behaviour configurable so that operators can tighten or relax it without a deployment. Expose the thresholds, the sampling rate, and the fallback message in a configuration file. Emit a metric for every verdict so that the alerting rules from the monitoring section can fire. With these pieces in place you have a complete loop of detection, measurement, and improvement. Document each setting so that on-call engineers understand what changes when they adjust it.
import random

SAMPLE_RATE = 0.05
FALLBACK = "I could not verify that answer against the sources, so here are the documents I found."

def guarded_answer(trace: RagTrace) -> str:
    ctx = trace.context()
    claims = extract_claims(trace.answer)
    scores = entailment_scores(ctx, claims) if claims else []
    if scores and min(scores) < 0.2:
        return FALLBACK
    if random.random() < SAMPLE_RATE:
        result = verify(trace)  # full pipeline, logged for review
        if not result["passed"]:
            return FALLBACK
    return trace.answer
Recommended by AIplusInfo
Books to go deeper on building reliable RAG
Hand-picked titles that map to the evaluation and retrieval work described above.
As an Amazon Associate, AIplusInfo earns from qualifying purchases.

Book
AI Engineering: Building Applications with Foundation Models
Covers evaluation, retrieval, and guardrail design for foundation model applications, the practical backdrop to every detection technique above.
Buy on Amazon
Book
Hands-On Large Language Models: Language Understanding and Generation
Walks through embeddings, retrieval, and semantic search with working code, which helps readers build and debug the retrieval half of a RAG pipeline.
Buy on AmazonKey Insights
- Commercial legal research tools built on retrieval still hallucinated on 17 to 33 percent of queries, which proves that retrieval narrows the problem without closing it.
- Vectara reports that HHEM-2.1 scores a claim in about 0.6 seconds on a consumer GPU, which makes inline checking of every response affordable for most teams.
- A GPT-4 based faithfulness check can take up to 35 seconds on a 4096-token context according to Vectara's benchmark write-up, so expensive judges belong on sampled traffic.
- The FaithJudge method reached 84.0 percent balanced accuracy on FaithBench, against 68.8 percent for the best zero-shot detector, which shows that annotated examples lift judge quality.
- Across twelve models in the expanded leaderboard, hallucination rates ranged from 7.63 percent to 28.38 percent, so model choice can shift summary faithfulness by nearly a factor of four.
- Google said AI Overviews showed unacceptable content for fewer than one in 7 million unique queries, yet a handful of viral errors still forced product restrictions.
- New York City's MyCity chatbot cost around half a million dollars according to the mayor, and the city removed it in early 2026 after reports of wrong legal advice.
- HHEM has been downloaded over 3.5 million times and its leaderboard covers more than 130 models, evidence that open detectors have become standard infrastructure.
Taken together, these figures describe a field that has moved from hoping retrieval would solve hallucination to measuring how much of it remains. The legal research data shows that the problem is large enough to matter in professional settings. The detector benchmarks show that accuracy depends heavily on method, with annotated judges and small specialized classifiers beating naive zero-shot prompting. The latency numbers explain why most teams split their checks between a fast inline classifier and a slower sampled judge. Public incidents add the final lesson, which is that the cost of an unchecked answer is paid in money, trust, and legal exposure.
| Dimension | Claim-level LLM judge | Entailment classifier | Self-consistency sampling | Human review |
|---|---|---|---|---|
| Best for | Borderline and domain-specific claims | Fast screening of all traffic | Cheap triage without context | High-severity answers and calibration |
| Typical latency | Seconds per answer, up to 35 for a GPT-4 check | About 0.6 seconds on a consumer GPU | Several model calls per question | Minutes to days |
| Cost per check | Highest per call | Low after hardware | Multiplies generation cost | Highest per item |
| Needs retrieved context | Yes | Yes | No | Usually yes |
| Catches unsupported claims | Strong with annotated examples | Strong on clear cases | Indirect, through disagreement | Strongest |
| Catches contradictions | Strong | Strong | Weak | Strongest |
| Main weakness | Judge bias and drift | Domain shift and English focus | Repeats consistent errors | Does not scale |
| Calibration need | Two hundred labelled claims | Threshold per domain | Sample count and temperature | Clear labelling guidelines |
Real-World Examples of RAG Hallucination Detection
Stanford's Evaluation of Commercial Legal Research Tools
Researchers at Stanford ran a preregistered evaluation of commercial legal research assistants that were built on retrieval and marketed with strong accuracy claims. They checked the answers to legal queries against authoritative sources and found that the tools hallucinated on 17 to 33 percent of queries. Some providers had said that retrieval eliminates hallucination or guarantees hallucination-free citations, and the authors judged those claims overstated. The tools did perform better than a general purpose chatbot, so retrieval clearly helped. The limit of that result is that a one in three error rate is still unacceptable for work where a fabricated authority can sanction a lawyer. The study gave legal teams concrete evidence for why every output still needs supervision and verification.
Vectara's HHEM Leaderboard for Summary Faithfulness
Vectara built HHEM, a classifier that returns a factual consistency score between zero and one, and used it to rank language models on summary faithfulness. The company reported that HHEM-2.1 beat GPT-4 by more than 30 percent in relative F1 on hallucination detection while scoring in about 0.6 seconds on a consumer GPU. The leaderboard now covers more than 130 models, and the open checkpoint has been downloaded over 3.5 million times according to the FaithBench paper. That paper also found 16 ranking inversions against human labels for the HHEM leaderboard, compared with 6 for a judge-based alternative. The limitation is that the published benchmarks are in English and measure summarization, so they still need validation on a question answering product. Teams that adopted the model usually ran it as a first-pass filter and kept human labels for calibration.
FaithJudge and the FaithBench Study
Researchers built FaithJudge, a method that prompts an o3-mini-high judge with human-annotated examples of hallucinated and faithful summaries. They tested it across several datasets and reported 84.0 percent balanced accuracy on FaithBench. The best zero-shot detector reached only 68.8 percent on the same benchmark, and top zero-shot methods averaged below 78 percent across four datasets. Adding more annotated examples to the prompt raised sensitivity, which gives practitioners a cheap lever to pull. The drawback is that the judge still under-flags hallucinations compared with human annotators for several models and often labels benign differences as consistent. The authors also found that combining multiple judges did not beat the single best judge on the hardest benchmark.
Case Studies in Grounded Answers Gone Wrong
Case Study: Air Canada's Bereavement Fare Chatbot
Jake Moffatt asked the Air Canada website chatbot about bereavement fares after a death in his family. The problem was that the chatbot told him he could claim the reduced rate after travel, while a linked policy page said the opposite. According to the American Bar Association summary, the bot allegedly said the request could be submitted within 90 days of ticket issuance. When the dispute went unresolved, Moffatt took the dispute to the British Columbia Civil Resolution Tribunal. Air Canada argued that the chatbot was a separate legal entity responsible for its own statements.
The tribunal rejected that argument and treated the chatbot as part of the airline's website, which made the company responsible for what it said. It found negligent misrepresentation and ordered compensation of approximately 650 Canadian dollars plus interest and fees. The ruling also noted that a customer should not be expected to cross-check a chatbot against other pages. The amount was small, but the controversy was large, because the decision established that a grounded answer's errors belong to the deployer. A detector that compared the chatbot reply with the policy page would likely have flagged the contradiction before the customer relied on it.
Case Study: New York City's MyCity Business Chatbot
New York City launched the MyCity chatbot in fall 2023 to help business owners understand city rules. Testing by The Markup and THE CITY found that the chatbot gave wrong answers on high-stakes topics, which was the central problem. It said landlords could refuse tenants with Section 8 vouchers, claimed that businesses could refuse cash despite a 2020 city law, and suggested that bosses could take workers' tips. Officials responded by adding a disclaimer against treating answers as legal advice and by improving some answers. The fix appeared to work partly by limiting the questions the bot would answer.
According to The Markup's reporting, the mayor later said the project cost around half a million dollars. The city removed the chatbot in early 2026, ending a beta test that had drawn criticism for more than two years. Critics argued that a disclaimer cannot offset an official channel that tells businesses to break the law. A claim-level verifier tied to the actual statutes would have flagged answers that contradicted the 2020 cash law. The case shows that faithfulness to a retrieved page does not help when the corpus itself is incomplete or outdated.
Case Study: Google's AI Overviews and the Glue-on-Pizza Answer
Google rolled out AI Overviews widely in May 2024, and users quickly posted answers that told them to put glue on pizza. The problem, as MIT Technology Review explained, is that the system likely retrieved a joke forum post that looked relevant to the query. Relevance does not guarantee accuracy, and the generation step did not check the claim against any trusted source. Conflicting sources can also blend into a misleading answer, and the system sometimes reversed the meaning of an academic essay. Google would not confirm whether the feature uses retrieval augmented generation, though the article says it likely does.
Google's head of search wrote that the company would build better detection for nonsensical queries, limit user-generated content in answers, and restrict triggers where the feature was not helpful. TechCrunch reported the response and also noted that the company would avoid showing overviews for hard news and would add protections for health searches. Google said unacceptable content appeared for fewer than one in 7 million unique queries, a figure that critics found hard to square with the visible errors. Some experts argued that the feature should have been optional until it matured. The episode shows why source quality scoring and claim verification belong in the pipeline before launch, since a rare error at scale still reaches many people.
Frequently Asked Questions on How to Detect Hallucinations in RAG Pipelines
A hallucination in a RAG pipeline is any claim in the generated answer that the retrieved context does not support. It includes invented facts, statements that contradict the sources, and conclusions that leap beyond the evidence. The answer may sound fluent and even cite a real document while still being wrong. Detection focuses on comparing each claim with the passages the model actually received.
Retrieval reduces invention but does not fully stop it, because the generator still decides what to repeat from the passages. Stanford researchers found that commercial legal research tools built on retrieval hallucinated on 17 to 33 percent of queries. Retrieval can also surface wrong or conflicting passages that the model then repeats faithfully. Every RAG system therefore needs its own measurement layer to verify what it says.
Faithfulness asks whether every claim in the answer is supported by the retrieved context. Relevance asks whether the answer actually addresses the question the user asked. An answer can be faithful but irrelevant when it summarizes the context accurately and ignores the question. Teams should score the two on separate axes so that each failure points to the right fix.
No single method wins on every dimension, so most production teams layer several of them. Teams learning how to detect hallucinations in RAG pipelines usually start with a fast entailment classifier on all traffic. They then add an LLM judge on borderline claims and a random sample, plus human review for high-severity topics. This layering balances accuracy, cost, and latency better than any single detector can.
Accuracy varies widely with the judge, the prompt, and the benchmark. On the FaithBench study, top zero-shot detectors averaged below 78 percent balanced accuracy across four datasets. The FaithJudge method with annotated examples reached 84.0 percent on the hardest benchmark. Always calibrate any judge against a few hundred human-labelled claims from your own domain.
HHEM is Vectara's Hughes Hallucination Evaluation Model, an open classifier that checks whether a hypothesis is supported by a premise. You pass the retrieved context as the premise and a generated claim as the hypothesis. It returns a score between zero and one, where higher means more consistent with the evidence. The open version runs on consumer hardware and is licensed under Apache 2.0.
Two to three hundred carefully labelled rows are usually enough to catch most regressions and to calibrate a judge. Stratify them by topic and difficulty, and include questions the corpus cannot answer. Domain experts should write or approve every reference answer in the dataset. Add every production incident as a new row so the set grows with your system.
Score retrieval precision, retrieval recall, faithfulness, and answer quality as four separate numbers. Then run ablations, such as giving the generator the gold passages and checking whether faithfulness improves. If it stays low with perfect context, the generator is at fault. If it rises, the retriever or the index needs attention.
There is no universal threshold, because the right value depends on the cost of each kind of error. Plot precision and recall for your detector across thresholds on the golden dataset. Choose the point that matches your tolerance for false alarms and missed hallucinations. High-severity domains usually choose stricter thresholds and accept more refusals.
Use both patterns according to your latency budget and the risk of each topic. A fast classifier can run inline and block or soften answers that clearly fail. A thorough judge can run in the background on a sample and feed dashboards and review queues. Blocking is most valuable in high-severity domains where a single bad answer can cause real harm.
Run the full golden dataset on every change to the prompt, model, retriever, or corpus. Add continuous sampling in production to catch drift between releases. Review the top flagged cases weekly and fold them into the test set. Treat the evaluation suite like a regression suite that gates every deployment.
Yes, because faithfulness only measures agreement with the retrieved context. If an attacker or a mistake places false content in the corpus, the generator can repeat it faithfully. Source trust controls such as provenance tags, document review, and signing address this root cause. Detection should be paired with ingestion safeguards rather than treated as a complete defense.
Describe it as an error rate that can be measured, not a mysterious flaw. Share the unsupported-claim rate on a labelled test set and the severity tier of each use case. Use real incidents, such as the Air Canada chatbot ruling, to show that the deploying company is accountable. Pair the numbers with a clear plan for monitoring and escalation.