Introduction
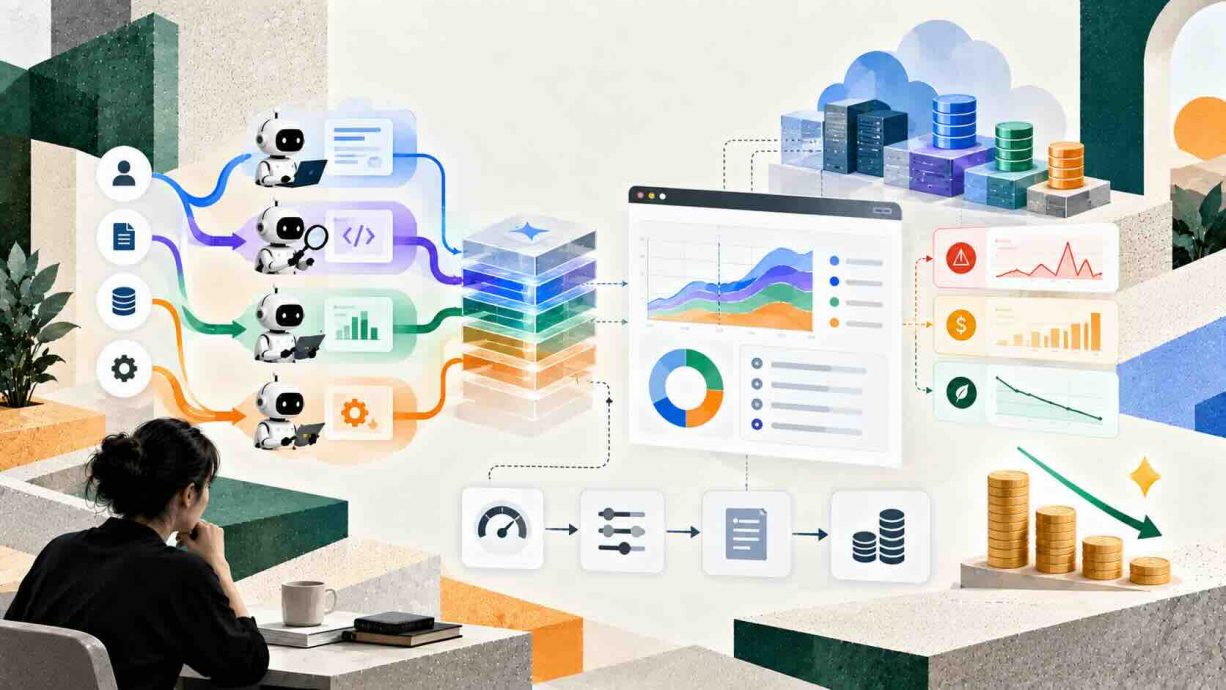
FinOps for agentic AI is the discipline of keeping autonomous software agents financially accountable. The topic is urgent because Gartner expects over 40 percent of agentic AI projects to be canceled by end of 2027, citing rising costs, unclear value, and weak controls. A chatbot answers one question and stops, while an agent plans, calls tools, reads the results, retries, and keeps going until it decides the job is done. Every one of those loops burns tokens, API calls, and compute that nobody approved line by line. Traditional cloud cost management assumed that people launch resources and that spend follows capacity, but agents launch their own work and spend follows behavior. This guide explains how to measure that behavior, assign it to an owner, cap it with budgets, and judge it against the value an agent actually delivers. You will find unit economics, attribution, showback and chargeback, guardrails, vendor pricing models, and a working implementation path. The goal is simple: let agents run at full speed without letting the bill become a surprise.
Quick Answers on FinOps for Agentic AI
What is FinOps for agentic AI?
FinOps for agentic AI applies cloud financial management to autonomous agents. It tracks token and tool spend per task, attributes cost to teams, enforces budgets and guardrails, and compares spending with the business outcomes agents deliver.
Why do AI agents cost so much more than chatbots?
Agentic AI loops. Each plan, tool call, retry, and validation step re-sends context, so Anthropic measured agents at roughly four times the tokens of chat and multi-agent systems at about fifteen times.
What is the best unit metric for agent cost?
Cost per resolved task is the best metric. Divide total spend, including failed and abandoned runs, by the number of jobs the agent actually completed, instead of relying on price per million tokens.
Key Takeaways
- Agent cost follows behavior, not capacity, so budgets must be enforced per run, per agent, and per team at the gateway.
- Cost per resolved task, which counts failed runs, is the honest unit metric for FinOps for agentic AI.
- Showback builds cost awareness first, and chargeback should follow only after attribution data is trusted.
- Routing, prompt caching, and batching cut spend without touching quality when they are measured against outcomes.
Table of contents
- Introduction
- Quick Answers on FinOps for Agentic AI
- Key Takeaways
- What Is FinOps for Agentic AI?
- Why Agents Break the Traditional Cloud Cost Model
- Where the Tokens Go Inside an Agent Loop
- Cost per Resolved Task as the Core Unit Metric
- Setting Token Budgets That Survive Real Workloads
- Attributing Spend Across Agents, Tools, and Teams
- Showback and Chargeback for Autonomous Workloads
- Guardrails, Circuit Breakers, and Kill Switches
- Routing, Caching, and Batching as Cost Levers
- Telemetry and Observability for Agent Spend
- Seats, Credits, and Outcomes in Vendor Pricing
- Forecasting Spend for Non-Deterministic Workloads
- Organizing People and Process Around Agent Costs
- Risks That Quietly Inflate the Agent Bill
- Ethics, Fairness, and Trust in Cost Governance
- Weighing Spend Against Agent Performance
- The Future of Agent Cost Governance
- How to Implement an Agent Cost Governance Practice Step by Step
- Step 1 – Inventory agents and assign owners
- Step 2 – Route every call through a gateway with required tags
- Step 3 – Record a cost ledger entry for every run
- Step 4 – Set hierarchical budgets and per-run caps
- Step 5 – Add circuit breakers inside the agent loop
- Step 6 – Publish showback and review it every week
- Key Insights
- Real Examples of Agent Spend Surprises and Fixes
- Case Studies in Agent Pricing and Spend Control
- Frequently Asked Questions on FinOps for Agentic AI
What Is FinOps for Agentic AI?
FinOps for agentic AI is the practice of measuring, attributing, budgeting, and optimizing the variable costs of autonomous AI agents, such as tokens, tool calls, and compute, so every run is accountable to an owner and a business outcome.
An Interactive From AIplusInfo
What Will Your Agent Really Cost?
Set the workload, the loop length, the failure rate, and the model tier to see monthly spend, cost per resolved task, and the budget caps worth enforcing.
20,000
12 calls
20%
Mid-tier model
$0
Estimated monthly spend
Every run counts, resolved or not.
$0
Cost per resolved task
Spend divided by resolved runs.
0
Tokens per run
Versus a single chat exchange.
$0
Suggested per-run cap
Monthly budget to approve: $0
Illustrative model: 3,200 tokens per call, a 1,500-token chat baseline, and placeholder blended prices of $0.80, $4, and $12 per million tokens. Benchmark multiples come from Anthropic’s multi-agent research system write-up. Replace the assumptions with figures from your own run ledger.
Why Agents Break the Traditional Cloud Cost Model
Classic FinOps grew up around virtual machines, storage, and managed services whose cost followed provisioned capacity. An engineer launched an instance, the tag said who owned it, and the bill grew in a way that a dashboard could explain. Agentic workloads break that link because the unit of spend is no longer a resource, it is a decision made by a model at runtime. An agent that searches the web twelve times, rewrites a plan, and calls a larger model to verify has authorized spend that no engineer typed into a console. The FinOps Foundation notes in its AI guidance that many AI services charge per token rather than per compute hour. That difference is the first reason existing playbooks fall short.
Building on that shift, the second problem is the wide variance in cost between runs of the same agent. Two runs against two similar tickets can differ in cost by an order of magnitude. One run may resolve on the first pass while the other spirals through retries. Cost per request, the metric most dashboards show, hides this spread behind an average that nobody ever actually experiences. Budget owners then see a monthly figure that jumps without any change in traffic, which makes forecasting feel like guesswork. Gartner has described this pattern as the inference paradox, where falling token prices coexist with rising total bills because capable agents consume far more tokens per task.
Stepping back from the bill itself, the third problem is deciding who actually owns the spend. A single agent platform often serves many products, each calling shared models through shared keys, so the invoice arrives as one line item from one vendor. Nobody can say which product, team, or customer triggered the spend without deliberate instrumentation. The same pattern appears in how AI agent pricing is evolving, where vendors themselves are searching for units that match value, since raw tokens do not. Anthropic reports that multi-agent systems use about fifteen times more tokens than chat, which explains why a prototype that looked cheap in a demo can look alarming in production.
Where the Tokens Go Inside an Agent Loop
Looking at a single agent run makes the cost structure of FinOps for agentic AI visible, and it rarely resembles the single prompt and response that pricing pages assume. A typical run starts with a system prompt, tool definitions, and retrieved documents, then sends all of that again on every step. The model reasons, emits a tool call, receives a result, and appends everything to the context before the next call. Input tokens usually dominate, because the growing transcript is re-sent to the model at every turn of the loop. Output tokens are fewer but cost more per unit, so reasoning-heavy steps can still dominate the invoice even when they are rare.
Beyond the visible steps, several hidden multipliers inflate the total. Planning and replanning cycles repeat context that the agent already has, and self-correction loops pay twice for the same work. Tool calls that return large payloads, such as full web pages or entire database rows, push thousands of irrelevant tokens into every later turn. Retries after malformed tool arguments or timeouts consume tokens for attempts that produce nothing. Failed runs that end in escalation or abandonment still cost the same as successes, yet they never appear in a cost-per-success figure unless someone counts them on purpose.
Turning to the architecture, multi-agent designs add a coordination tax on top of single-agent loops. An orchestrator briefs several workers, each worker builds its own context, and the orchestrator then reads every worker’s output before synthesizing an answer. Anthropic found in its multi-agent research system that token usage alone explained about 80 percent of performance variance on the BrowseComp evaluation, which means extra tokens often buy extra quality. That finding cuts both ways for FinOps, because cutting tokens blindly can lower accuracy. It is why context engineering for LLM agents matters as much as price. Teams comparing frameworks such as Google ADK and LangGraph for orchestration should therefore compare token overhead per step alongside features.
Finally, the shape of the loop depends on how much freedom the agent has. A tightly scripted workflow with two model calls costs a predictable amount, while an open-ended research agent may take four calls or forty. The more autonomy a design grants, the wider the cost distribution becomes, and the more important it is to measure percentiles rather than averages. A practical habit is to log the number of model calls, tool calls, and tokens for every run, then review the ninety-fifth percentile weekly. That tail is where runaway behavior hides, and it is usually where a single fix saves the most money.
Cost per Resolved Task as the Core Unit Metric
Moving on from raw consumption to meaning, the central question in FinOps for agentic AI is what one successful outcome costs. Price per million tokens describes the vendor’s rate card, but it says nothing about how many tokens a job needs or whether the job finished. The most useful unit metric is cost per resolved task, which divides total spend over a period by the number of jobs the agent actually completed. The numerator must include failed runs, retries, abandoned sessions, and the cost of human escalations that followed an agent failure. Teams that adopt this definition often discover that their real unit cost is far higher than their per-token dashboards implied.
The FinOps Foundation’s guidance on unit economics for AI lists cost per inference, cost per token, resource utilization, and time to business value as the core measures. Those are sound starting points for model hosting, yet agents need one more layer that links spend to the business event. For a support agent that event is a resolved ticket, for a coding agent it is a merged change, and for a research agent it is an accepted report. Each of these has a human-equivalent cost that provides a ceiling, because an agent that costs more than the person it replaces has no financial case. Pairing the metric with quality is essential, which is why the approach in how to measure AI agent performance belongs in the same dashboard as spend.
Rounding out the picture, a handful of derived ratios turn the headline metric into something managers can act on. Success rate shows what fraction of runs finish, so a low rate with a low unit cost signals cheap failure rather than efficiency. Tokens per resolved task reveals context bloat, and tool calls per resolved task reveals planning waste. Cost per escalation matters wherever a human takes over, because the human time is part of the true cost of the automated path. Tracking these four ratios together prevents the classic mistake of cutting cost per run while the number of runs needed per outcome quietly rises.
Setting Token Budgets That Survive Real Workloads
Looking at controls first, budgets are the tool most teams reach for, and they fail when set as a single monthly number. A token budget works only when it is hierarchical in structure. It needs a ceiling for the organization, a share for each team, and a smaller cap on each key, agent, and run. The generative AI cost per token trends and budgeting guide on this site covers the price side of that planning. Tools such as the LiteLLM proxy budget controls implement this hierarchy with personal, team, and key budgets plus a reset window such as thirty days. A budget that only alerts after the money is spent is a report, so real protection requires enforcement before the request reaches the model.
Sizing the numbers is the harder half of the job. Start from observed cost per resolved task at the median and the ninety-fifth percentile. Then set the per-run cap between the two, so normal hard jobs finish and runaway jobs stop. A per-run cap that sits at the median will truncate legitimate complex work and teach teams to disable the control. A cap far above the tail provides no protection at all. Review the caps monthly against the latest distribution, because prompt changes, model upgrades, and new tools all shift the shape.
Attributing Spend Across Agents, Tools, and Teams
Shifting from limits to visibility, no budget can be enforced unless spend is attributed to something that has an owner. The FinOps Foundation points out that identifying the consumer of model output becomes difficult when several interfaces inside one application share a single model. Attribution therefore starts at the request, not at the invoice. Every model call should carry metadata that names the team, product, agent, environment, and ideally the end customer or workflow that triggered it. If a call reaches the model without an owner tag, treat it as a defect, because untagged spend can never be budgeted, charged back, or explained.
Cloud providers already offer native hooks for this kind of tagging. Amazon Bedrock lets teams create application inference profiles that support cost allocation tags, so spend can be grouped by application or cost center in billing reports. A gateway in front of all providers adds a second layer, stamping each request with virtual keys that map to teams and agents regardless of which vendor served the call. Combining both gives provider-side invoices that reconcile with gateway-side ledgers, which is essential when finance asks why the two numbers differ. Teams that evaluate agents with tooling such as Amazon Bedrock Agents with RAGAS can attach the same identifiers to evaluation traffic so test spend is separated from production.
Next, agents create a subtler attribution problem because one user request fans out into many internal calls. A parent run spawns child runs, each child calls tools, and some tools call other models, so the cost tree has depth. The ledger should record a trace identifier and a parent identifier on every call, which lets analysts roll child costs up to the originating task. Without this tree, the orchestrator looks cheap while its workers hide the real spend, and optimization effort lands on the wrong component. With it, teams can answer questions such as which tool call contributes most to cost per resolved task.
Looking at shared infrastructure, some costs cannot be traced to a single request and need an allocation rule. Vector databases, embedding jobs, evaluation suites, and fixed-capacity GPU endpoints serve many agents at once. The usual options are proportional allocation by request count, by token volume, or by a weighted blend that reflects each agent’s real footprint. Pick one rule, document it, and apply it consistently, because the credibility of the whole program depends on teams trusting that the split is fair. Publish the rule alongside the numbers so that disputes become discussions about the method rather than arguments about the totals.
Showback and Chargeback for Autonomous Workloads
Building on attribution, the next decision in FinOps for agentic AI is what to do with the numbers. Showback reports each team’s agent spend back to them without moving money, while chargeback actually bills the team’s budget. The FinOps Foundation notes that tagging enables showback models that increase cost awareness without immediate chargebacks. Start with showback, because chargeback on top of unreliable attribution turns every invoice into a political dispute. A few months of transparent showback also reveals which agents deserve investment, since teams begin asking why their support agent costs three times the sales agent.
Moving to chargeback, the preconditions are concrete and worth checking before any money moves. Attribution coverage should exceed about 95 percent of spend, and shared-cost rules should be published. Teams should also hold levers they can pull, such as choosing a cheaper model or tightening a cap. Charging a team for spend it cannot influence breeds resentment rather than discipline. Many organizations adopt a hybrid, echoed in enterprise AI cost optimization strategies, in which platform costs are shared as overhead and variable consumption is charged back. Internal rates should be stable for a quarter so that teams can plan, even if vendor prices move underneath.
Considering the agent-specific wrinkles, chargeback has to deal with spend that benefits several teams. A shared research agent may answer questions for sales, legal, and product, and splitting that cost by headcount is rarely accurate. Tagging each request with the requesting team solves most of it, because the ledger already knows who asked. Another wrinkle is experimentation, where new agents consume budget before they prove value. Many teams give pilots a capped innovation allowance that is exempt from chargeback for a fixed period, then switch them to normal accountability once they reach production.
Guardrails, Circuit Breakers, and Kill Switches
Turning to enforcement, budgets set the limits and guardrails make those limits real while an agent is running. A guardrail is any rule that stops, slows, or redirects a run when it crosses a threshold of cost, steps, or time. The most valuable guardrail is a hard cap on retries, because a retry loop is the cheapest bug to write and the most expensive one to run. Pair it with a maximum number of steps per run, a maximum number of tool calls per minute, and a wall-clock timeout that ends sessions nobody is watching. The article on deterministic guardrails for AI agents explains how to keep these rules outside the model. That placement means a clever prompt cannot argue them away.
Beyond single-run limits, a good design layers controls at several levels. Per-run caps catch runaway loops, per-agent daily ceilings catch bugs that affect every run, and per-team monthly budgets catch slow drift. Soft thresholds at 50 and 80 percent of a budget should notify owners. The hard limit at 100 percent should block or degrade service according to a policy chosen in advance. Decide before the incident whether the agent fails closed or falls back to a cheaper model. A customer-facing agent that simply stops may cost more than the overage it prevented. Finally, keep a documented kill switch that a single on-call engineer can pull, and rehearse it the way teams rehearse failover.
Routing, Caching, and Batching as Cost Levers
Shifting from limits to savings, three technical levers account for most of the legitimate cost reduction available to agent teams. Model routing sends easy steps to small, cheap models and reserves the flagship model for the hard ones. Gartner recommends this approach when it urges product leaders to build multimodel ecosystems with inference tiering. Prompt caching exploits the fact that agents resend the same long prefix on every turn. According to Anthropic’s prompt caching documentation, cache reads cost a tenth of the base input price on standard models. A five-minute cache write costs 1.25 times the base price. Because an agent loop reuses its system prompt and tool definitions dozens of times, caching is usually the first optimization that pays for itself. Readers who want implementation detail can read the prompt caching explained guide on this site.
Batching handles work that does not need an immediate answer. OpenAI documents a Batch API that offers a 50 percent discount compared with synchronous calls, with results returned within a 24-hour window. Nightly evaluations, bulk document classification, and offline enrichment agents are natural candidates, since nobody waits for the response. The saving is large, but only for workloads that tolerate the delay, so the practical step is to inventory agent jobs and mark each one as interactive or deferrable. Even a modest share of deferrable traffic moved to a batch lane lowers the monthly bill without any visible change for users.
On top of these levers, every optimization needs a quality check before it counts as a saving. A cheaper model that fails more often raises cost per resolved task even though cost per call falls. A cache that serves stale context can quietly degrade answers. Run each change against a fixed evaluation set, compare cost per resolved task and success rate side by side, and keep the change only when both hold. This discipline is what separates FinOps for agentic AI from simple cost cutting, since the target is value per dollar rather than a smaller invoice.
Telemetry and Observability for Agent Spend
Stepping back to instrumentation, none of the controls above work without a trustworthy record of what each run cost. The core artifact is a per-run cost record that captures the trace identifier, agent, team, model, input tokens, output tokens, cached tokens, tool calls, duration, and outcome. Emit one record per model call and one summary per run, and store them where finance and engineering can both query them. If the record does not include the outcome, you can compute cost per call but never cost per resolved task. The guidance in how to reduce LLM inference costs pairs well with this record, because it shows where the biggest savings tend to hide.
Next, align the record with open standards so tools can read it. OpenTelemetry maintains semantic conventions for generative AI that define spans, metrics, and events for model clients. Using those names means your gateway, your application traces, and your cost warehouse all describe the same call the same way. It also keeps you portable if you change observability vendors or add a second model provider. A consistent schema is unglamorous, yet it is the difference between a one-hour investigation and a one-week reconciliation.
Looking at what to watch, a small set of views covers most needs. A daily spend chart by team and agent shows trends, and a histogram of cost per run shows the tail where runaway behavior lives. A ranking of the most expensive tool calls shows where context bloat originates, and a ratio of cached to uncached input tokens shows whether caching is working. Alerts should fire on rate of change, such as spend per hour doubling, not just on absolute thresholds. These views belong on the same screen as quality metrics so that nobody celebrates a cost drop that coincides with a success-rate drop.
On top of the dashboards, decide how long records live and how much detail each one keeps. Full per-call records are valuable for investigations, but they can themselves become a cost when agents generate millions of calls per day. A common compromise keeps every call for a few weeks, retains run summaries for a year, and samples raw prompts for debugging. Redact sensitive content before storage, since finance and engineering staff will both read the ledger and may not be cleared for customer data. Finally, reconcile the ledger total with the provider invoice every month, and investigate any gap larger than a few percent.
Seats, Credits, and Outcomes in Vendor Pricing
Beyond your own infrastructure, many agents are bought rather than built, so FinOps for agentic AI must also account for how vendor pricing models shape spend. Three families dominate: per-seat licenses, consumption credits, and outcome-based fees. Seats are predictable but ignore usage, so they suit assistants that humans operate one at a time. Credits track usage, which fits agents that act on their own, but they push forecasting risk onto the buyer. Outcome-based pricing shifts the risk back to the vendor, and it only works when both sides agree on what counts as a successful outcome.
Salesforce shows clearly how vendors move between these models over time. Its Agentforce product was first priced at $2 per conversation. It then added Flex Credits at $500 per 100,000 credits, where each action consumes 20 credits, or $0.10 per action, as described in the Salesforce pricing announcement. The company justified the change by noting that 90 percent of CIOs say managing AI costs limits their ability to drive value. Intercom takes the outcome route with Fin priced at $0.99 per resolution, charging nothing when the customer asks for a human or Fin escalates. Both approaches turn a vague usage bill into a unit that finance can compare with the cost of a human-handled ticket.
Choosing among these options is itself a FinOps decision that deserves a documented analysis. Buyers should model expected volume under each plan, including the cases where the agent fails and where volume spikes. They should also ask how the vendor defines an action or outcome, since a definition that counts every internal step can multiply the effective price. Contracts should include spending caps, alerting, and the right to export usage data in a form that joins to your own ledger. A monthly outcome limit, like the one Intercom offers, is exactly the kind of guardrail that belongs in every purchased agent contract.
Forecasting Spend for Non-Deterministic Workloads
Given the variability of agent runs, forecasting in FinOps for agentic AI needs a different method than the straight-line extrapolation used for virtual machines. A traditional forecast multiplies a known number of instances by a known hourly rate, whereas an agent forecast multiplies volume by a distribution of cost per run. A credible forecast is a range with a median and a ninety-fifth percentile, not a single number. Start with expected task volume by workflow, then apply the observed cost distribution for each, and add scenarios for adoption growth and model price changes. The adoption trends collected in agentic AI adoption statistics for 2026 offer useful context for setting growth assumptions.
Moving to the drivers, four inputs move a forecast more than any others. Volume growth is the obvious one, since a successful agent attracts more tasks. Task mix matters because a shift toward harder tasks raises tokens per run even if volume is flat. Model changes matter in both directions, since a new model may cut price per token yet raise tokens per task through longer reasoning. Finally, context growth over time, such as longer histories and larger knowledge bases, quietly raises input cost on every call.
Looking at the evidence for caution, Gartner predicts that inference cost per agentic workflow will rise more than fivefold through 2028 even as token prices fall. Teams that forecast by multiplying today’s tokens by tomorrow’s lower prices will therefore under-budget. A sounder approach assumes that each new capability generation consumes more tokens and checks the assumption against actual telemetry every month. Treat the forecast as a living document, with variance reviews that explain differences between plan and actual in terms of volume, mix, price, and efficiency. Over time those reviews teach the organization which assumptions to trust.
Rounding out the method, tie the forecast to the portfolio rather than to individual agents. Some pilots will be canceled, some will scale, and a few will surprise everyone with demand, so a portfolio view allows reserve capacity for the surprises. The finding in why AI pilots fail to scale in enterprises shows that cost uncertainty is one of the reasons promising pilots stall before production. A pre-approved contingency pool, released only against evidence of value, lets teams scale winners quickly without reopening the whole budget. It also gives finance a way to say yes with a limit rather than no with a lecture.
Organizing People and Process Around Agent Costs
Stepping back to the organizational side, tools alone do not create accountability, and the people structure decides whether the data gets used. The State of FinOps 2026 survey gathered 1,192 respondents who together represent about $83 billion in annual cloud spend. It found that 98 percent of respondents now manage AI costs, up from 31 percent two years earlier. That jump means AI cost management is no longer a specialty, so every FinOps team needs a named owner for agent spend. The owner works with platform engineers who run the gateway and product owners who decide where agents are deployed. Finance partners maintain the rates and budgets that give the whole program a shared language.
Next, define clear responsibilities for each group so that nothing falls between teams. Platform engineering owns the gateway, the tagging enforcement, and the guardrails that protect shared budgets. Product teams own their agents’ cost per resolved task and their budgets, and they decide which optimizations to adopt. Finance owns the showback reports, the internal rate cards, and the monthly forecast process that ties them together. Security and governance teams review agent permissions and spending authority, in line with the controls described in Microsoft Agent 365 and enterprise agent governance.
Risks That Quietly Inflate the Agent Bill
Looking at failure modes, the most dangerous cost risks in FinOps for agentic AI are the ones that look like normal operation until the invoice arrives. A retry storm happens when a flaky tool causes an agent to loop through the same failing step hundreds of times. A context explosion happens when each step appends a large payload and the transcript grows until every call costs ten times more than the first. Runaway spend rarely comes from one dramatic failure, and far more often from a small inefficiency multiplied across thousands of runs. Real users have felt this: Replit users reported overruns after Agent 3, including $1,000 spent in one week against a typical $180 to $200 monthly cost.
Beyond accidents, adversaries can also create spend on purpose, and they need very little skill to do it. A prompt injection can instruct an agent to fetch huge documents, call expensive tools repeatedly, or spawn sub-agents, turning the budget itself into the attack surface. This is sometimes called a denial-of-wallet attack, and the defenses are the same budgets, rate limits, and step caps described earlier. Oversight design also matters, as discussed in autonomous AI agents challenging oversight frameworks, because an agent with unchecked authority can commit the organization to spend. Require human approval for any action above a defined cost or irreversibility threshold.
Considering the reverse risk, over-aggressive cost control causes its own damage. A budget kill switch that halts a customer-facing agent during peak demand can cost more in lost revenue than the overage it prevents. Cheap-model routing that silently lowers quality can raise escalations to human staff, which moves cost rather than removing it. Vendor price changes, deprecations, and rate-limit shifts can also invalidate a forecast overnight. Mitigate by keeping a second approved model, testing fallbacks regularly, and reviewing pricing announcements as part of the monthly FinOps cycle.
Ethics, Fairness, and Trust in Cost Governance
Shifting from finance to fairness, cost governance decides who gets to use powerful tools and who does not. A rigid per-team budget can leave a small team without access to the agents that would help it most. Meanwhile a large team with a generous cost center spends freely, whether or not the spend creates value. Good governance treats access to agents as a resource to be allocated on purpose, not a side effect of whoever has the largest cost center. Transparency helps, so publish the rules for how budgets are set, how shared costs are split, and how exceptions are granted.
Turning to individuals, usage monitoring raises privacy and trust questions. Per-user cost reports can tempt managers to rank employees by token consumption, which rewards waste or punishes experimentation depending on the framing. Report at the team and workflow level, and reserve per-user views for investigating anomalies. The same fairness question appears in vendor plans, and Anthropic offers a telling case. It introduced weekly limits for Claude Code after some users ran it continuously in the background, and it said fewer than 5 percent of subscribers would notice. The episode shows that unlimited plans eventually meet an economic limit, and that how a limit is communicated shapes trust. Lock-in raises a related concern, so review the portability points in vendor lock-in for agentic AI platforms before committing to a single pricing model.
Weighing Spend Against Agent Performance
Stepping back to purpose, cost data in FinOps for agentic AI means little until it is set against what the agent achieves. An agent that costs two dollars per task and resolves 90 percent of cases may be a bargain. One that costs twenty cents and resolves only 20 percent of cases is an expensive disappointment. The right question is never whether an agent is cheap, but whether each dollar buys enough verified value. Anthropic makes the same point about multi-agent systems, which it says need tasks valuable enough to pay for the extra performance they deliver.
Building on that principle, create a quality-adjusted unit cost by dividing spend by successful outcomes that passed review. Compare it with the fully loaded cost of the human or legacy process the agent replaces or assists, including rework and escalation time. The broader framework in measuring ROI on AI investments helps translate those figures into payback periods and risk-adjusted returns. Include soft benefits only when they can be tied to a number, such as faster resolution time or higher conversion. Review the comparison quarterly, because model prices, task mix, and human wages all move.
In practice, the review often leads to one of four decisions. Scale the agents whose quality-adjusted cost beats the baseline by a wide margin, and invest in making them cheaper still. Fix agents that deliver value at too high a cost by applying routing, caching, and context trimming. Narrow the scope of agents that only work on a subset of tasks, so they stop spending on cases they fail. Retire agents that cannot beat the baseline after a fair trial, and record the lesson so the next proposal starts with better assumptions.
The Future of Agent Cost Governance
Looking ahead, the direction of travel is toward more spend per task, not less, which makes governance more valuable over time. Gartner predicts that inference costs per agentic workflow will increase more than fivefold through 2028. Analyst Will Sommer argues that product leaders cannot rely on efficient token economics to rationalize AI costs. Each generation of capability, he says, needs more and often more expensive tokens. Organizations that treat FinOps for agentic AI as a permanent operating function, rather than a one-time cleanup, will be the ones still running agents in 2028. Expect inference tiering, routing, and orchestration to become standard parts of every agent platform.
Beyond that, expect tooling and commercial models to mature around the problem. Gateways will ship with built-in budgets, per-agent ledgers, and showback exports, so the instrumentation described in this guide becomes a configuration choice instead of a project. Vendors will continue moving from seats toward credits and outcomes, which makes the unit-economics skills of buyers even more important. Standards for describing AI usage will make cross-vendor comparison easier. The teams that already track cost per resolved task will adapt easily, because they will know which numbers to ask for.
Chart From AIplusInfo
Agents burn far more tokens than chat
Relative tokens consumed per interaction, with a single chat exchange set to 1x.
Source: Anthropic.
How to Implement an Agent Cost Governance Practice Step by Step
Turning to implementation, the sequence below takes a team from no visibility to enforced budgets in six steps. Each step produces something you can verify before moving on to the next one. Do the steps in order, because every later control depends on the tags and ledger created in the earlier ones. The examples use a LiteLLM-style gateway and Python, but the same pattern works with any gateway or provider SDK. Pro tip: start with one high-spend agent rather than the whole estate, and expand once its numbers reconcile with the invoice.
Step 1 - Inventory agents and assign owners
Begin by listing every agent that can spend money, including prototypes that someone left running and vendor agents that bill through a shared account. For each one, record a name, an accountable owner, a business purpose, the environment, and the models and tools it may use. This registry becomes the source of truth for tags, so the names in it must match the names your code sends on every call. Review it with finance within the first 5 working days so that each agent maps to a cost center that already exists in the general ledger. Pitfall to avoid: do not let two agents share one identifier, because their spend will merge and neither owner will recognize the total.
agents:
  - id: support-triage
    owner: [email protected]
    cost_center: CC-4410
    environment: prod
    allowed_models: [small-model, large-model]
  - id: research-assistant
    owner: [email protected]
    cost_center: CC-2250
    environment: prod
    allowed_models: [large-model]
Step 2 - Route every call through a gateway with required tags
Next, force all model traffic through a single gateway so that tagging and limits are applied in one place instead of in every application. Configure the gateway with the approved models and a global ceiling that resets every 30 days, and issue each agent its own virtual key. Reject any request that arrives without the metadata fields for team, agent, and environment. This turns attribution from a hope into a rule, and it gives you one choke point for later controls. Pro tip: block direct provider keys in your network policy so that teams cannot route around the gateway.
model_list:
  - model_name: small-model
    litellm_params:
      model: provider/small-model
  - model_name: large-model
    litellm_params:
      model: provider/large-model

litellm_settings:
  max_budget: 20000
  budget_duration: 30d
Step 3 - Record a cost ledger entry for every run
With traffic flowing through the gateway, add a ledger that stores 1 summary row per agent run. The row should include the trace and parent identifiers, agent, team, model, token counts by type, tool call count, duration, and a flag showing whether the task was resolved. Compute cost from a versioned price table rather than hard-coding rates, so historical rows can be restated when vendors change prices. The rates in the sample code are placeholders, not real vendor prices. Write the record even when the run fails or times out, since failed runs are exactly the ones that distort unit cost. Pitfall to avoid: skipping the outcome flag, because without it the ledger can only tell you what you spent and never what you got.
from dataclasses import dataclass, asdict
import json, time

PRICES = {"small-model": (0.25, 1.25), "large-model": (3.00, 15.00)}  # USD per million tokens

@dataclass
class RunRecord:
    trace_id: str
    agent: str
    team: str
    model: str
    input_tokens: int
    output_tokens: int
    tool_calls: int
    resolved: bool
    started_at: float

    def cost_usd(self) -> float:
        p_in, p_out = PRICES[self.model]
        return (self.input_tokens * p_in + self.output_tokens * p_out) / 1_000_000

def write_record(rec: RunRecord, sink) -> None:
    row = asdict(rec)
    row["cost_usd"] = round(rec.cost_usd(), 6)
    row["written_at"] = time.time()
    sink.write(json.dumps(row) + "\n")
Step 4 - Set hierarchical budgets and per-run caps
Now translate your observed distribution into limits at each level. Create a team budget with a 30-day reset, issue each agent a key with a smaller budget, and store the per-run cap in the agent's configuration. Base the numbers on the median and ninety-fifth percentile of cost per resolved task from your ledger, not on guesses. Enable the gateway's strict enforcement mode where available, so budget checks happen before each request rather than after the fact. Pro tip: give every key a short expiry and a rotation date so that forgotten prototypes eventually stop spending.
{
  "key_alias": "support-triage-prod",
  "team_id": "support-platform",
  "max_budget": 1500,
  "budget_duration": "30d",
  "metadata": {
    "agent": "support-triage",
    "cost_center": "CC-4410",
    "per_run_cap_usd": 0.60
  }
}
Step 5 - Add circuit breakers inside the agent loop
Budgets at the gateway protect the organization, yet the agent loop itself needs local brakes so a single run cannot burn its whole allowance. Track cumulative cost, step count, retries, and elapsed time inside the loop, and stop the run when any of the 4 limits is crossed. On a stop, return a clear partial result or escalate to a human with the context gathered so far. Keep these limits in configuration the agent cannot modify, since a model that can edit its own limits has no limits. Pitfall to avoid: counting only successful calls, because failed calls usually cost tokens too.
class RunBudgetExceeded(Exception):
    pass

class RunGuard:
    def __init__(self, max_usd=0.60, max_steps=25, max_retries=3, max_seconds=120):
        self.max_usd, self.max_steps = max_usd, max_steps
        self.max_retries, self.max_seconds = max_retries, max_seconds
        self.usd = self.steps = self.retries = 0
        self.started = time.time()

    def charge(self, usd: float, retried: bool = False) -> None:
        self.usd += usd
        self.steps += 1
        self.retries += 1 if retried else 0
        if self.usd > self.max_usd:
            raise RunBudgetExceeded("per-run cost cap reached")
        if self.steps > self.max_steps or self.retries > self.max_retries:
            raise RunBudgetExceeded("step or retry cap reached")
        if time.time() - self.started > self.max_seconds:
            raise RunBudgetExceeded("wall-clock cap reached")
Step 6 - Publish showback and review it every week
Finally, turn the ledger into a weekly showback report that every agent owner receives. The headline figures are cost per resolved task, success rate, tokens per resolved task, and the ninety-fifth percentile run cost, each compared with the previous week. Add a short list of the five most expensive runs with their traces so owners can see concrete causes. Hold a 30-minute review where owners explain changes and agree on one optimization to try next. After a few cycles, share the same report with finance and decide whether the data is trustworthy enough to move toward chargeback.
SELECT agent,
       team,
       SUM(cost_usd) AS total_usd,
       SUM(CASE WHEN resolved THEN 1 ELSE 0 END) AS resolved_tasks,
       SUM(cost_usd) / NULLIF(SUM(CASE WHEN resolved THEN 1 ELSE 0 END), 0) AS cost_per_resolved_task
FROM agent_runs
WHERE written_at >= CURRENT_DATE - INTERVAL '7 days'
GROUP BY agent, team
ORDER BY total_usd DESC;
Recommended by AIplusInfo
Books to go deeper on agent cost control
Hand-picked titles that map to the budgeting, attribution, and architecture topics covered above.
As an Amazon Associate, AIplusInfo earns from qualifying purchases.

Book
AI Engineering: Building Applications with Foundation Models
Covers evaluation, latency, and cost trade-offs for production AI systems, which are the same levers that govern agent spend.
Buy on Amazon
Book
Cloud FinOps: Collaborative, Real-Time Cloud Value Decision Making
The standard practitioner text on cloud financial management, whose showback, allocation, and unit economics ideas carry directly into agent cost governance.
Buy on Amazon
Book
Building Applications with AI Agents: Designing and Implementing Multiagent Systems
A practical guide to designing multiagent systems, useful for understanding where agent loops and orchestration create the token costs discussed here.
Buy on AmazonKey Insights
- Gartner predicts that over 40 percent of agentic AI projects will be canceled by end of 2027 as costs escalate and value stays unclear, so cost discipline is essential.
- Anthropic measured that agents use about four times more tokens than chat and multi-agent systems about fifteen times more, so multi-agent designs deserve a separate budget class.
- Gartner expects inference cost per agentic workflow to rise more than fivefold through 2028 even as token prices fall, so efficiency gains alone will not offset growing consumption.
- The State of FinOps 2026 survey found that 98 percent of 1,192 respondents now manage AI costs, up from 31 percent two years earlier, so the practice went mainstream.
- Anthropic prices cache reads at one tenth of the base input price on standard models, which makes prefix caching a high-return optimization for loops that resend long prompts every turn.
- OpenAI's Batch API offers a 50 percent discount for results returned within 24 hours, so deferrable agent jobs should be separated from interactive traffic.
- Salesforce moved Agentforce from $2 per conversation to $0.10 per action through Flex Credits, noting that 90 percent of CIOs say AI costs limit their ability to drive value.
- Intercom charges $0.99 per resolution for its Fin agent and nothing when Fin escalates to a human, turning a usage bill into a unit finance can compare with human handling.
Taken together, these figures describe a market where agents consume more tokens per task, vendors search for pricing units that match value, and buyers are rapidly building cost practices. The cancellation forecast shows that cost and value problems, not model capability, are what end many projects. Token multipliers explain why agent bills surprise teams that budgeted from chatbot experience, while the fivefold forecast shows the pressure will intensify through 2028. Caching and batching prove that real savings exist, but only for teams that measure outcomes so they can verify that quality held. The pricing moves at Salesforce and Intercom suggest the industry is converging on the same answer as FinOps practitioners, which is to price and budget by completed work.
| Dimension | Per-seat license | Consumption credits | Outcome-based fee | Raw token API |
|---|---|---|---|---|
| Cost predictability | High, fixed per user | Medium, depends on action volume | Medium, depends on resolution volume | Low, depends on loop behavior |
| Alignment with value | Weak, ignores usage | Moderate, tracks activity | Strong, tracks results | Weak, tracks tokens |
| Who carries usage risk | Vendor | Buyer | Shared | Buyer |
| Best suited for | Human-operated assistants | Autonomous multi-step agents | Well-defined, countable tasks | Custom-built agents |
| Attribution effort | Low, by named user | Medium, by action log | Low, by outcome report | High, needs gateway tags |
| Forecasting method | Headcount times price | Volume times credits per action | Expected outcomes times fee | Volume times cost distribution |
| Main failure mode | Paying for idle seats | Credit burn from retries | Disputes over what counts | Runaway loops and context bloat |
| Guardrail to demand | Fair-use policy | Spending caps and alerts | Monthly outcome limit | Per-run and per-key budgets |
Real Examples of Agent Spend Surprises and Fixes
Looking at documented cases, three examples show how agent cost behavior surprised builders, buyers, and vendors in different ways. Each one turns on the same lesson, which is that cost must be visible before it can be controlled. The examples are drawn from engineering write-ups and press coverage rather than from vendor marketing. They span a research agent built in-house, a coding tool that changed its billing, and a platform whose agents ran up customer bills. Read them as a checklist of failure modes to test against your own FinOps for agentic AI program.
Anthropic's Multi-Agent Research System
Anthropic built a multi-agent research system in which a lead agent plans a query and spawns parallel subagents to search and report back. The team measured token usage and found that agents typically use about 4 times more tokens than chat, while multi-agent systems use about 15 times more. In its evaluation on the BrowseComp benchmark, token usage alone explained roughly 80 percent of the variance in performance, which shows that spending tokens often buys better answers. That relationship forced a budgeting rule, because Anthropic states that multi-agent systems only make sense for tasks whose value is high enough to pay for the increased performance. The approach still has a clear limit, since domains that need shared context across agents or many dependencies between steps are poor candidates and become expensive without a quality gain. The full multi-agent research system write-up is a useful model for treating token allocation as a first-class design variable.
Cursor's Usage-Based Pricing Reset
Cursor rolled out new pricing on June 16, 2025, replacing a fixed allotment of fast requests with usage tied to the actual API cost of the models people chose. Many users were surprised by the new charges on their bills. The messaging did not make clear that unlimited usage applied only to the Auto model, not to every model on the Pro plan. On July 4 the company published an apology and committed to refunding any unexpected charges incurred over the previous 3 weeks. It also promised advance notice of pricing changes, clearer documentation, and dashboard improvements that show when users approach their limits. The episode shows that a pricing change can still damage trust when communication lags behind the economics, even if the underlying cost logic is sound. Cursor's own pricing apology post is a candid record of what a usage-based rollout needs in order to avoid bill shock.
Replit Agent 3 and Effort-Based Pricing
Replit adopted effort-based pricing in June 2025, bundling complex tasks into single checkpoints. It then launched Agent 3 on September 10, claiming it was ten times more cost-effective than computer-use models. Within days, users reported surprise bills, and one told reporters they spent $1,000 in a single week compared with a typical monthly cost of $180 to $200. Another user reported spending $70 in one night, and tasks on existing code bases were reported to cost $2 to $4 per action. Replit acknowledged that effort-based pricing can end up more expensive over the lifetime of a project. The reporting did not describe refunds or spending limits at the time, and the company had not yet answered questions, so the limit on what can be concluded is real. The Register's report on Replit pricing is a reminder that autonomous agents need visible spend controls before launch, not after complaints.
Case Studies in Agent Pricing and Spend Control
Beyond individual incidents, three longer cases show how organizations responded to cost pressure with pricing design and hard limits. The common thread is that each response replaced an open-ended expense with a bounded, countable unit. Two cases come from vendors designing prices for their customers, and one comes from a buyer containing its own spend. Together they show both sides of the FinOps conversation about agents. Each case lists the problem, the response, the measurable result, and the limits that remain.
Case Study: Salesforce Agentforce Moves From Conversations to Actions
Salesforce faced the problem that a flat $2 per conversation was a coarse unit for agents used across sales, service, and other workflows. In May 2025 it introduced Flex Credits as a solution, priced at $500 for 100,000 credits, with each agent action consuming 20 credits, or $0.10 per action. Enterprise Edition customers also received 100,000 Flex Credits at no cost through Salesforce Foundations, which lowered the barrier to experimentation. The company stated that 90 percent of CIOs say managing AI costs limits their ability to drive value. It presented the change as a way to align price with business outcomes. The shift gave buyers a smaller, more granular unit, and it made Agentforce usable for cases beyond customer service where a whole conversation was the wrong measure. A limit remains, because customers must now forecast the number of actions their agents will take. That moves forecasting risk to the buyer and rewards teams that already track actions per task, as the Salesforce pricing announcement makes clear in its description of the full model.
Case Study: Intercom Fin and Per-Resolution Pricing
Intercom faced the problem of finding a pricing unit for its Fin support agent that customers could compare directly with the cost of a human-handled conversation. The company adopted a model that charges $0.99 per outcome. An outcome counts when Fin successfully delivers value, such as an answer the customer confirms or a completed procedure like a refund. Fin does not charge when the customer asks for a human or when Fin cannot answer and escalates. Customers can also set a monthly outcome limit to control costs, which gives finance a built-in ceiling. This design ties the vendor's revenue to successful conversations, so the vendor shares the risk of failed runs that would otherwise fall on the buyer. The controversy lies in the definition, since an outcome depends on signals such as a customer who leaves satisfied, and teams should audit those counts against their own data. Intercom also notes that minimum commitments apply for standalone deployments on other helpdesks, which can reduce the benefit for small teams, as the Intercom pricing page explains.
Case Study: Uber's Per-Tool Token Caps for Coding Agents
Uber faced the problem that AI coding tools consumed far more tokens than its 2025 budget had assumed. Agentic coding grew popular only after the plan was written. According to Bloomberg reporting summarized by Simon Willison, the company's 2026 AI budget was exhausted within about four months. Uber introduced a solution that limits employees to $1,500 of monthly token spending per AI coding tool, with separate caps for tools such as Cursor and Claude Code. Willison calculates that two tools at that cap would allow $36,000 per employee annually, roughly 11 percent of a median engineer's pay of $330,000. The case shows how a per-tool, per-person cap turns an open-ended expense into a controlled one while still allowing heavy users to work. The details deserve caution, because the figures come from secondary summaries of press reporting, and Uber has not published how the caps are enforced or what happened to productivity. Teams can read Simon Willison's summary of the Uber caps alongside their own usage data before copying the number.
Frequently Asked Questions on FinOps for Agentic AI
FinOps for agentic AI manages the variable cost of autonomous agents, including tokens, tool calls, and compute. Classic cloud FinOps tracks resources that people provision, while agents decide at runtime how much to spend. That shift makes per-run tracking, request-level tagging, and enforced budgets essential. The core FinOps ideas of visibility, accountability, and optimization still apply, but the unit of analysis changes from instances to tasks.
Anthropic reports that agents typically use about four times more tokens than chat, and multi-agent systems about fifteen times more. Gartner adds that routing a task to an agentic reasoning model raises provider inference costs by at least five times. The exact multiple depends on loop length, context size, and retries. Measure your own agents instead of relying on a published ratio.
Cost per resolved task divides total agent spend over a period by the number of tasks the agent completed successfully. The numerator must include failed runs, retries, abandoned sessions, and the cost of human escalations. Record a resolved flag in every run record so the calculation is automatic. Track it alongside success rate so that a cheap but failing agent does not look efficient.
Start from your observed cost distribution, using the median and the ninety-fifth percentile of cost per resolved task. Set the per-run cap between those two values so that normal hard tasks finish and runaway runs stop. Layer team, agent, and key budgets above it with a monthly reset. Review all caps monthly because prompt, model, and tool changes shift the distribution.
The behavior should be decided in advance, not improvised during an incident. Common policies are to stop and escalate to a human, to fall back to a cheaper model, or to return a partial result with an explanation. Customer-facing agents usually need a graceful fallback because a hard stop can cost more than the overage. Internal batch agents can usually fail closed without harming anyone.
Route all model traffic through a gateway that requires metadata for team, product, agent, and environment on every request. Add provider-side tags where available, such as cost allocation tags on Amazon Bedrock application inference profiles. Store a trace identifier and a parent identifier so child calls roll up to the originating task. Document the allocation rule for shared costs such as vector databases and evaluation suites.
Start with showback, which reports spend to teams without moving money, until attribution coverage is high and trusted. Chargeback works best when teams have levers they can pull, such as choosing models or tightening caps. Many organizations settle on a hybrid, sharing platform costs as overhead and charging variable consumption. Keep internal rates stable for a quarter so teams can plan.
Yes, for agents that resend long, stable prefixes such as system prompts and tool definitions on every turn. Anthropic prices cache reads at one tenth of the base input price on standard models, with a 1.25 times premium for a five-minute cache write. The saving depends on hit rate, so monitor the ratio of cached to uncached input tokens. Always confirm that answer quality is unchanged after you enable it.
Routing makes sense when an agent performs steps of very different difficulty, such as classification, extraction, and final reasoning. Easy steps go to a small, cheap model, and only hard steps use the flagship model. Gartner recommends inference tiering and orchestration for exactly this reason. Validate each routing rule against an evaluation set, because a cheaper model that fails more often can raise cost per resolved task.
Seats are predictable but ignore usage, credits track activity but push forecasting risk onto the buyer, and outcome-based fees tie price to results. Intercom charges $0.99 per resolution for Fin, while Salesforce prices Agentforce at $0.10 per action through Flex Credits. Outcome pricing is attractive when the outcome is countable and the definition is clear. Always ask how the vendor defines an outcome or action.
Forecast with a range, not a single figure, by multiplying expected task volume by the observed distribution of cost per run. Add scenarios for adoption growth, task mix, model price changes, and context growth. Gartner expects inference cost per agentic workflow to rise more than fivefold through 2028, so do not assume falling token prices will lower your bill. Review the variance against actual spend every month without fail.
The biggest risks are retry storms, context explosions, unbounded multi-agent fan-out, and malicious prompts that trigger expensive tool calls. Each can turn a small inefficiency into a large bill because agents repeat actions at machine speed. Defend with per-run step and retry caps, rate limits, approval thresholds for costly actions, and alerts on spend rate. Also plan for vendor price changes that can invalidate a forecast overnight.
Ownership should be shared across teams but made explicit in writing. A FinOps lead or named AI cost owner coordinates the practice, and platform engineering runs the gateway and guardrails. Product teams own their agents' unit costs, and finance maintains rates and forecasts. The State of FinOps 2026 survey found that 98 percent of respondents now manage AI costs. Governance and security teams should review spending authority for agents.
Cost without quality is misleading, and quality without cost is incomplete. Pair cost per resolved task with success rate, escalation rate, and review outcomes so that every saving is verified against performance. A quality-adjusted unit cost compares spend with the outcomes that passed review. Publish both views in the same report so teams never optimize one at the expense of the other.