Context Development Lifecycle
Why it matters: Stop shipping untested prompts. Learn the context development lifecycle: generate, evaluate, distribute, and observe agent context, backed by real test data.
Model Context Protocol vs Function Calling: Differences and When to Use Each
Why it matters: MCP or function calling? Learn how each works, what tool definitions cost in tokens, and use our decision framework to pick the right layer for your agent.
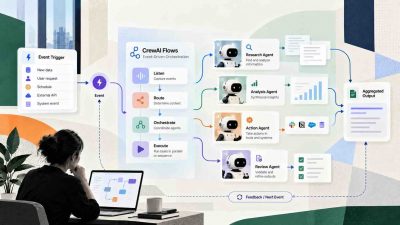
CrewAI Flows Event-Driven Agent Orchestration Explained
Why it matters: CrewAI Flows explained: how start, listen and router decorators turn improvising agents into deterministic, resumable workflows you can actually audit.
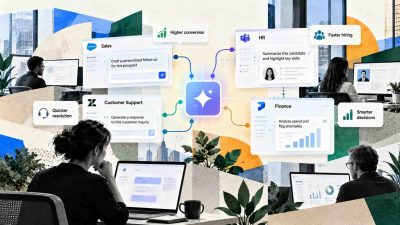
Embedded AI in Enterprise Software: What It Changes
Why it matters: Embedded AI is already inside your CRM and ERP: see what changes for governance, cost, and daily work before your next vendor renewal.
Google ADK 2.0 vs LangGraph for Multi-Agent Orchestration
Why it matters: ADK 2.0 or LangGraph? See which wins on state, human approval, cost, and risk, with side-by-side code, real case studies, and a decision framework.
Context Engineering for LLM Agents
Why it matters: Agents fail when their context fills with noise. Get the write, select, compress, isolate playbook, real token data, and a free planner to cut cost and errors.
Deterministic Guardrails for AI Agents
Why it matters: Prompts cannot contain an autonomous agent. See how deterministic guardrails for AI agents enforce tool limits at the gateway, cut risk, and survive an audit.
Function Calling in LLMs Explained
Why it matters: Function calling in LLMs, explained clearly: how models call tools, why strict schemas hit 100% reliability, and the security risks you cannot ignore.

Semantic Knowledge Graph for LLM Agents
Why it matters: See how a semantic knowledge graph for LLM agents slashes hallucinations, adds memory, and lifted answer accuracy from 17 to 54 percent in tests.
