Introduction
Choosing a tool layer for agents comes down to model context protocol vs function calling: differences and when to use each. The answer decides how every tool in your system is described, called, secured, and reused. Gartner predicts that forty percent of enterprise applications will be integrated with task-specific AI agents by the end of 2026, up from less than five percent in 2025. Every one of those agents needs a dependable way to reach calendars, databases, ticketing systems, and internal APIs. Two answers dominate the conversation: the function calling feature built into model APIs, and the open Model Context Protocol that Anthropic released in November 2024. Many teams treat them as rivals and spend weeks debating what is really a question about layers rather than brands. Function calling is how a model asks for work, while MCP is how tools are packaged so that many applications can ask for the same work. This guide separates the two ideas, compares them across cost, security, portability, and operations, and ends with a decision framework you can apply to your own stack.
Quick Answers on Model Context Protocol vs Function Calling
What is the difference between MCP and function calling?
Function calling lets a model request a tool, while MCP standardizes how tools are served. For model context protocol vs function calling: differences and when to use each, treat them as different layers, not rivals.
When should I use function calling instead of MCP?
Use function calling when one application, one team, and one model provider share a small set of tools. Fewer than about twenty functions rarely justify running separate servers.
When is MCP the better choice?
Choose MCP when several applications, teams, or model providers must reuse the same tools. It also fits cases that need central authentication, audit logs, and independently deployed integrations.
Key Takeaways
- Function calling is a model capability for emitting structured tool requests, while MCP is an open protocol that standardizes how tools are exposed, discovered, and executed.
- Small, single-provider agents with fewer than about twenty tools are usually best served by plain function calling and no extra servers.
- MCP pays off when tools are shared across applications, teams, or providers, and when security reviews demand central authentication and audit trails.
- Most mature systems use both layers together, and the real engineering work is managing token cost, trust boundaries, and tool sprawl.
Table of contents
- Introduction
- Quick Answers on Model Context Protocol vs Function Calling
- Key Takeaways
- What Is the Difference Between Model Context Protocol and Function Calling?
- Two Layers of One Stack: Where Each Idea Lives
- How Function Calling Works From Prompt to Result
- How Model Context Protocol Works Under the Hood
- Model Context Protocol Versus Function Calling on Seven Core Dimensions
- Token Cost and the Context Window Problem
- Portability, Lock-In, and the Standards Race
- Security and Trust Boundaries on Each Side
- Putting Both Approaches to Work in Code
- A Decision Framework for Choosing Between Them
- Hybrid Architectures That Combine Both Layers
- Latency, Reliability, and Operating Cost
- Ethics, Accountability, and Governance of Tool-Using Agents
- Industry Patterns in Model Context Protocol Adoption
- Common Mistakes and How Teams Migrate
- Risks That Remain on Both Sides
- The Future of Tool Use in AI Agents
- Key Insights
- Examples in Practice: Three Teams Putting Tool Protocols to Work
- Lessons From Three Production Incidents and Rollouts
- Frequently Asked Questions on Model Context Protocol vs Function Calling
What Is the Difference Between Model Context Protocol and Function Calling?
Function calling is a model capability that emits structured tool requests, while the Model Context Protocol is an open standard for exposing those tools. That is the core of model context protocol vs function calling: differences and when to use each.
An Interactive From AIplusInfo
Which Tool Layer Fits Your Agent?
Move the sliders to describe your agent and see whether plain function calling, MCP, or a hybrid fits, plus what tool definitions may cost in tokens.
12 tools
2 apps
1 provider
Low
Recommendation
Lean toward function calling
Fit score
Tool definitions per turn
0 tokens
With tool search: 0 tokens
Estimate calibrated to Anthropic’s measurement of about 55,000 tokens for 58 tools, and its 85 percent reduction with tool search. OpenAI suggests staying under about 20 active functions.
Two Layers of One Stack: Where Each Idea Lives
Building on that definition, the cleanest way to understand the pair is to place each one on a different layer of the same stack. Function calling lives at the model boundary, where a language model receives a list of tool schemas and decides whether to answer in plain text or return a structured request. The model never runs anything itself, because it only produces a tool name and a JSON object of arguments. Your code must interpret that output, run the real operation, and hand the result back. Everything about where the tool lives, who maintains it, and how it authenticates is outside the feature. That narrow scope is why function calling feels simple, and it is also why it says nothing about reuse.
The Model Context Protocol lives one layer further out, between the application that hosts the model and the systems that hold data and capabilities. According to the original Anthropic announcement, MCP is an open standard for connecting AI assistants to the systems where data lives, including content repositories, business tools, and development environments. Anthropic framed the problem plainly: every new data source previously required its own custom implementation. MCP replaces that fragmentation with one protocol that any compatible client and any compatible server can speak. Early adopters named in the announcement included Block and Apollo, with developer tools such as Zed, Replit, Codeium, and Sourcegraph working on integrations. The protocol therefore starts life as an integration standard rather than a model feature.
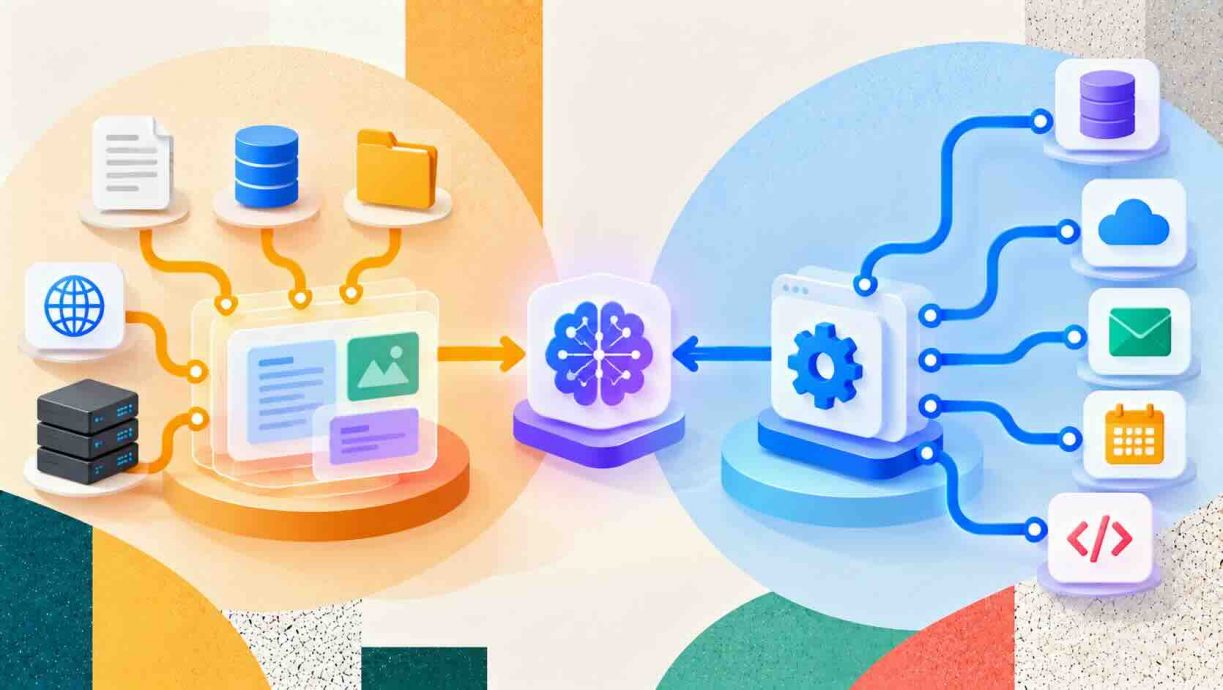
Seen together, the two ideas form a pipeline rather than a fork in the road, and our Model Context Protocol integration guide covers the protocol side in more depth. A host application uses an MCP client to ask a server which tools exist. It converts those descriptions into whatever tool schema its model provider expects and sends them to the model. The model then uses its function calling ability to pick a tool, and the host routes that request back through the MCP client to the server that performs the work. When people say MCP uses function calling, this routing is what they mean. When people say MCP replaces function calling, they have confused the transport of tools with the decision to call them. Function calling answers how a model signals intent, while MCP answers how tool code is packaged, discovered, and invoked across process and organization boundaries. Comparing them head to head is a bit like comparing a database driver with SQL, since they appear in the same stack and neither makes the other redundant.
How Function Calling Works From Prompt to Result
Shifting from the big picture to mechanics, function calling is a request and response loop in which your application, not the model, performs every real action. OpenAI introduced the feature in June 2023 for its gpt-4-0613 and gpt-3.5-turbo-0613 models, letting developers describe functions with JSON Schema so the model could return a JSON object of arguments. Today the same idea appears across providers under names such as tool use and tool calling, with small differences in field names and message shapes. Our own explainer on function calling in LLMs explained walks through the basics for readers who are new to the feature. The important point for this comparison is that the model proposes and your code disposes. That division of labor keeps the model in a sandbox and keeps all side effects in software you control.
The loop has five steps, and OpenAI's function calling guide lists them in this order. First, your application sends a request that includes the tools the model may call. Second, the model returns one or more tool calls with arguments. Third, your code executes the matching function with the arguments the model supplied, and fourth, you send the tool output back in a second request. Fifth, the model produces a final answer or asks for more tool calls, and the loop repeats until it is done. Each tool definition is a small contract made of a name, a description, and a JSON Schema for the parameters. The description matters most, because it is all the model sees when deciding whether a tool fits. Strict modes tighten the contract by forcing arguments to conform to the schema, and parallel calls let the model request several tools in a single turn.
Notice carefully what this request and response loop does not include. There is no discovery step, because you hand the model the full tool list on every request. There is no shared server, because the function body sits in your own process or service. There is no standard for authentication, because credentials simply live wherever your code lives. There is no registry, no versioning story, and no way for a second application to reuse the tool without copying it. These omissions are not flaws, since they are exactly why function calling is so fast to adopt, but they are also the reasons teams eventually look for something more structured.
The cost model of function calling follows directly from the same design. Tool definitions travel with every request and count toward input tokens, so a long list of tools becomes a recurring tax on every turn. OpenAI's guidance suggests keeping fewer than about twenty functions available at the start of a turn, or deferring rarely used tools through tool search. That recommendation is a useful anchor throughout this guide, because it marks the point where plain function calling starts to strain without help. A team with eight well-described tools is nowhere near that line, while a team with two hundred is far beyond it. Most real systems sit somewhere between, which is where the decision framework later in this article earns its keep.
How Model Context Protocol Works Under the Hood
Turning to the protocol side, MCP is a stateful JSON-RPC conversation between a client inside a host application and a server that offers capabilities. The MCP specification names three roles: hosts are the LLM applications that initiate connections, clients are connectors inside the host, and servers provide context and tools. Messages use JSON-RPC 2.0, connections are stateful, and both sides negotiate their capabilities when a session starts. The designers openly borrowed the idea from the Language Server Protocol, which solved a similar integration problem for code editors. Local servers typically run as child processes that talk over standard input and output, while remote servers use HTTP-based transports that support authentication and multi-user hosting. That is the practical reason MCP feels heavier than function calling on day one, because you now have a process or service to build, deploy, version, and monitor.
Servers can offer three distinct kinds of features to connected clients. Resources carry context and data for the user or the model, prompts are templated messages and workflows that users can invoke, and tools are functions the model can execute. Tools are the part of the protocol that overlaps with function calling. Clients can also offer several features back to servers in return. Sampling lets a server request a model completion, roots let a server ask about filesystem or URI boundaries, and elicitation lets a server ask the user for more information. A client sends a tools/list request to discover what the server offers. The tools section of the specification shows each tool carrying a name, a description, and an input schema written in JSON Schema. When the model chooses a tool, the client sends a tools/call request with the tool name and arguments, and the server replies with content blocks plus an error flag.
Several design choices set MCP apart from a plain tool list. Discovery happens at runtime, so a client can attach to a new server and immediately see what it can do. Servers can declare that their tool list may change and send a notification when it does, so clients refresh without restarting. Tool results can be structured, with optional output schemas that clients may validate before handing data to the model. Errors split into protocol errors for malformed requests and tool execution errors that the model can read and use to correct itself. The specification also states that there should always be a human in the loop with the ability to deny tool invocations. Together these features turn a simple list of functions into a managed integration surface, and the price is extra moving parts that function calling never asks you to run.
Model Context Protocol Versus Function Calling on Seven Core Dimensions
Stepping back from the mechanics, the two approaches differ most on seven dimensions. Those dimensions are definition location, tool discovery, code execution, portability, credential placement, context consumption, and operational workload. On definitions and discovery, function calling embeds the schema in each request and your application owns the list. MCP moves the schema to a server and lets any client ask for it. That is why Portkey's comparison credits MCP with runtime tool discovery and change notifications that plain function calling lacks. On execution, function calling runs inside the calling application, while MCP runs inside a server that can be deployed, scaled, and secured on its own. Anthropic's tool use documentation also shows a middle path, where an MCP connector lets the Messages API reach remote MCP servers without a separate client in your code. Seeing these dimensions side by side prevents the most common mistake, which is picking one approach on a single dimension such as setup speed.
On portability, function calling formats differ between providers in field names and message structure, so moving a tool set from one vendor to another means rewriting glue code. An MCP server describes its tools once and any compliant client translates them. On credentials, function calling usually keeps secrets in the application that makes the call, whereas MCP lets each server hold only the secrets for its own tools. That separation limits how much an attacker gains from compromising one component, although it creates a new thing to defend, which is the set of servers itself. On context and operations, the tradeoff between the two approaches flips. Function calling is lean for a handful of tools and expensive for hundreds. MCP makes it easy to attach many servers and so reach that scale quickly, even though its architecture also enables fixes such as tool search. Operationally, function calling asks only for code in your existing service, while MCP asks you to run extra infrastructure and to govern which servers are allowed at all.
Token Cost and the Context Window Problem
Zooming in on cost, the most underestimated difference between the two approaches is how many tokens tool definitions consume before the user has typed a word. Anthropic's engineering team reported in its advanced tool use write-up that a five-server MCP setup with 58 tools used about 55,000 tokens before any conversation began. Internally, the team saw tool definitions reach 134,000 tokens before optimization. Those numbers are not unique to MCP, since any long tool list in plain function calling has the same effect. MCP simply makes it easy to attach many servers and reach that scale quickly. Anyone who has connected five or six servers to a coding assistant has probably felt the slowdown.
The cost of long tool lists shows up in three distinct places. Latency rises because the model must read a longer prompt on every turn. Spend rises because those definition tokens are billed as input each time unless caching absorbs them. Accuracy falls because a model choosing among hundreds of similar tools picks the wrong one more often. That is a form of the attention problem discussed in context engineering for LLM agents. Tool descriptions that overlap in meaning make the problem worse, since the model has to separate near-duplicates using only a sentence or two of text. Teams that audit tool descriptions often find that pruning and rewording them improves accuracy as much as any model upgrade.
The industry has responded with patterns that keep the protocol but change how definitions reach the model. Tool search lets the model discover relevant tools on demand instead of loading all of them. Anthropic reports that its tool search tool cut a roughly 77,000 token baseline to about 8,700 tokens. Programmatic tool calling lets the model write code that orchestrates many calls, so intermediate results never enter the context window. These techniques sit on top of both function calling and MCP, which is another reminder that the two are complementary rather than competing. The practical rule for teams today is to count tokens, not tools, because a dozen terse tools can cost less than three sprawling ones. Measure the definition payload with your real provider, track it as a budget, and treat a rising number as a design smell. If you cannot shrink it, defer rarely used tools behind search or move heavy orchestration into code that the model writes.
Portability, Lock-In, and the Standards Race
Looking at strategy rather than syntax, the strongest argument for MCP is portability across models and applications. The strongest argument for function calling is that it commits you to nothing beyond your own code. A tool written against one provider's function calling format has to be re-expressed for another provider, and the differences, though small, make migrations tedious. When an organization expects to switch models, run several in parallel, or let teams choose their own assistants, a neutral protocol helps. It reduces the number of integrations from a product of models and tools to a sum. With M applications and N tools, point-to-point integration needs up to M times N connectors, while a shared protocol needs M clients and N servers. Real organizations rarely hit the theoretical extremes, but a modest estate of four assistants and thirty internal systems turns one hundred twenty custom adapters into thirty-four components. The saving only materializes if the protocol is widely supported, which is why governance and adoption matter as much as the technical design.
Governance moved quickly in late 2025, when Anthropic, Block, and OpenAI co-founded the Agentic AI Foundation. MCP became one of its anchor projects, with support from Google, Microsoft, AWS, Cloudflare, and Bloomberg. A neutral home reduces the risk that a single vendor changes the protocol for its own advantage, and it signals that rival model providers intend to keep supporting it. Lock-in worries do not vanish, because you can still be locked into a gateway, a registry product, or an agent platform. That risk is explored in vendor lock-in in agentic platforms. Agent SDKs from model vendors increasingly ship built-in MCP clients, which blurs the boundary for developers who never touch the wire format. The sensible stance is to keep tool logic behind a thin interface you control, with schema and transport treated as adapters. Then moving between native function calling, MCP, or a different framework costs days instead of quarters.
Security and Trust Boundaries on Each Side
Moving on to risk, plain function calling inherits the security posture of the application that hosts it. MCP adds a second set of parties whose code and descriptions you must learn to distrust. With function calling, the model's output is untrusted input to your code, just as a form submission from a browser would be. Your handlers must validate every argument, enforce authorization for the real end user, and refuse operations the user could not perform directly. Credentials usually sit inside the same service that runs the handlers, so one compromised component can expose every tool. Prompt injection is the standard route to misuse, since text in a web page or a document can persuade the model to request an action its operator never intended. Our guide to prompt injection attacks and defenses covers that class of problem in detail.
MCP widens the attack surface in several different directions at the same time. A server is a program written by someone, running somewhere, advertising tool descriptions that your model will read as trusted instructions. The specification itself says that descriptions of tool behavior should be considered untrusted unless they come from a trusted server. The Cloud Security Alliance notes in its research note on tool poisoning that the protocol does not require clients to validate them. The same note cites a 36.5 percent average tool-poisoning success rate across 20 language models tested on 353 tools from 45 live servers. It also describes CVE-2025-54135, a Cursor flaw rated 8.6 on the CVSS scale, and four agentic coding command line tools that auto-executed project-defined servers after a single trust prompt. These are not exotic lab attacks, because they exploit the ordinary fact that an assistant reads whatever a connected server tells it.
MCP also offers genuine security advantages when it is deployed with care. Each server can hold only the credentials needed for its own tools, so a breach in the calendar integration does not hand over the billing system. Remote servers can use standard authorization flows such as OAuth, which lets an agent act with the permissions of the signed-in user instead of a shared service account. Because every call passes through a defined protocol boundary, a gateway can authenticate, rate limit, and log traffic without changing the tools themselves. Central registries make it possible to keep an allowlist of approved servers, which is difficult to do when tools are scattered across dozens of codebases as hard-coded functions.
The practical controls are the same few ideas applied consistently. Require explicit user approval for anything that writes, sends, spends, or deletes, and show the arguments before the call runs. Pin server versions, review configuration changes the way you review code, and treat every new server as third-party software. Run local servers in containers or virtual machines without host credentials, and issue short-lived, per-session tokens wherever possible. Scan tool descriptions for hidden directives before deployment, and log every call so that an investigation has something to read. None of these controls is specific to one approach, but MCP makes them mandatory rather than optional.
Putting Both Approaches to Work in Code
On top of the theory, seeing the same tool built both ways is the fastest route to an intuition for what each layer adds. The scenario is a customer support assistant that looks up the shipping status of an order. In plain function calling, you describe the tool with a name, a plain language description, and a JSON Schema for its parameters. You then pass that description to the model on every request. Strict mode and a closed property list keep the arguments tidy. The schema below follows the shape used by OpenAI and similar providers, though exact field names vary by vendor.
{
  "type": "function",
  "name": "get_order_status",
  "description": "Look up the shipping status of a customer order by its order number.",
  "parameters": {
    "type": "object",
    "properties": {
      "order_id": {"type": "string", "description": "Order number such as A-10293"}
    },
    "required": ["order_id"],
    "additionalProperties": false
  },
  "strict": true
}
Your application owns the loop that surrounds that schema, and the loop is short. It sends the conversation and the tool list to the model and then checks whether the reply contains tool calls. For each call it runs the matching handler and appends the result to the conversation. Then it asks the model to continue until a reply arrives with no tool calls. The sketch below is provider-neutral pseudocode, so the client call and message field names will differ in your SDK. The handler table lives in your own process, which is why this approach needs no extra infrastructure and also why nothing else can reuse the tool.
import json

HANDLERS = {"get_order_status": get_order_status}

def run_agent(llm, messages, tools):
    while True:
        reply = llm.chat(messages, tools=tools)
        calls = reply.tool_calls
        if not calls:
            return reply.text
        messages.append(reply.as_message())
        for call in calls:
            handler = HANDLERS[call.name]
            result = handler(**json.loads(call.arguments))
            messages.append({"role": "tool", "id": call.id, "content": json.dumps(result)})
The MCP version moves the function body into a server that any compliant client can attach to. The official Python SDK lets you decorate an ordinary function and expose it as a tool, with the schema inferred from the type hints and the docstring. Developers who want a broader picture of how this plays out in daily coding work can read AI and the MCP developer workflow. Notice that the function body is identical to the one in the first example. Only the packaging changes, and the packaging is exactly what buys you reuse, isolation, and runtime discovery.
from mcp.server import MCPServer

mcp = MCPServer("Orders")

@mcp.tool()
def get_order_status(order_id: str) -> dict:
    """Look up the shipping status of a customer order by its order number."""
    return {"order_id": order_id, "status": "shipped", "eta": "2026-10-18"}

# Run with the SDK's command line tool, for example: mcp run server.py
Once the server is running, any client can ask what it offers and call it. The messages below follow the shapes defined in the specification. The client sends a tools/list request and receives the schema in reply. Later it sends a tools/call request carrying the arguments the model chose. The server answers with content blocks and a flag that says whether the call failed. The host application then converts the discovered schema into whatever tool format its model provider expects, which is the bridge shown in the hybrid section later in this guide.
{"jsonrpc": "2.0", "id": 1, "method": "tools/list"}

{"jsonrpc": "2.0", "id": 2, "method": "tools/call",
 "params": {"name": "get_order_status", "arguments": {"order_id": "A-10293"}}}
A Decision Framework for Choosing Between Them
Given the differences so far, the most reliable way to choose is to score your own situation against eight signals rather than to follow a slogan. Applying model context protocol vs function calling: differences and when to use each to a real project starts with a handful of honest questions about scale, ownership, and risk. The table below turns those questions into lean-left or lean-right signals, with thresholds drawn from published guidance. Portkey's decision guidance suggests function calling alone for fewer than five tools in one application, and MCP once you reach roughly ten tools or multiple teams. OpenAI's own documentation puts the comfortable limit for a single request at about twenty functions.
| Signal | Lean toward function calling | Lean toward MCP | Rule of thumb |
|---|---|---|---|
| Number of tools | Fewer than about 10 | 10 to several hundred | OpenAI suggests staying under roughly 20 active functions per turn |
| Applications reusing the tools | One application | Two or more applications or teams | Reuse is the main economic argument for a server |
| Model providers in use | One provider | Several providers or planned switching | A neutral protocol removes per-vendor glue code |
| Tool ownership | Same team writes tools and agent | Different teams or outside vendors own tools | Separate owners need a contract between them |
| Credential and audit needs | Internal prototype, low-risk data | Regulated data, per-user permissions, audit trail | Isolated credentials and central logs favor servers |
| Latency sensitivity | Tight loops where each hop matters | Interactive tasks that tolerate a network hop | In-process calls avoid a process or network boundary |
| Tool churn | Stable list that changes with releases | Tools that appear or change at runtime | Runtime discovery needs list-changed notifications |
| Operations capacity | No appetite for extra services | A platform team can run and govern servers | Every server is software you deploy and patch |
Reading the table is mostly a matter of counting the rows. If most rows point left, build the tools as plain functions behind a thin interface and ship. If most rows point right, invest in servers, a registry, and gateway controls from the start, because retrofitting governance later is far more painful. A mixed result is common and usually means the hybrid pattern in the next section is the right answer. Cost belongs in the same conversation, since long tool lists multiply input tokens on every turn. Prompt caching to cut LLM costs can absorb part of that bill when definitions stay stable. Treat the thresholds as starting points to be tested with your own measurements, not as laws.
Hybrid Architectures That Combine Both Layers
From there, the pattern most mature systems converge on is a host application that speaks MCP outward and function calling inward. The host keeps one or more MCP clients that connect to internal and external servers. It asks each for its tool list and translates the results into the tool schema its model provider expects. The model sees an ordinary list of functions and responds with ordinary tool calls. The host maps each call back to the right server, so the model never needs to know that a protocol exists. A few latency-critical or security-critical tools can still run as in-process functions beside the MCP-backed ones.
The translation layer is small, which is part of why the hybrid works so well. The sketch below converts one discovered MCP tool into a function definition, copying the name, the description, and the input schema. Real implementations also namespace tool names by server to prevent collisions. They cache the tool list until a change notification arrives. They also filter the list per user, so the model only sees tools that user may invoke. Those three habits solve most of the practical problems teams hit when they first attach several servers to one assistant.
def mcp_tool_to_function(tool):
    return {
        "type": "function",
        "name": tool["name"],
        "description": tool.get("description", ""),
        "parameters": tool["inputSchema"],
    }
Agent frameworks now package this hybrid pattern for you out of the box. The comparison of Google ADK against LangGraph orchestration shows how orchestration libraries wrap tool access. The Microsoft Agent Framework versus OpenAI Agents SDK comparison does the same for two vendor SDKs. Using a framework saves time, but it also hides the decisions this article describes, such as token budgets and trust boundaries. Whatever you choose, keep a short written record of which tools are native, which come through MCP, and why. That record becomes the backbone of your security review and your cost model.
Latency, Reliability, and Operating Cost
In practice, MCP adds a hop that plain function calling avoids, and whether that hop matters depends on the work the tool performs. A local server speaking over standard input and output adds little more than process communication, while a remote server adds a network round trip plus authentication. For tools that already call an external API, the extra hop is usually small compared with the API call itself. For tight loops that call dozens of cheap functions, in-process execution is clearly faster. The right comparison is therefore not protocol against protocol but end-to-end turn time for the tasks your users actually run.
Reliability is mostly a property of the model, not of the transport. The Berkeley Function Calling Leaderboard evaluates how accurately language models call functions, and its four versions progress from syntax checks through enterprise functions and multi-turn interactions to holistic agentic evaluation. That progression mirrors production experience, where a model that picks the right tool in a demo still stumbles on long conversations with many similar tools. The specification adds operational advice of its own: clients should implement timeouts, validate results, and log tool usage for audit. Operating cost splits into tokens, compute, and people, and tokens depend on how many definitions you load regardless of protocol. People cost is the real difference, because a native function is code in a service you already maintain while a server is a product with versions, dashboards, and on-call duties. Deterministic checks around tool calls, such as those in deterministic guardrails for AI agents, reduce reliability incidents under both approaches. Add such checks early, before the first production incident forces the issue.
Ethics, Accountability, and Governance of Tool-Using Agents
Beyond engineering, a tool-using agent turns a model's words into real-world actions, so accountability has to be designed in rather than assumed. The underlying ethical question is simple to state, even though the answers are not. When an agent sends an email, moves money, or changes a record, who consented, and how can a harmed person find out what happened? OpenAI's launch post for function calling was published on June 13, 2023. It already advised consuming information only from trusted tools and adding user confirmation before actions with real-world impact, such as sending email or making a purchase. It also noted that a proof-of-concept exploit showed untrusted tool output could push a model into unintended actions. Those warnings are as relevant today as they were at launch.
MCP builds some of this concern into its core design vocabulary. The specification lists principles of user consent and control, data privacy, tool safety, and limits on model sampling. It says hosts must obtain explicit consent before exposing user data to servers or invoking any tool. The protocol cannot enforce those principles itself, so the burden falls on implementers to build consent screens, permission scopes, and review flows. That is a governance task as much as a coding task, and it benefits from the kind of structure described in a practical framework for securing agentic AI. Organizations that skip it often discover the gap only after an incident.
Three governance habits apply equally to both of these approaches. First, assign every tool an owner who answers for its behavior, its data access, and its change history. Second, record each call with the user, the arguments, and the outcome so that decisions can be reconstructed and challenged. Third, publish plain language descriptions of what each agent can and cannot do, so the people affected know where the boundaries are. Fairness concerns also arise indirectly, because an agent that reaches only some systems may serve some customers better than others. Treat those disparities as design questions to be examined, not as accidents of integration.
Industry Patterns in Model Context Protocol Adoption
Looking across industries, adoption follows the shape of the tool estate: sprawling estates gravitate toward MCP, while focused products stay with function calling. Developer tools were the first large cluster, since editors and coding assistants need to reach repositories, terminals, documentation, and issue trackers, and a shared protocol let each vendor reuse integrations. Enterprise platform teams followed, wrapping internal data systems behind servers so many assistants could reach them under common controls. By late 2025 the project reported more than 97 million monthly SDK downloads and 10,000 active servers, and Descope's comparison counted over eleven thousand servers on one public marketplace. Those counts include many hobby projects, but they show how quickly the ecosystem formed after the protocol's November 2024 debut.
Function calling remains the default wherever the tool list is short and stable. Customer support bots with a handful of lookups rarely need a protocol layer. The same is true of data extraction pipelines that use a function schema to force structured output. Mobile and embedded apps with a fixed set of device actions also tend to stay native. Regulated sectors such as finance and healthcare tend to split the difference. They keep a few high-risk actions as tightly audited native functions and place broader read-only access behind servers and gateways. Coverage of how vendors are racing to support the standard appears in MCP gaining momentum across vendors, which tracks the trend from the news side.
Common Mistakes and How Teams Migrate
Despite the clean diagrams, most failed tool integrations stem from a handful of repeated mistakes rather than from the choice of protocol. The most common is wrapping every endpoint of a large REST API as its own tool, which floods the context window with near-duplicate definitions and leaves the model guessing. A second is writing vague descriptions, since the description is the only documentation the model reads. A third is returning enormous tool outputs that crowd out the conversation, a failure related to the effects described in context rot in large language models. A fourth is trusting third-party servers without review, and a fifth is building a server for a one-off script that will never be reused.
Teams also stumble by treating the initial choice as permanent. Because tool logic should live in ordinary functions behind a thin interface, moving from native calling to MCP, or back, is a packaging exercise rather than a rewrite. Teams that need fresh reference material for those tools can look at coding agents reading live API docs, which shows how documentation access itself becomes a tool. A sound migration plan keeps the function body unchanged and extracts it behind a server. It then runs both paths in parallel on a slice of traffic and compares accuracy, latency, and cost before switching over. Rolling back should stay one configuration change away until the new path has earned trust.
Several smaller disciplines prevent most of the day-to-day pain teams feel. Version your tool schemas and announce breaking changes, because models and clients cache assumptions about them. Namespace tool names by domain so that two servers can both offer a search tool without collision. Cap result sizes and paginate, since a tool that can return a million rows eventually will. Test with adversarial inputs, including descriptions that contain instructions, and keep an inventory of every server and tool in production. Teams that keep this inventory find that half of their problems disappear simply because they can finally see what the agent can reach.
A final migration lesson concerns measurement before and after the change. Before changing anything, record a baseline of task success rate, turn latency, tokens per task, and error rate for a representative set of prompts. After the change, rerun the same set and compare, because intuition about tool behavior is wrong surprisingly often. Teams regularly find that a tidy rewrite reduced accuracy because descriptions were shortened too far, or that a new server added more latency than the savings justified. Numbers settle those arguments quickly, and they give the next architectural debate something concrete to start from.
Risks That Remain on Both Sides
Rounding out the analysis, no choice between the two approaches eliminates the central risk, which is that a model will act on text it should not trust. Published research on tool poisoning makes this point especially sharply. The MCPTox benchmark, described in its arXiv paper, built 1,348 malicious test cases against 45 real MCP servers and 353 authentic tools and evaluated 20 language model agents. The highest attack success rate reached 72.8 percent, and the highest refusal rate stayed under 3 percent. The authors also found that more capable models were often more susceptible, because the attacks exploit stronger instruction following.
Other risks sit much closer to ordinary software engineering practice. The protocol and its SDKs are evolving quickly, so code written against one revision may need migration work for the next. Servers from the open ecosystem vary widely in quality, and some of the most popular ones have carried serious vulnerabilities. Token overhead can quietly erode both cost and accuracy as tool lists grow. Vendor comparisons, including several cited here, often come from companies that sell MCP infrastructure, so their security and scalability claims deserve scrutiny where they are design arguments instead of measurements. Benchmarks help but do not capture your workflow, so build a small evaluation set of your own.
Residual risk is best handled by layering defenses rather than searching for a perfect one. Keep humans in the loop for consequential actions and restrict each agent to the narrowest set of tools that does the job. Validate arguments and results in code the model cannot influence. Monitor for anomalies such as unusual call volumes or unexpected destinations. Plan for incident response before you need it, including a way to disable a server or tool quickly. These measures do not make an agent safe by themselves, but together they make failures smaller, rarer, and easier to diagnose.
The Future of Tool Use in AI Agents
Looking ahead, the two layers are converging toward a stack in which protocols standardize access while models and runtimes decide how much of it to load. Anthropic's engineering team described in its code execution with MCP article how presenting MCP servers as code APIs changed the economics. In one task, the approach reduced usage from 150,000 tokens to 2,000 tokens, a saving of 98.7 percent. The idea is that the model writes code that calls tools, so only the results that matter ever enter the context window. Cloudflare reached a similar result for its own API, and both approaches suggest that the token objection to MCP will shrink as tooling matures. Function calling will keep improving in parallel, with stricter schemas, deferred loading, and better multi-turn accuracy.
Adoption forecasts for agents point in the same general direction. With forecasts of rapid agent growth in enterprise software, the number of tools an organization exposes to models will rise, and so will the pressure for consistent governance. Our roundup of agentic AI adoption statistics for 2026 tracks how quickly organizations are moving from pilots to production. The likely outcome is not a single winner but a division of labor. Function calling remains the universal way a model signals intent, MCP becomes the common way tools are published and governed, and code execution becomes the efficient way to chain calls. Teams that design for that division of labor today will find the next generation of tools easy to adopt. The decision framework above is meant to age well for the same reason. Any answer to model context protocol vs function calling: differences and when to use each should depend on your constraints, not on a vendor's roadmap.
Chart From AIplusInfo
How Much Context Do Tool Optimizations Save?
Tokens of tool definitions or intermediate data before and after each technique, with every row scaled to its own baseline.
Source: Anthropic Engineering, advanced tool use; Anthropic Engineering, code execution with MCP; Cloudflare, Code Mode for MCP. Reduction for tool search is computed from the reported 77,000 and 8,700 token figures.
Key Insights
- The protocol reported over 97 million monthly SDK downloads and 10,000 active servers in December 2025, according to the Agentic AI Foundation announcement, so MCP is mainstream infrastructure.
- A five-server MCP setup with 58 tools consumed about 55,000 tokens before any conversation started, Anthropic's engineers reported, so tool definitions are a real recurring cost.
- Anthropic's tool search cut a 77,000 token baseline to roughly 8,700 tokens, and its tests lifted Opus 4 accuracy on MCP evaluations from 49 to 74 percent.
- Cloudflare's Code Mode shrank an MCP server covering more than 2,500 API endpoints from about 1.17 million tokens to roughly 1,000, a 99.9 percent reduction in input tokens.
- The MCPTox benchmark found poisoning attacks succeeded up to 72.8 percent of the time across 20 agents, and the paper notes that capable models were often more susceptible.
- Gartner expects task-specific AI agents in forty percent of enterprise applications by the end of 2026, up from under five percent in 2025, so tool counts will climb.
- OpenAI's function calling guide recommends keeping fewer than about twenty functions available at the start of a turn, or deferring rarely used tools through tool search.
- Pinterest reported 66,000 MCP tool invocations per month across 844 active users and about 7,000 hours saved monthly, though its engineers call those savings a directional estimate from owners.
Taken together, these figures describe a protocol that won the integration argument and a cost problem that is still being solved. Adoption numbers show that MCP is no longer optional knowledge for anyone building agents, while the token measurements show that attaching many servers carries a price. The security results explain why governance cannot be an afterthought, since attack success rates are high and capable models are not immune. Meanwhile, vendor guidance such as OpenAI's twenty-function guideline gives teams a concrete number to design against. The practical conclusion is that function calling and MCP are partners, with the right mix set by tool count, reuse, and risk. Teams that measure their own token overhead and trust boundaries will choose well, regardless of which label wins the headlines.
| Dimension | Function calling | Model Context Protocol | Hybrid |
|---|---|---|---|
| What it is | A model capability that returns structured tool requests | An open client-server protocol for exposing tools, resources, and prompts | MCP outward, function calling inward |
| Where definitions live | In each request, owned by the application | On the server, fetched by any client at runtime | On servers, translated into request schemas by the host |
| Discovery | None; the application hands over the list | tools/list plus change notifications | Host discovers, model sees a plain list |
| Where code executes | Inside the calling application | Inside an independently deployed server | Critical tools in process, shared tools on servers |
| Portability across providers | Schemas and message shapes differ by vendor | One server description works with any compliant client | Portability where it pays, speed where it matters |
| Credentials and trust boundary | Secrets live with the application | Each server holds only its own secrets, but servers are new attack surface | Per-server secrets with gateway policy in front |
| Context window cost | Grows with every definition you send | Grows faster when many servers attach, unless search or code execution is used | Budgeted per tool, with deferral for rare tools |
| Operational effort | Code in an existing service | Servers, registries, and governance to run | Moderate, concentrated in the host and gateway |
| Best fit | Small, single-provider, single-team agents | Shared tools across teams, apps, and providers | Most production systems at scale |
Examples in Practice: Three Teams Putting Tool Protocols to Work
Cloudflare's Code Mode for a 2,500-Endpoint API
Among the clearest demonstrations of server-side optimization, Cloudflare built an MCP server for its entire API that exposes only two tools, search and execute. The model writes JavaScript to filter the OpenAPI specification and then to call the endpoints it needs, so the full specification never enters the context window. According to Cloudflare's engineering post, a conventional MCP server covering more than 2,500 endpoints would need about 1.17 million tokens of definitions. Code Mode uses roughly 1,000, a reduction of 99.9 percent. Generated code runs in a sandboxed isolate with no file system or environment variables, and the server uses OAuth 2.1 so the agent receives only the permissions the user approves. The trade-off is that the model must write correct code against an API specification, and the sandbox limits what that code can reach. Teams still need monitoring and review, and the design moves complexity into the server, which is a drawback for small teams without platform engineers.
Pinterest's Internal MCP Registry
Shifting to internal platforms, Pinterest deployed several domain-specific MCP servers for systems such as Presto, Spark, and Airflow instead of one monolithic server. A central registry acts as the source of truth for approved servers, with a web interface for people and an API for AI clients and authorization checks. Every server needs an owning team and security review, and end-user tokens are validated at the network edge with finer-grained policies per tool. Agents must obtain human approval before sensitive actions, and elicitation is used to confirm dangerous ones. Pinterest's engineers reported 66,000 invocations per month across 844 monthly active users, with roughly 7,000 hours saved per month. Those savings come from owner estimates, which the post itself calls a directional signal, and it does not disclose server counts, costs, or failure rates. The limitation matters because the numbers show adoption and perceived value but not a controlled comparison against simple function calling.
Anthropic's Tool Search and Programmatic Calling
Looking at the model-provider side, Anthropic built a tool search tool and programmatic tool calling to tame large tool sets. Before optimization, a five-server setup with 58 tools used about 55,000 tokens, and internal tool definitions had reached 134,000 tokens. Using tool search, the traditional 77,000 token baseline fell to about 8,700 tokens. Accuracy on MCP evaluations rose from 49 to 74 percent for Opus 4 and from 79.5 to 88.1 percent for Opus 4.5. Programmatic tool calling cut average usage on complex research tasks from 43,588 to 27,297 tokens, a 37 percent reduction. Anthropic's engineering write-up presents these as results from its own internal evaluations. That is a real limit, since results on your workload may differ and the techniques depend on supported models, sandboxed code execution, and ongoing monitoring.
Recommended by AIplusInfo
Books to go deeper on agents and tool use
Hand-picked titles that connect to the tool layers, trust boundaries, and agent designs discussed above.
As an Amazon Associate, AIplusInfo earns from qualifying purchases.

Book
AI Engineering: Building Applications with Foundation Models
Covers agents, tool use, evaluation, latency, and cost trade-offs that decide how you wire tools into model applications.
Buy on Amazon
Book
Building Applications with AI Agents: Designing and Implementing Multiagent Systems
A practical guide to designing agents that call tools and coordinate with each other, which is where this tool-layer choice matters most.
Buy on Amazon
Book
Hands-On Large Language Models: Language Understanding and Generation
A visual, code-first grounding in how language models work, useful background before deciding how they should call and trust tools.
Buy on AmazonLessons From Three Production Incidents and Rollouts
Case Study: Asana's MCP Server Data Exposure
Asana launched an MCP server on May 1, 2025, aiming to connect customers' AI assistants to their work data. The server was meant to let AI assistants read and summarize project data on behalf of signed-in users. The problem surfaced on June 4, 2025, when the company discovered a bug that could let one organization's users see data belonging to another. Asana described it as a logic flaw in the MCP system and not the result of a hack, and it said roughly 1,000 customers were affected. The exposure window stretched from the launch until the server returned to normal operation on June 17, a span of about seven weeks that included 13 days after discovery.
The company's response was to take the MCP server offline and notify each impacted organization with a communication form. Administrators were told to review Asana logs for MCP access and check AI-generated summaries and answers for data that looked foreign. They were also advised to restrict LLM integrations until trust was re-established, according to BleepingComputer's report. The episode is controversial mainly because the flaw was ordinary tenant isolation, not an exotic AI attack, which means function calling would have been just as exposed. It shows that a new integration surface multiplies the places where authorization logic can fail. Teams should still test cross-tenant isolation explicitly before exposing any server to production data.
Case Study: The mcp-remote Command Injection Flaw
The mcp-remote package let local MCP clients reach remote servers, and developers had downloaded it more than 437,000 times when the problem came to light. JFrog's research team found that a malicious server could embed a command in the initial connection and authorization phase, which the client would then execute on the host operating system. The flaw, tracked as CVE-2025-6514 and scored 9.6 out of 10 on the CVSS scale, affected versions 0.0.5 through 0.1.15. On Windows the attacker gained arbitrary operating system commands with full control of parameters, while macOS and Linux allowed arbitrary executables with limited parameter control. The researcher who reported it described the result as full system compromise.
The maintainers introduced a fix in version 0.1.16, released on June 17, 2025. The recommended mitigations were to update promptly and connect only to trusted servers over HTTPS, as The Hacker News reported. With nearly half a million downloads, the exposure was broad, though not every install was reachable by an attacker. The lasting concern is that clients implicitly trust the servers they connect to, and a single malicious endpoint can become a path to the developer's machine. Plain function calling has no equivalent flaw in this exact place only because it has no such connection phase, and it carries its own risks in the handlers you write. Pinning versions and keeping an inventory of connected servers remain the strongest defenses.
Case Study: Tool Poisoning and the Cursor CurXecute Flaw
The challenge in this case is that a model reads tool descriptions as instructions, and a hostile description can steer it. The Cloud Security Alliance summarizes research in which the average tool-poisoning success rate was 36.5 percent. Those tests covered 20 models and 353 tools from 45 live servers, with a peak of 72.8 percent. In the same note, CVE-2025-54135, nicknamed CurXecute and rated 8.6 on CVSS, affected Cursor versions before 1.3. A related issue showed that approving a server by name rather than by contents let a repository attacker swap in a malicious command later. A poisoned calculator tool exfiltrated an SSH private key while the developer saw only an ordinary arithmetic result. Four agentic coding command line tools also auto-executed project-defined servers after a single folder trust prompt.
The solution set recommended in the Cloud Security Alliance note is layered. Patch affected tools, inventory every server against an allowlist, treat configuration changes as code review, scan descriptions for embedded directives, and isolate server processes without host credentials. The note also urges explicit approval in headless continuous integration runs, where trust dialogs may be skipped entirely. A limitation of the evidence is that attack success rates come from benchmark conditions and vary widely by model, so real exposure depends on your clients and servers. Even so, the case shows why approval must be bound to what a server does, not merely to what it is called.
Frequently Asked Questions on Model Context Protocol vs Function Calling
The short version of model context protocol vs function calling: differences and when to use each is that they sit at different layers of the stack. Function calling is a model feature that returns a structured request naming a tool and its arguments. MCP is an open protocol that defines how tools are described, discovered, and executed by servers. One handles the model's decision, and the other handles how tool code is packaged and reached.
No, MCP does not replace function calling, because the two operate on different layers. A model still uses its tool calling ability to decide which tool to request. MCP standardizes how the requested tool is described, discovered, and run. Most production agents therefore end up using both layers at the same time.
An MCP server can expose three kinds of features: tools, resources, and prompts. Tools are functions the model can execute, resources are context and data, and prompts are templated messages that users can invoke. Clients can offer sampling, roots, and elicitation back to servers. Function calling has no equivalent for resources, prompts, or these client features.
There is no hard limit, but guidance from model vendors gives a useful signal. OpenAI recommends keeping fewer than about twenty functions available at the start of a turn. Portkey's guidance suggests plain function calling for fewer than five tools and MCP at roughly ten or more across teams. Count tokens as well as tools, because long descriptions can matter more than the raw number.
It can, because MCP makes it easy to attach many servers whose tool definitions all load into the context window. Anthropic reported that a five-server setup with 58 tools used about 55,000 tokens before any conversation began. Plain function calling has the same cost per definition, so the difference is scale rather than protocol. Tool search and code execution can cut the overhead dramatically, as the Cloudflare and Anthropic figures in this guide show.
Neither is inherently more secure, because each moves risk to a different place. MCP can isolate credentials per server and enable central logging and allowlists. It also introduces third-party servers whose tool descriptions the model reads as instructions, which creates tool poisoning risk. Function calling keeps everything in your code, so your handlers and authorization checks carry the full burden. Whichever you choose, require human approval for consequential actions and validate every argument.
With MCP, a server describes its tools once and any compliant client can translate them for its model provider. With plain function calling, field names and message shapes differ between providers, so you usually rewrite some glue code. A thin adapter that converts a neutral tool description into each provider's schema keeps that work small. The hybrid pattern in this guide uses exactly that approach.
In-process function calling is faster per call, because it avoids a process or network boundary. A local MCP server over standard input and output adds little overhead, while a remote server adds a network round trip plus authentication. For tools that already call external APIs, the extra hop is usually small compared with the API itself. Measure end-to-end turn time on your own tasks before deciding.
A startup with one product, one model provider, and a short list of tools should usually start with function calling. It needs no extra servers, no registry, and no gateway to operate. Keep tool logic in ordinary functions behind a thin interface so you can move to MCP later. Revisit the choice when a second application, a second team, or a second provider needs the same tools.
Yes, and most mature systems already combine the two approaches. The host application connects to MCP servers, translates their tool lists into the schema its model provider expects, and sends them to the model. The model returns ordinary tool calls, and the host routes each one to the right server. Latency-critical tools can still run as native in-process functions alongside them.
Tool poisoning hides malicious instructions inside a tool's description or metadata, which the model reads as trusted guidance. The attack can steer the model to misuse legitimate tools, for example to read secrets and send them elsewhere. The MCPTox benchmark measured success rates of up to 72.8 percent across 20 agents. Defenses include allowlisting servers, scanning descriptions, isolating processes, and requiring approval for sensitive actions.
It is usually a packaging exercise when tool logic already sits behind a thin interface. You move the function body into a server, expose it with the SDK, and point your host at it. Running both paths in parallel on a slice of traffic lets you compare accuracy, latency, and cost. Most effort goes into authentication, deployment, and governance rather than the tool code itself.
Anthropic created MCP and released it as an open standard in November 2024. In December 2025 it joined the Agentic AI Foundation, which Anthropic, Block, and OpenAI co-founded. Google, Microsoft, AWS, Cloudflare, and Bloomberg also provide support for the foundation. A neutral foundation makes it less likely that any single vendor controls the specification.