
Introduction
Learning how to build a retrieval pipeline with hybrid search and reranking has become a core skill for teams shipping search boxes, support assistants, and retrieval-augmented generation systems. A single retriever rarely survives contact with real users, because some queries hinge on exact identifiers while others depend on meaning. Anthropic’s own tests found that reranked contextual embeddings plus contextual BM25 cut top-20 retrieval failures by 67 percent, showing how much accuracy lives outside the embedding model. Hybrid search runs a keyword engine and a vector engine side by side, then fuses their ranked lists into one candidate set. Reranking adds a slower, more accurate model that rescores only the best few dozen candidates before anything reaches the user or the language model. This guide walks through the concepts, the design decisions, the measurements, and a complete Python implementation you can adapt to your own corpus. By the end you will know which knobs matter, which ones are folklore, and how to prove that each stage earns its latency.
Quick Answers on Hybrid Search and Reranking Pipelines
How do you build a retrieval pipeline with hybrid search and reranking?
To follow how to build a retrieval pipeline with hybrid search and reranking, index documents for BM25 and embeddings, fuse both ranked lists with reciprocal rank fusion, then rerank the top candidates with a cross-encoder.
What is reciprocal rank fusion in hybrid search?
In hybrid search, reciprocal rank fusion scores each document as the sum of one divided by (k plus rank) across every ranked list, with k commonly 60, so consensus documents rise to the top.
Why add a reranker to a hybrid retrieval pipeline?
A reranker in a hybrid search pipeline reads the query and each candidate together, which captures fine-grained relevance that separate embeddings miss. Running it only on the top fifty or so candidates keeps latency and cost manageable.
Key Takeaways
- Hybrid search pairs lexical matching (BM25) with dense vectors so exact terms and paraphrased meaning are both retrieved.
- Reciprocal rank fusion merges the two ranked lists without needing comparable scores, and a constant of 60 is a sensible default.
- A cross-encoder reranker rescoring roughly 50 to 150 candidates delivers the largest single quality gain, at a measurable latency cost.
- Every stage should be justified with recall and nDCG measurements on your own labeled queries rather than vendor benchmarks.
Table of contents
- Introduction
- Quick Answers on Hybrid Search and Reranking Pipelines
- Key Takeaways
- What Is a Retrieval Pipeline With Hybrid Search and Reranking?
- Why Single-Method Retrieval Falls Short in Production Search
- How Lexical Matching and Dense Vectors Complement Each Other
- Choosing Chunking and Indexing Strategies That Feed Both Retrievers
- Fusing Ranked Lists With Reciprocal Rank Fusion and Weighted Scores
- Picking a Reranker: Cross-Encoders, Hosted APIs and Late Interaction
- Putting the Pipeline to Work Within Latency and Cost Budgets
- Measuring Retrieval Quality With Recall, nDCG and Honest Test Sets
- Risks, Failure Modes and Ethical Questions in Retrieval Systems
- Security, Privacy and Access Control Across Retrieved Documents
- The Future of Hybrid Retrieval and Reranking
- How to Build a Retrieval Pipeline With Hybrid Search and Reranking, Step by Step
- Step 1 – Prepare and chunk the corpus
- Step 2 – Build the lexical BM25 index
- Step 3 – Build the dense vector index
- Step 4 – Fuse the two ranked lists with reciprocal rank fusion
- Step 5 – Rerank the fused candidates with a cross-encoder
- Step 6 – Evaluate every stage on labeled queries
- Step 7 – Tune depth and ship with latency guards
- Key Insights
- Hybrid Retrieval in Practice: Three Examples With Measured Results
- Lessons From Case Studies on Reranking and Hybrid Retrieval
- Common Questions About Building a Hybrid Search and Reranking Pipeline
What Is a Retrieval Pipeline With Hybrid Search and Reranking?
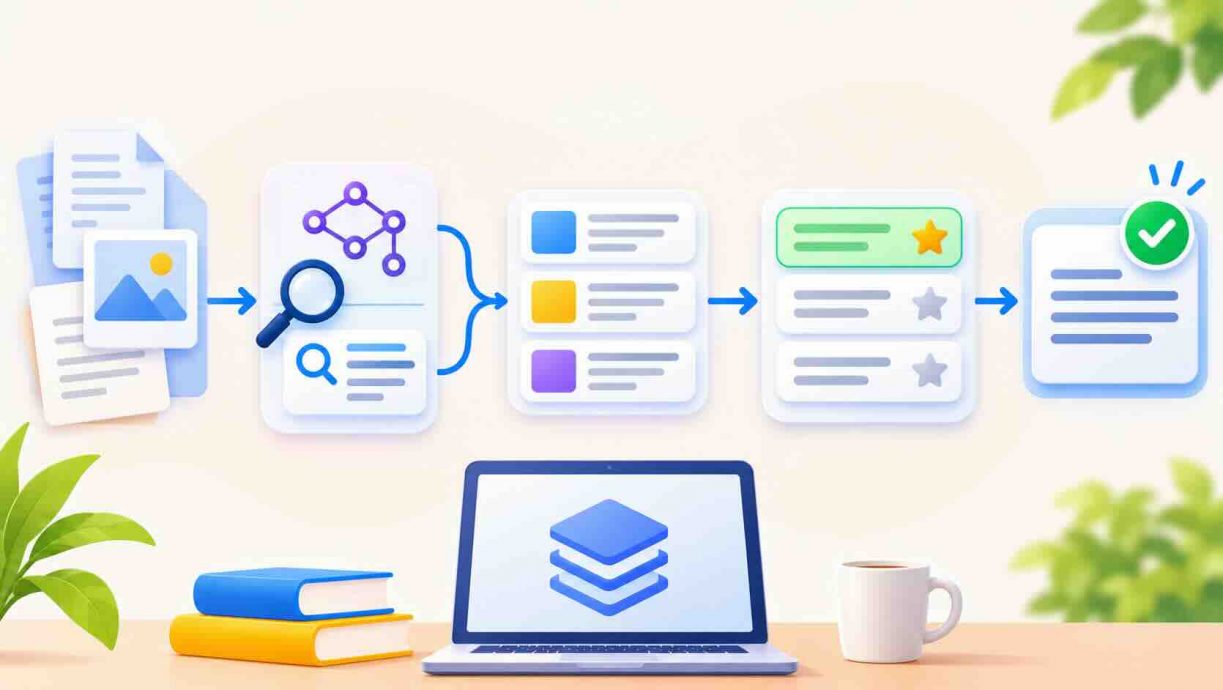
How to build a retrieval pipeline with hybrid search and reranking means assembling stages that retrieve with BM25 and vectors, fuse both ranked lists, and rescore the top candidates with a cross-encoder for higher precision.
An Interactive From AIplusInfo
Retrieval Pipeline Budget Explorer
Choose the stages in your pipeline, set the reranker depth and speed, and see the benchmark failure rate against the latency you spend.
Hybrid plus reranker
50 candidates
Hosted API
800 ms
Top-20 failure rate
1.9%
Lower is better.
Reduction vs baseline
67%
Versus a 5.7% baseline.
Estimated pipeline latency
0 ms
Budget verdict
Within budget
Failure rates are the top-20 chunk retrieval failure figures reported in Anthropic’s contextual retrieval study. The 30 ms per result rate is derived from the Databricks figure of 1.5 seconds for 50 results, and the CPU and GPU rates are assumptions you should replace with your own measurements. First-stage retrieval is modeled at 30 ms.
Why Single-Method Retrieval Falls Short in Production Search
Every retrieval method carries a blind spot, and production traffic finds that blind spot within the first week. Keyword engines such as BM25 reward exact term overlap, so a query for a product code or an error string works beautifully while a paraphrased question returns nothing useful. Dense embedding models invert that profile, because they place semantically similar passages near each other even when the words differ completely. The same models often blur rare identifiers, version numbers, and proper names into the surrounding topic, which makes exact lookups unreliable. No single retriever dominates across query types, so the safest design assumes every method will fail on some fraction of real traffic.
The published research record supports that caution with data from several benchmarks. The BEIR benchmark evaluated retrieval models zero-shot across 18 public datasets and found that BM25 remains a robust baseline, while re-ranking and late-interaction models achieve the best average results. Dense retrievers that look excellent on the dataset they were trained on frequently lose ground when the domain shifts to legal text, scientific abstracts, or code. That pattern matters for anyone indexing private company documents, because those documents resemble no public training set. Teams that ship a vector-only system often discover the gap only after users complain that searching for an exact policy number returns loosely related essays.
Weak retrieval also feeds directly into the quality of downstream generated answers. When the passage that contains the answer never reaches the language model, no prompt can recover it, and the model fills the gap with plausible invention. Our guide on reducing LLM hallucinations in production makes the same point from the generation side: grounding quality is capped by retrieval quality. Measuring retrieval separately from generation lets you tell whether a bad answer came from missing evidence or from a model that ignored good evidence. A hybrid pipeline with reranking attacks the first failure mode directly by widening what gets found and then sharpening what gets shown.
How Lexical Matching and Dense Vectors Complement Each Other
Building on those blind spots, the two retrieval families can be understood by what each one notices. BM25 scores a document by counting query terms, discounting very common words, and normalizing for document length through two tunable parameters usually called k1 and b. It needs no training, updates instantly when documents change, and explains its own scores, which makes debugging pleasant. Dense retrieval encodes the query and every passage into vectors with a bi-encoder model, then returns the passages whose vectors sit closest to the query vector. Because the document vectors are computed ahead of time, a single query costs one model call plus a fast approximate nearest-neighbor lookup. Early word embeddings were the first form of this idea, and modern sentence encoders extend it to whole passages.
The complementary strengths show up clearly in several concrete query types. Lexical search wins on rare tokens, quoted phrases, part numbers, function names, and any query where the user already knows the right vocabulary. Vector search wins when the user describes a concept in their own words and the document uses different terminology for the same idea. A support question such as "my laptop will not wake up" should find an article titled "Resolving resume-from-sleep failures," and only embeddings make that leap reliably. Running both retrievers and merging their output means the system does not have to guess in advance which kind of query it is facing.
Choosing Chunking and Indexing Strategies That Feed Both Retrievers
Stepping back from the ranking stages, the quality of everything downstream depends on how documents are split before indexing. Chunks that are too small lose the context that makes a sentence interpretable. Chunks that are too large dilute the embedding and bury the relevant sentence. A practical starting point is passages of roughly 200 to 400 tokens with 10 to 20 percent overlap, split at paragraph or heading boundaries instead of arbitrary character counts. Each chunk should carry metadata such as the source title, section heading, URL, and last-modified date, because filters and citations depend on it. The same chunk text feeds both indexes, so a decision made here affects BM25 and the vector index equally.
Context loss is the most common chunking failure, and it is worth designing against. A chunk that says "revenue grew 3 percent over the previous quarter" is nearly useless without knowing which company and which quarter it describes. Anthropic's contextual retrieval technique prepends a short generated explanation of the chunk's place in its source document. It applies that prefix to both the embedding and the BM25 index. Long contexts bring their own hazards, since models lose track of details as the window fills, a phenomenon covered in our explainer on context rot in large language models. Smaller, self-describing chunks therefore help twice: they improve retrieval and they leave more room in the prompt for other evidence.
Analyzer settings deserve the same careful attention as chunk size and overlap. For the lexical index, decide on lowercasing, stemming, stop-word handling, and how to tokenize identifiers such as "user_id" or "v2.1.3", because the wrong choice silently destroys exact-match recall. For the vector index, pick an embedding model whose training domain and language coverage match your corpus, and record its name and version alongside the index. Changing the embedding model later forces a full re-embedding, so treat that choice like a schema migration. Store raw text, chunk identifiers, and metadata in one place so both indexes can be rebuilt from a single source of truth.
Index freshness is the last practical matter to settle before moving on to ranking. Lexical indexes accept new documents within seconds, while vector indexes built on approximate nearest-neighbor graphs may need background merges or periodic rebuilds to stay fast and accurate. Decide early how stale each index is allowed to be, and expose that lag in your monitoring dashboards. Delete handling is a frequent surprise, because removing a document from only one of the two indexes leaves ghosts that fusion will faithfully promote. Schedule a periodic reconciliation job that compares document identifiers across both indexes and the source store.
Fusing Ranked Lists With Reciprocal Rank Fusion and Weighted Scores
Turning to the fusion step, the central problem is that BM25 scores and cosine similarities live on incompatible scales. A BM25 score might range from zero to thirty depending on query length. Cosine similarity sits between minus one and one, so adding the two directly lets one retriever drown the other. Reciprocal rank fusion sidesteps the problem by ignoring scores entirely and using only each document's rank in each list. The formula adds 1 divided by (k plus rank) for every list in which the document appears. The original RRF paper fixed k at 60 and reported that it beat Condorcet fusion, CombMNZ, and the best individual system by four to five percent on average. A document that ranks moderately well in both lists will usually beat a document that ranks first in only one, which is exactly the consensus behavior you want.
Score-based fusion is the main alternative, and it can win when the scores carry real signal. The approach normalizes each list, commonly with min-max scaling, and then combines them with a weight often called alpha. Weaviate's hybrid search exposes both strategies: ranked fusion uses positions only, while relative score fusion min-max normalizes each list and has been the default since version 1.24. Its alpha parameter defaults to 0.75, where zero means pure keyword search and one means pure vector search. Rank-based fusion is more forgiving when you do not know the score distributions, whereas score-based fusion preserves the information that one candidate was a runaway winner.
Whichever method you pick, treat the candidate window as a first-class parameter. Each retriever should return enough results, commonly 50 to 200, that relevant documents appear in at least one list before fusion trims the pool. Elasticsearch's RRF retriever documents the same idea through a rank constant that defaults to 60 and a window size that trades relevance against cost. Your own evaluation set should decide the window, the constant, and the alpha, because the right values depend on corpus size and query mix. Resist the temptation to tune on five hand-picked queries, since fusion settings overfit small samples easily.
Picking a Reranker: Cross-Encoders, Hosted APIs and Late Interaction
Moving on from fusion, the reranker is where a pipeline buys most of its precision. A bi-encoder embeds the query and the document separately, so it can only compare two compressed summaries. A cross-encoder feeds the query and the document into the model together, allowing every query token to attend to every document token, which captures negation, qualifiers, and subtle topical fit. That joint reading is far more accurate and far more expensive, so it is applied only to the few dozen candidates that fusion surfaced. The Sentence Transformers cross-encoder models trained on MS MARCO are the usual open-source starting point, and they run comfortably on a single GPU or even a CPU for small batches.
Hosted reranking APIs are the second option, and they trade control for convenience. Services from vendors such as Cohere, Voyage, Jina, and the major clouds accept a query and passages, then return relevance scores with no model hosting on your side. The deciding factors are usually latency, data-residency rules, and cost per thousand documents reranked, not raw accuracy on a public leaderboard. Self-hosting a small cross-encoder keeps documents inside your network and gives predictable cost, but you own scaling, batching, and model updates. Late-interaction models such as ColBERT sit between the two worlds. They store per-token vectors so they can score richly without a full joint pass, at the price of a much larger index.
Putting the Pipeline to Work Within Latency and Cost Budgets
Looking at the pipeline as a production service, every stage spends part of a latency budget that users feel directly. A typical interactive search target is a few hundred milliseconds end to end, and retrieval-augmented chat can tolerate a second or two before generation begins. BM25 lookups usually take single-digit milliseconds on a well-sized index, approximate vector search takes somewhat longer, and the two can run in parallel so the slower one sets the pace. The reranker is almost always the largest line item, because it runs a transformer forward pass for every query and candidate pair. Treat the reranker's candidate count as the main dial for trading accuracy against latency, and set it from measurements instead of habit.
Vendors publish a few figures that help you calibrate your expectations early on. Databricks reports that its Mosaic AI reranker reranks 50 results in as little as 1.5 seconds. It suggests reranking mostly helps when the right answer appears in the top 50 but not the top 10. Anthropic's tests retrieved 150 chunks and passed the top 20 onward after reranking, noting an inherent trade-off between reranking more chunks and keeping latency and cost low. Your numbers will differ with hardware, passage length, and model size, so benchmark with your own documents. Cache the results of frequent queries, and cache document embeddings so only the query is encoded at request time.
Cost control extends beyond the reranker to the whole stack. Contextual chunk generation is a one-time indexing expense, which Anthropic estimated at about $1.02 per million document tokens under its stated assumptions. Query-time costs scale with traffic, so a cheap first pass that skips reranking for obviously easy queries can cut spend without hurting quality. Our overview of ways to reduce LLM inference costs covers batching, quantization, and routing tactics that apply equally to rerankers. Add timeouts and a graceful fallback, so that if the reranker is slow or unavailable the pipeline returns the fused list instead of an error.
Candidate depth and passage length determine reranker latency more than model choice does. Doubling the number of candidates roughly doubles inference time, and long passages are truncated by the model's maximum sequence length, which can silently cut off the answer. Batch the candidate pairs, cap the passage length to a size the model was trained on, and measure p95 latency under realistic concurrency. Watch the tail percentiles closely, because a few slow batches can dominate the experience of the unluckiest users. Warm the model at startup so the first request does not pay the loading penalty. Reranker latency therefore deserves its own dashboard panel, separate from retrieval time.
Measuring Retrieval Quality With Recall, nDCG and Honest Test Sets
Beyond the build itself, a hybrid pipeline is only as trustworthy as the evaluation that justified it. Start with a labeled set of real queries paired with the passages that answer them, even if it holds only a hundred or two examples. Recall at k asks whether the right passage appears anywhere in the top k results, which is the right metric for the first-stage retrievers and the fusion window. Mean reciprocal rank and nDCG at 10 reward placing the right passage near the top, which is what the reranker is supposed to improve. Report each metric per stage, so you can see exactly what fusion added over each single retriever and what reranking added over fusion.
Label quality decides whether any of the reported numbers actually mean anything. Build the set from logged user queries and expert review. Avoid generating every question with a language model from the same documents, because those questions mirror the passage wording and flatter lexical search. Hold out a portion of the queries that you never tune against, and treat the score on that portion as the only number you quote. Include hard cases on purpose: identifiers, negations, multi-hop questions, and queries with no answer in the corpus. Stratify results by query type, because an average can hide a regression on exact-match lookups that matters more than a gain elsewhere.
End-to-end answer quality needs its own measurement on top of retrieval metrics. Frameworks such as RAGAS score context precision, context recall, and faithfulness, and our walkthrough on evaluating agents with RAGAS metrics shows the mechanics. Model-graded evaluation is useful for generation but should be calibrated against human labels, as described in the guide to evaluating outputs with an LLM judge. Re-run the whole evaluation whenever the embedding model, chunking rules, fusion constants, or reranker change. A small regression suite wired into continuous integration catches most silent quality drops before users do.
Online signals complete the picture once the system is live. Click-through position, reformulation rate, and the share of answers users mark as unhelpful all reveal problems the offline set missed. Sample failed queries weekly and add them to the labeled set so the benchmark tracks real traffic. Log the ranks and scores each stage produced, because without them you cannot tell whether a bad result came from retrieval, fusion, or reranking. Review the dashboards together with support staff, who often spot patterns the metrics miss.
Risks, Failure Modes and Ethical Questions in Retrieval Systems
Despite the gains, the most common failure is silent: a document that should have been retrieved simply never appears. The cross-encoder can only reorder what the first stage found. An AWS write-up on reranking points out that the later stage cannot recover documents that were excluded. That makes first-stage recall the ceiling for the entire pipeline, which is why candidate windows should be generous. Other failure modes include stale indexes, duplicate chunks that crowd out diverse evidence, and rerankers that favor long or confidently worded passages over correct ones. Monitor recall at the fusion stage separately from final precision, because the two fail for different reasons and need different fixes.
Ethical questions follow from who and what the ranking system favors. Rerankers inherit the biases of their training data, so they may systematically prefer certain dialects, writing styles, or sources. A hybrid system can amplify whatever the lexical index already overweights. When ranked results feed a language model, the ordering shapes which viewpoints the answer reflects and which sources receive credit or traffic. Transparency practices help: show citations, expose why a result matched, and let users see the source passages instead of only a synthesized answer. Our guide to testing models for bias and fairness offers audit methods that transfer well to ranking systems.
Security, Privacy and Access Control Across Retrieved Documents
Shifting focus to security, retrieval systems concentrate sensitive text in two indexes and a model that can read it. Access control must be enforced at query time, with permission filters applied inside both searches so a user never receives a candidate they could not open directly. Filtering after retrieval is risky, because it wastes the candidate window and may leak the existence of restricted documents through result counts or timing. Store the access-control metadata with every chunk, and re-sync it when permissions change, since stale entitlements are a common source of exposure. Embeddings themselves can leak information about the text they encode, so apply the same retention and encryption rules to vector stores as to the source documents.
Retrieved text is also an attack surface, because documents can contain instructions aimed at the language model that reads them. A poisoned wiki page or uploaded file can try to override the system prompt or exfiltrate data through the answer. Defenses include treating retrieved content as untrusted data, stripping or flagging instruction-like text, and limiting what tools the model may call after reading it. Our article on prompt injection attacks and defenses lays out those mitigations in detail. Reranking does not remove malicious passages and can even promote a persuasive one, so security review has to cover the retrieval path as well as the prompt.
Privacy rules shape what may be indexed in the first place. Personal data, regulated records, and confidential contracts need classification, minimization, and deletion workflows before they enter any search index. When a user exercises a deletion right, the document must disappear from the lexical index, the vector index, any caches, and any stored evaluation logs. Follow the practices summarized in our guide to AI data privacy best practices when drafting retention schedules. Document the retention period for each index so audits can verify it.
The Future of Hybrid Retrieval and Reranking
Looking ahead, the boundaries between the individual retrieval stages are steadily blurring. Learned sparse models such as SPLADE and Pinecone's sparse encoders add semantic expansion to lexical matching. Pinecone reports that its sparse model beat BM25 by up to 44 percent in NDCG@10 on TREC Deep Learning tracks. Multi-vector and late-interaction systems keep per-token representations to approach cross-encoder accuracy at lower cost. Vendors increasingly bundle dense, sparse, and reranking into a single managed call, which hides the plumbing but makes your own evaluation set even more valuable. Expect the winning architecture to be decided by measured recall and latency on your data rather than by any fixed recipe.
Retrieval is also becoming an agent capability instead of a fixed pre-processing step. Agents decide when to search, rewrite their own queries, and call different indexes, which raises the importance of consistent tool interfaces and good context management. Our explanation of context engineering for LLM agents covers how retrieved evidence should be selected and compressed before it reaches the model. Graph-structured retrieval adds relationships between entities on top of text similarity, a trade-off examined in GraphRAG versus traditional RAG. Hybrid text retrieval remains the foundation underneath those richer systems, so skills invested here carry forward.
Enterprise adoption points in the same direction for most large organizations today. Organizations are folding search, knowledge management, and generative answers into one layer, which makes shared retrieval infrastructure a strategic asset. Teams will also weigh whether to retrieve at query time or adapt the model itself. Retrieval keeps knowledge fresh and auditable, which fine-tuning cannot match without retraining. Plan for models and vendors to change, and keep your evaluation harness portable so swapping a component is a measured decision. A portable harness also lets you adopt new rerankers within days instead of months.
Chart From AIplusInfo
Each retrieval stage cuts failed lookups further
Top-20 chunk retrieval failure rate, in percent. Lower is better.
Source: Anthropic, Introducing Contextual Retrieval, top-20 chunk retrieval failure rate across codebases, fiction, ArXiv papers, and science papers.
How to Build a Retrieval Pipeline With Hybrid Search and Reranking, Step by Step
Putting the earlier design decisions into code, the walkthrough below builds a complete pipeline in about 100 lines of Python. It uses an in-memory BM25 index, a flat vector index, reciprocal rank fusion, and an open-source cross-encoder, so you can run it on a laptop first. Each step is deliberately small and independently testable, which lets you swap any component later without rewriting the rest. If you want a broader application around it, our guide to building a RAG chatbot with open-source tools shows how to wrap the same retrieval core in a chat interface. Install the dependencies first, ideally inside a fresh virtual environment, and pin their versions so your evaluation numbers stay reproducible. The code assumes your documents are already loaded as plain text with an identifier and a title.
pip install rank-bm25 sentence-transformers faiss-cpu numpyStep 1 - Prepare and chunk the corpus
Start by turning every source document into chunks of roughly 200 to 250 words, split on paragraph boundaries with a small overlap. The function below accumulates paragraphs until a word limit is reached, emits the chunk, and carries the last 30 words forward so straddling sentences remain findable. Each chunk keeps its document identifier and title, which you will need later for citations, filters, and evaluation labels. Keep the list of chunks as the single source of truth, because both indexes will refer to chunks by their position in that list. Pro tip: prepend the document title to each chunk before indexing, since a heading often supplies the context a bare paragraph lacks.
import re
from dataclasses import dataclass

@dataclass
class Chunk:
    chunk_id: str
    doc_id: str
    title: str
    text: str

def split_into_chunks(doc_id, title, text, max_words=220, overlap=30):
    paragraphs = [p.strip() for p in re.split(r"\n\s*\n", text) if p.strip()]
    pieces, current = [], []
    for para in paragraphs:
        words = para.split()
        if current and len(current) + len(words) > max_words:
            pieces.append(" ".join(current))
            current = current[-overlap:]
        current.extend(words)
    if current:
        pieces.append(" ".join(current))
    return [Chunk(f"{doc_id}-{i}", doc_id, title, f"{title}. {piece}")
            for i, piece in enumerate(pieces)]

chunks = []
for doc in documents:  # documents: list of dicts with id, title, text
    chunks.extend(split_into_chunks(doc["id"], doc["title"], doc["text"]))
Step 2 - Build the lexical BM25 index
Next, build the keyword index with the rank-bm25 library, which implements the Okapi BM25 formula in pure Python. The tokenizer lowercases text and keeps digits, underscores, and dots, so identifiers such as version strings and function names survive as single tokens. BM25 exposes the k1 and b parameters, and the defaults of the library are a reasonable place to begin before you tune on labeled queries. The search function scores every chunk, sorts them, and returns the positions of the top 100 results that scored above zero. For a corpus beyond a few hundred thousand chunks, move this step to a dedicated engine such as Elasticsearch or OpenSearch, which provide the same scoring with inverted indexes. Keep the return type as a plain list of chunk positions so the fusion step stays agnostic about where results came from.
from rank_bm25 import BM25Okapi

def tokenize(text):
    return re.findall(r"[a-z0-9_.]+", text.lower())

bm25 = BM25Okapi([tokenize(c.text) for c in chunks])

def bm25_search(query, k=100):
    scores = bm25.get_scores(tokenize(query))
    order = scores.argsort()[::-1][:k]
    return [int(i) for i in order if scores[i] > 0]
Step 3 - Build the dense vector index
Then encode every chunk with a sentence embedding model and store the normalized vectors in a FAISS index. The all-MiniLM-L6-v2 model produces 384-dimensional vectors, runs quickly on a CPU, and is a sensible baseline before you try larger or domain-specific encoders. Normalizing the vectors lets an inner-product index behave like cosine similarity, which is the usual way to compare sentence embeddings. A flat index performs exact search and is fine up to a few hundred thousand vectors, while larger collections should switch to an approximate index such as HNSW. Record the model name next to the index, because mixing vectors from two different models silently corrupts the results. Pro tip: encode in batches of 64 or more, since throughput on both CPU and GPU improves sharply with batching.
import numpy as np
import faiss
from sentence_transformers import SentenceTransformer

encoder = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2")
vectors = encoder.encode([c.text for c in chunks],
                         normalize_embeddings=True, batch_size=64)
index = faiss.IndexFlatIP(vectors.shape[1])
index.add(np.asarray(vectors, dtype="float32"))

def vector_search(query, k=100):
    q = encoder.encode([query], normalize_embeddings=True)
    _, ids = index.search(np.asarray(q, dtype="float32"), k)
    return [int(i) for i in ids[0] if i != -1]
Step 4 - Fuse the two ranked lists with reciprocal rank fusion
With both retrievers returning ranked lists of chunk positions, fuse them using reciprocal rank fusion with the standard constant of 60. Each chunk receives 1 divided by (60 plus its rank) from every list that contains it, and the scores are summed across lists. Chunks found by both retrievers accumulate two contributions and therefore float above chunks found by only one, which is the consensus effect described earlier. The function accepts any number of rankings, so you can add a third retriever, such as a title-only index or a learned sparse model, without changing the fusion code. Return the top 100 fused chunks, which becomes the candidate pool for the reranker. If you later find that one retriever deserves more influence, multiply its contribution by a weight and tune that weight against your labeled queries.
def rrf_fuse(rankings, k=60, top_n=100):
    scores = {}
    for ranking in rankings:
        for rank, position in enumerate(ranking, start=1):
            scores[position] = scores.get(position, 0.0) + 1.0 / (k + rank)
    ordered = sorted(scores, key=scores.get, reverse=True)
    return ordered[:top_n]
Step 5 - Rerank the fused candidates with a cross-encoder
Now load a cross-encoder and rescore the top 50 fused candidates against the query. The model cross-encoder/ms-marco-MiniLM-L-6-v2 is small enough to run on a CPU and was trained on MS MARCO passage ranking, so it suits English question-style queries. The function builds query and passage pairs, predicts one relevance score per pair, sorts by that score, and returns the best ten chunk positions. Passages longer than the model limit of 512 tokens are truncated, so make sure your chunk size keeps the answer inside that window. If your domain is specialized or multilingual, evaluate a larger reranker or a hosted API against this baseline using the harness in the next step. Pro tip: keep the number of candidates a parameter, since it is the main dial for trading accuracy against latency.
from sentence_transformers import CrossEncoder

reranker = CrossEncoder("cross-encoder/ms-marco-MiniLM-L-6-v2", max_length=512)

def rerank(query, candidate_positions, top_k=10):
    pairs = [(query, chunks[i].text) for i in candidate_positions]
    scores = reranker.predict(pairs, batch_size=32)
    ranked = sorted(zip(candidate_positions, scores),
                    key=lambda item: item[1], reverse=True)
    return [position for position, _ in ranked[:top_k]]
Step 6 - Evaluate every stage on labeled queries
Before trusting the pipeline, measure each stage on a labeled set of at least 100 real queries, where every query maps to the set of chunk positions that answer it. The harness below computes recall at 10 and nDCG at 10 for BM25 alone, vectors alone, the fused list, and the fused list after reranking. Comparing the four rows tells you what each component contributes, and a stage that adds nothing is a candidate for removal. Slice the results by query type, such as identifier lookups versus natural-language questions, to catch regressions that the average hides. Keep a held-out portion of about 20 percent of the queries untouched during tuning, and quote only that number when reporting results. Rerun the harness whenever the chunking rules, models, or constants change.
import math

def recall_at_k(ranked, relevant, k=10):
    return len(set(ranked[:k]) & relevant) / max(len(relevant), 1)

def ndcg_at_k(ranked, relevant, k=10):
    dcg = sum(1.0 / math.log2(r + 2) for r, p in enumerate(ranked[:k]) if p in relevant)
    ideal = sum(1.0 / math.log2(r + 2) for r in range(min(len(relevant), k)))
    return dcg / ideal if ideal else 0.0

def evaluate(labeled, search_fn):
    recalls, ndcgs = [], []
    for query, relevant in labeled.items():
        ranked = search_fn(query)
        recalls.append(recall_at_k(ranked, relevant))
        ndcgs.append(ndcg_at_k(ranked, relevant))
    return sum(recalls) / len(recalls), sum(ndcgs) / len(ndcgs)

def fused(q):
    return rrf_fuse([bm25_search(q), vector_search(q)])

systems = {
    "bm25": bm25_search,
    "vector": vector_search,
    "hybrid": fused,
    "hybrid + rerank": lambda q: rerank(q, fused(q)[:50]),
}
for name, fn in systems.items():
    print(name, evaluate(labeled_queries, fn))
Step 7 - Tune depth and ship with latency guards
Finally, wrap the stages in one search function with explicit limits so the pipeline behaves predictably under load. The function fuses the two lists, trims the pool to the rerank depth, and reranks only if the time already spent is within a budget of 0.8 seconds. If the reranker raises an error or the budget is exceeded, the function falls back to the fused ordering, so users still receive good results. Sweep the rerank depth across values such as 20, 50, and 100 on your labeled queries, and choose the smallest depth where nDCG stops improving. Log the rank and score from every stage, plus the latency of each call, so production problems can be traced to a specific stage. Put the function behind your API, add a cache for frequent queries, and review the logs weekly to expand the labeled set.
import time

def search(query, window=100, rerank_depth=50, top_k=10, budget_s=0.8):
    start = time.perf_counter()
    fused_ids = rrf_fuse([bm25_search(query, window), vector_search(query, window)],
                         top_n=rerank_depth)
    if time.perf_counter() - start > budget_s:
        return fused_ids[:top_k]
    try:
        return rerank(query, fused_ids, top_k)
    except Exception:
        return fused_ids[:top_k]
Recommended by AIplusInfo
Books to go deeper on search and retrieval
Two practitioner titles that extend the pipeline you just built.
As an Amazon Associate, AIplusInfo earns from qualifying purchases.

Book
AI-Powered Search
A practitioner guide to relevance engineering, hybrid lexical and vector retrieval, and learning to rank that extends the pipeline built above.
Buy on Amazon
Book
AI Engineering: Building Applications with Foundation Models
Chip Huyen covers retrieval, RAG architectures, and evaluation for production foundation-model applications, which frames where this retrieval pipeline fits.
Buy on AmazonKey Insights
- Anthropic's contextual retrieval tests cut the top-20 retrieval failure rate from 5.7 percent to 1.9 percent once reranking joined contextual embeddings and contextual BM25, a 67 percent reduction.
- Generating the context prefix for every chunk costs about $1.02 per million document tokens under Anthropic's assumptions, so indexing expense stays small next to the retrieval gain.
- Pinecone's cascading retrieval research reports that rerankers lifted TREC results by up to 48 percent, and by 24 percent on average, compared with dense vector search alone.
- Pinecone's own benchmark shows dense plus sparse retrieval with a reranker beating CombSUM score fusion by 8 percent on average across BEIR, which favors reranking over fancier fusion math.
- The original reciprocal rank fusion paper fixed k at 60 and beat Condorcet fusion, CombMNZ, and the best single system by roughly 4 to 5 percent on average.
- Across 18 datasets, the BEIR benchmark found BM25 to be a robust baseline while re-ranking models achieved the best average zero-shot results, albeit at much higher computational cost.
- Databricks reports reranking lifted recall at 10 from 74 percent to 89 percent, an average gain of 15 percentage points, though the figures come from its own tests.
- Weaviate's hybrid search defaults its alpha weight to 0.75 and has used relative score fusion by default since version 1.24, which shows even vendors keep a keyword component beside vectors.
Taken together, these insights point to a consistent pattern across independent sources and vendors. Fusing lexical and vector retrieval raises recall, and a reranker then converts that wider candidate pool into better precision at the top of the list. The gains reported range from single digits for fusion constants to tens of percent for the complete cascade, which explains why the full pipeline repeatedly beats any single component. Costs stay modest when reranking is limited to dozens of candidates and indexing work is done once. Vendor figures come from vendor benchmarks, so your own labeled queries remain the final judge of which stages deserve a place in production. A team that measures each stage separately will know exactly where its next improvement should come from.
| Dimension | BM25 only | Vector only | Hybrid with RRF | Hybrid plus reranker |
|---|---|---|---|---|
| Best query type | Exact terms and identifiers | Paraphrased concepts | Mixed traffic | Mixed traffic needing top-rank precision |
| Exact identifier lookup | Strong | Weak to moderate | Strong | Strong |
| Paraphrase and synonym matching | Weak | Strong | Strong | Strongest |
| Typical added latency | Single-digit milliseconds | Tens of milliseconds | Tens of milliseconds (parallel) | Hundreds of milliseconds to seconds |
| Indexing cost | Low, no model needed | Embedding every chunk | Both indexes | Both indexes, no extra index for the reranker |
| Tuning required | k1 and b parameters | Model and index choice | Window size and constant k | Candidate depth and model choice |
| Explainability | High, term-level scores | Low, opaque similarity | Moderate, rank contributions | Moderate, model relevance score |
| Main failure mode | Vocabulary mismatch | Rare tokens blurred | Relevant item missing from both lists | Relevant item excluded before reranking |
Hybrid Retrieval in Practice: Three Examples With Measured Results
Reciprocal Rank Fusion on TREC Collections
Researchers at the University of Waterloo ran reciprocal rank fusion across several TREC collections to test whether a simple rank-based formula could beat established fusion methods. They implemented the 1 divided by (k plus rank) scoring with k fixed at 60 during a pilot study and then left it unchanged for validation. The method improved mean average precision by 7.2 percent over the best individual ranker on TREC 5 and by 2.9 percent on TREC 3. Its main practical lesson is that a parameter-light rank formula can match or beat tuned score combinations, which is why it became the default in many search engines. The limit of the study is its age and its focus on classic keyword systems, since the experiments predate modern dense retrievers. Results were also mixed on some collections, where CombMNZ still edged ahead, so the RRF paper itself is best read as evidence for robustness rather than guaranteed superiority.
Pinecone's Cascading Retrieval Benchmarks
Pinecone built a cascading retrieval stack that combines dense vectors, a learned sparse model, and rerankers, then measured it against single-method baselines. In its published tests, rerankers improved TREC results by up to 48 percent and 24 percent on average over dense search alone. Dense plus sparse retrieval with reranking gained an average of 12 percent over either method on BEIR and 8 percent over CombSUM score fusion. The numbers come with real limits, because Pinecone calls its sparse-only benchmarks preliminary and shows per-dataset values only in charts. The article also does not report latency, and the figures come from the vendor's own research team, so independent replication on your corpus is still required. Even so, the cascading retrieval write-up is a useful reference for what a multi-stage design can deliver at scale.
Databricks Mosaic AI Vector Search Reranker
Databricks rolled out a reranker inside Mosaic AI Vector Search that rescored the top 50 retrieved results for each query. On the company's enterprise benchmarks the feature raised recall at 10 from 74 percent to 89 percent, an average gain of 15 percentage points. Reranking those 50 results took as little as 1.5 seconds, which the company contrasted with several seconds on competing systems. The post recommends the feature mainly for workloads with low recall at 10 but high recall at 50, a useful rule of thumb for deciding where reranking pays off. The main drawbacks are that the feature was in public preview and that the benchmarks are the vendor's own and unnamed. The Databricks reranking announcement is therefore best treated as a directional signal that you verify locally.
Lessons From Case Studies on Reranking and Hybrid Retrieval
Case Study: Anthropic's Contextual Retrieval
Anthropic faced a common problem in retrieval-augmented generation, where chunks lose the context of their source document and retrieval fails on questions that depend on it. A chunk reading "the company's revenue grew by 3 percent" does not say which company or quarter, so neither embeddings nor BM25 could reliably match it. The team built contextual retrieval, which asks a model to prepend a short explanation of the chunk's place in its document before indexing. It applied the prefix to both the embedding and the BM25 index. On its test sets spanning codebases, fiction, and scientific papers, the baseline top-20 failure rate of 5.7 percent fell to 3.7 percent with contextual embeddings. Adding contextual BM25 brought it to 2.9 percent, which was a 49 percent reduction from the baseline.
Reranking supplied the final step, since the system retrieved 150 chunks and passed the best 20 to the model after rescoring. That cascade reached a 1.9 percent failure rate, a 67 percent reduction, and the one-time cost of the context prefixes was estimated at $1.02 per million document tokens. The authors caution that gains vary by embedding model, that chunk boundaries still matter, and that reranking adds latency and cost. They also note that adding more retrieved context can distract the model, so passing 20 chunks beat both 5 and 10 only up to a point. Teams copying the approach should therefore budget for both indexing and query-time costs.
Case Study: The BEIR Zero-Shot Benchmark
Researchers who built BEIR faced a problem the field had avoided, which was that retrieval models were rarely tested outside the dataset they were trained on. Leaderboards rewarded models for in-domain performance, so teams could not tell which architectures would survive on new topics. The BEIR authors assembled 18 public datasets spanning question answering, fact checking, biomedical search, and argument retrieval, then evaluated lexical, sparse, dense, late-interaction, and re-ranking models without any dataset-specific training. The study found that BM25 remained a robust baseline and that re-ranking and late-interaction models achieved the best average zero-shot performance. The result was an increase in credibility for hybrid and cascaded designs, and it gave practitioners a shared yardstick for domain shift. The BEIR paper also warns that the strongest models are costly to run and that dense retrievers still leave room for improvement in generalization.
Case Study: Cohere Rerank 3.5 on Amazon OpenSearch Service
AWS engineers described a challenge familiar to search teams, where lexical and semantic retrieval each miss relevant documents on complex enterprise queries from financial services, e-commerce, and project management. Their solution was a two-stage pipeline in Amazon OpenSearch Service, where BM25 or a bi-encoder gathers candidates and Cohere Rerank 3.5 rescores them jointly with the query. The post reports that the reranker produced an increase in nDCG@10 over its predecessor, BM25, and hybrid search, but the exact scores appear only in charts. It also gives no latency numbers, so teams cannot judge the speed trade-off from the article alone. The same AWS reranking walkthrough stresses a limit that applies to every cascade: the later stage has no way to recover documents the first stage excluded. That concern is why the case reinforces the advice to keep candidate windows generous and to monitor first-stage recall separately.
Common Questions About Building a Hybrid Search and Reranking Pipeline
Hybrid search runs a lexical retriever such as BM25 and a vector retriever on the same query, then merges their ranked results. The lexical side catches exact terms, identifiers, and quoted phrases. The vector side catches paraphrases and related concepts that share no words with the query. The merged list is a stronger candidate pool than either retriever produces alone.
Embeddings blur rare tokens such as part numbers, error codes, and version strings into the surrounding topic, so exact lookups can fail. BM25 handles those cases well but cannot bridge vocabulary gaps. Combining them covers both failure profiles without requiring you to classify queries in advance. Benchmarks such as BEIR show that BM25 stays a robust baseline even against modern neural models.
Reciprocal rank fusion adds 1 divided by (k plus rank) for each list that contains a document, so only positions matter and score scales do not. The constant k of 60 comes from the original paper, where it was fixed during a pilot study and left unchanged. It softens the advantage of the very top ranks so a single outlier list cannot dominate. Elasticsearch and Weaviate both default to the same value, which makes it a safe starting point.
Start with reciprocal rank fusion because it needs no score normalization and no tuning to give a solid result. Move to weighted score fusion, with min-max normalization and an alpha weight, when you have labeled queries that prove it helps. Score-based fusion keeps the information that one candidate was a runaway winner, while rank-based fusion discards it. Whichever you choose, compare both on a held-out query set before committing.
A cross-encoder reranker reads the query and a candidate passage together, so every query word can attend to every passage word. That joint reading captures negation, qualifiers, and fine-grained topical fit that separate embeddings compress away. It is far more accurate per pair but too slow to run over a whole corpus. This is why rescoring only the top candidates from the earlier stages is the standard design.
Most teams begin with 50 candidates and test values between 20 and 150 on their own labeled queries. Choose the smallest depth where nDCG stops improving, because latency grows roughly in proportion to the number of pairs scored. Anthropic's tests retrieved 150 chunks and passed the top 20 onward after reranking. If recall at your retrieval window is already low, increasing the window helps more than increasing the reranker depth.
It depends on the model, the hardware, the passage length, and the number of candidates. Databricks reports reranking 50 results in as little as 1.5 seconds, while a small cross-encoder on a GPU can be much faster. Measure p95 latency under realistic concurrency instead of trusting averages. Add a timeout and fall back to the fused list so a slow reranker never blocks the response.
Begin with an open-source MS MARCO cross-encoder from Sentence Transformers, because it is free, small, and easy to run locally. Compare it against one hosted reranking API using your labeled queries and your latency budget. Prefer a multilingual or domain-tuned model if your documents are not standard English prose. Keep the interface identical across candidates so swapping models is a configuration change.
Build a labeled set of real queries mapped to the passages that answer them, and report recall at 10 and nDCG at 10 for every stage. Include identifier lookups, negations, and unanswerable queries in the set on purpose. Hold out a portion of queries that you never tune against and quote only that number. Our guide to <a href="https://www.aiplusinfo.com/blog/how-to-evaluate-llm-outputs-with-llm-as-a-judge/" target="_blank" rel="noopener">evaluating outputs with an LLM judge</a> helps with the generation side.
Yes, a small corpus works fine with an in-memory BM25 library and a FAISS flat index, as the tutorial above shows. Flat exact search handles a few hundred thousand vectors comfortably on one machine. Beyond that scale you will want approximate indexes and a managed engine such as Elasticsearch, OpenSearch, or a vector database. Design the code so each retriever returns plain lists of positions, which makes migration straightforward.
Chunks of roughly 200 to 400 tokens with modest overlap give both indexes enough context without diluting the embedding. Splitting at paragraph and heading boundaries keeps ideas intact, and prepending the document title restores context a bare passage lacks. Anthropic's contextual retrieval goes further by adding a generated explanation to each chunk before indexing. Whatever you choose, re-run your evaluation after every change to chunking rules.
Yes, because stuffing an entire corpus into a prompt is slow, expensive, and often less accurate than supplying the right evidence. Retrieval also keeps answers auditable and fresh without retraining, a trade-off covered in our comparison of <a href="https://www.aiplusinfo.com/blog/retrieval-augmented-generation-vs-fine-tuning/" target="_blank" rel="noopener">retrieval augmented generation versus fine-tuning</a>. Organizations are also merging search and generation, as described in coverage of <a href="https://www.aiplusinfo.com/blog/bridging-the-gap-how-enterprise-search-and-llms-are-revolutionizing-knowledge-management/" target="_blank" rel="noopener">enterprise search and LLMs</a>. Hybrid retrieval with reranking is the layer that decides which passages reach the model.
Graphs and memory stores add structure that text similarity alone cannot capture, such as relationships between entities and facts learned in earlier sessions. They usually complement hybrid retrieval instead of replacing it outright in production systems. See the explainer on a <a href="https://www.aiplusinfo.com/blog/semantic-knowledge-graph-for-llm-agents/" target="_blank" rel="noopener">semantic knowledge graph for LLM agents</a> for one design. The article on <a href="https://www.aiplusinfo.com/blog/ai-agent-memory-architecture-explained/" target="_blank" rel="noopener">AI agent memory architecture</a> covers persistence and recall patterns.
Apply access-control filters inside both the lexical and vector queries so users only ever see documents they may open. Treat retrieved text as untrusted input to the language model, since documents can contain injected instructions. Delete content from both indexes, caches, and logs when a deletion request arrives. Review the whole retrieval path in security assessments, not only the prompt.