Introduction
Synthetic data for fine-tuning: benefits, risks and workflow has become a core skill for any team that adapts language models to private tasks. The reason is simple, because NVIDIA reported that over 98 percent of the alignment data behind Nemotron-4 340B was synthetic. That single figure shows how far the practice has moved from hobby experiments to production engineering. Instead of paying annotators to write thousands of instruction and response pairs, teams now prompt a strong teacher model to draft them and then filter the output hard. The economics are striking, since Stanford built the 52,000-example Alpaca set for under $500 in API fees. The risks are just as real, because models trained on their own outputs can lose rare knowledge and drift toward bland, repetitive text. This guide explains what the technique is, where it works, where it fails, and how to build a safe pipeline. Along the way you will find verified numbers from primary papers, an interactive cost and mix estimator, and a six-step workflow you can run this week.
Quick Answers on Synthetic Data for Fine-tuning
What is synthetic data for fine-tuning?
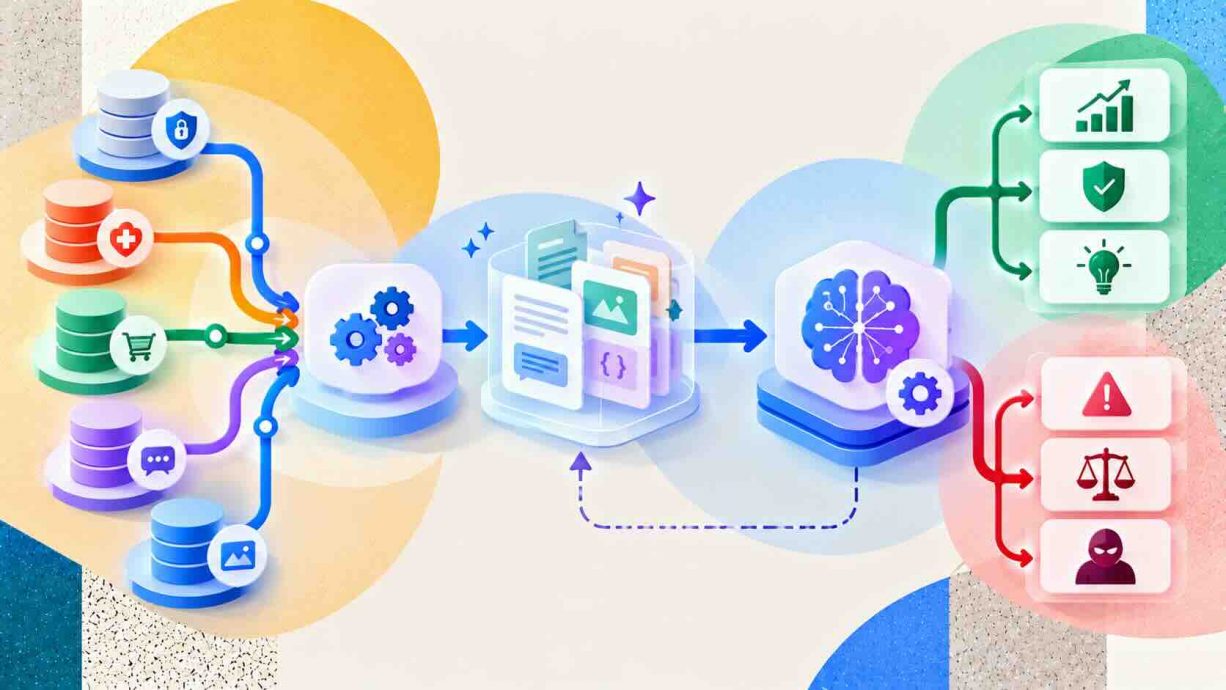
Synthetic data for fine-tuning is training text, such as instruction and response pairs, generated by a stronger model instead of written by people, then filtered and used to adapt a smaller model to a task.
What are the main risks of synthetic data?
The main risks are model collapse from recursive training, amplified bias and hallucinations inherited from the teacher, benchmark contamination, and license limits. Keeping real data in the mix and filtering hard reduces every one of them.
What is the basic synthetic data workflow?
Write 50 to 100 gold seed examples, generate candidates with a teacher model, deduplicate and judge them, mix with real data, fine-tune with LoRA, then evaluate on held-out real examples.
Key Takeaways
- Synthetic data for fine-tuning trades expensive human labeling for cheap teacher-model generation, so quality filtering becomes the main engineering job.
- Model collapse is driven by replacing real data with generated data, so always keep and accumulate real examples alongside synthetic ones.
- A small, diverse, well-judged dataset of a few thousand examples usually beats a huge raw dump of unfiltered generations.
- Diversity of sources, prompts, and temperatures matters as much as volume, and it needs to be measured, not assumed.
Table of contents
- Introduction
- Quick Answers on Synthetic Data for Fine-tuning
- Key Takeaways
- What Is Synthetic Data for Fine-tuning?
- Why Teams Turn to Synthetic Data Instead of Human Labels
- From Self-Instruct to Textbook Corpora: A Short History
- The Main Families of Synthetic Data Generation
- Teacher Models, Seeds, and Prompt Design
- Quality Filtering, Deduplication, and Judging
- Measuring Diversity and Coverage in Generated Datasets
- Cost Economics Compared With Human Annotation
- Where Synthetic Data Helps Most Across Domains and Tasks
- The Risks of Synthetic Data: Model Collapse, Bias, and Contamination
- Legal, Privacy, and Ethical Questions Around Generated Data
- Putting Real and Synthetic Data Together at Sensible Ratios
- Agentic Workflows That Generate and Verify Data Automatically
- Evaluating Fine-tuned Models Trained on Synthetic Data
- Common Mistakes and How Teams Recover
- The Future of Synthetic Data in Model Training
- How to Build a Synthetic Data Pipeline for Fine-tuning Step by Step
- Key Insights
- Synthetic Data Fine-tuning in Practice: Three Working Examples
- Lessons From Three Case Studies in Synthetic Data Training
- Common Questions About Synthetic Data for Fine-tuning
What Is Synthetic Data for Fine-tuning?
Synthetic data for fine-tuning: benefits, risks and workflow begins with a simple idea: a stronger teacher model generates training examples, a filter keeps the good ones, and a smaller student model learns from them.
An Interactive From AIplusInfo
What would your synthetic data pipeline cost?
Move the sliders to see how dataset size, real-data share, and filter yield change the bill and the collapse risk.
5,000
25%
25%
Commercial API
Example mix
1,250 real + 3,750 synthetic
Generate about 15,000 candidates
Hybrid pipeline cost
$3,975 to $12,725
Human labels for the real share plus generation and filtering
All-human cost
$15,000 to $50,000
About 74% cheaper with the hybrid approach
Collapse risk signal
Lower
Meets the 25% real-data floor suggested in the PremAI guide
Assumptions: human labels cost $3 to $10 per example, derived from the PremAI estimate of $15,000 to $50,000 per 5,000 examples. The API figure of $0.01 per candidate follows Stanford’s under-$500 cost for 52,000 Alpaca examples. The open-weight figure of $0.002 is an illustrative GPU estimate, and filtering adds 50% to generation cost.
Why Teams Turn to Synthetic Data Instead of Human Labels
Human annotation is the slowest and most expensive part of most fine-tuning projects. A 2026 guide from PremAI estimates that 5,000 expert-written examples cost between $15,000 and $50,000 and take weeks to deliver. The same guide puts teacher-model generation at roughly $50 to $500 and a few hours of compute. That gap of roughly one hundred times explains why startups and enterprises alike now begin with generated data. Speed matters as much as price, because a team can regenerate a whole dataset overnight after changing the task definition. Human labels must be commissioned and reviewed again every time the schema shifts.
Coverage is the second reason that teams choose to generate their training data. Real logs rarely contain the rare cases a model most needs to handle, such as refusals, long-tail edge cases, or safety-critical errors. A generator can be told to produce those cases on demand, in the exact format the model must output. Teams that already understand how data labeling drives model performance will recognize the benefit, since label quality and label coverage both shape final accuracy. Privacy is a third reason, because generated text can stand in for customer records that legal teams will not release.
Synthetic data is best understood as a way to buy coverage and speed, not a way to avoid thinking about quality. Control is a further benefit, since you choose the tone, length, and schema of every example. A model that must always answer in strict JSON can be trained on thousands of generated JSON answers that a parser has already verified. Those advantages explain the steady rise of generated data in open model releases. The same trend hides a catch, because volume without verification only produces confident noise at scale. The rest of this guide is about adding that verification.
From Self-Instruct to Textbook Corpora: A Short History
Looking back at how the practice began, the turning point was the Self-Instruct method published in late 2022. Its authors started with a small pool of human-written seed tasks and asked GPT-3 to invent new instructions and answers. After filtering out near duplicates, they fine-tuned GPT-3 on the result. The paper reports a 33 point absolute gain on Super-NaturalInstructions, which brought the model to roughly the level of InstructGPT-001. A human evaluation on novel tasks still left it about 5 points behind that commercial model. The lesson was clear from the start: generated data can close most of a gap, but not all of it.
Stanford turned that recipe into a public experiment in March 2023. The Alpaca project generated 52,000 instruction demonstrations with text-davinci-003 for under $500 and fine-tuned a 7B LLaMA model in about three hours on eight 80GB A100 GPUs. Microsoft researchers then pushed a different idea, which was to generate textbook-style material rather than chatty instructions. Their phi models showed that a small network trained on carefully filtered and synthesized text can punch above its weight. Later work such as Magpie removed the human seeds entirely and let aligned models write their own prompts. Each step in this history replaced a human bottleneck with a model, then added a stricter filter to compensate.
The Main Families of Synthetic Data Generation
Beyond the history, practitioners today choose among a handful of generation families, and each one suits a different goal. Seed expansion is the oldest family, where a few hundred human examples are shown to a teacher that writes many variations. Evolution methods such as Evol-Instruct take an existing instruction and rewrite it to be harder, longer, or more constrained. Both approaches keep a human fingerprint, because the seeds define the style and topics that the teacher will imitate. That makes them reliable for narrow business tasks and weaker for open-ended chat.
Distillation is the second family, where the teacher answers real or generated prompts and the student learns from those answers. Some pipelines ask the teacher to explain its reasoning step by step, so the student sees the chain of thought and not only the final answer. A third family removes seeds altogether, and Magpie is the best known example. It prompts an aligned model with only its chat template so the model invents a user question by itself, then answers it. The authors generated about 4 million conversations this way and kept 300,000 after filtering.
Persona-driven generation is the fourth family, and it attacks the diversity problem directly. The PremAI guide notes that the Persona Hub collection holds about one billion personas, which can be injected into prompts so that the same task is asked in countless voices. A teacher asked to write a billing question as a retired teacher and as a hospital administrator will produce very different text. Programmatic templates form a fifth family, useful when the structure is rigid, such as SQL queries, API calls, or form filling. Templates are cheap and perfectly labeled, but they sound mechanical unless a model rewrites the surface wording.
Verifiable domains deserve a family of their own, because code and math allow automatic checking. A teacher can propose many solutions, a test suite or answer checker keeps only the correct ones, and the student trains on survivors. This rejection sampling approach is far safer than trusting a judge model, since correctness is measured rather than guessed. Teams should prefer verifiable generation whenever the task allows it and fall back to judged generation only when it does not. Classic data augmentation in machine learning is a cousin of these methods, but it perturbs existing examples instead of inventing new ones.
Teacher Models, Seeds, and Prompt Design
Turning to the practical choices, the teacher model sets the ceiling for everything that follows. A teacher should be clearly stronger than the student on the target task, and it should be allowed by its license to produce training data. Open-weight teachers served locally remove per-token fees and many contractual worries. Commercial APIs give higher raw quality but raise cost and terms-of-service questions that legal teams should review early. Whatever you pick, record the model name, version, and settings for every batch.
Seeds are the next lever, and quality beats quantity here. The PremAI guide recommends writing 50 to 100 gold examples by hand with domain experts before generating anything, and the original Self-Instruct work used 175 seed tasks. Each seed should show the exact format, tone, and level of detail you want in the final model. Spend time on the awkward cases too, such as a polite refusal, an ambiguous request, or an input with missing fields. A weak seed set teaches the teacher to copy its own blind spots across thousands of outputs.
Prompt design deserves the same care as the seeds, because the generation prompt is effectively the specification of your dataset. State the task, the output schema, the audience, and the length in plain words. Rotate several prompt templates and show different random subsets of seeds each time, so the teacher does not lock onto one pattern. Keep sampling temperature moderate to high, since values below about 0.5 push the model toward its most probable phrasing and reduce variety. Teams that later train the student on a workstation can follow a walkthrough on fine-tuning models at home with Axolotl to complete the loop.
Quality Filtering, Deduplication, and Judging
Building on those choices, raw generations are never ready for training, and the filter stack is where most of the value is created. The PremAI example pipeline starts with exact deduplication, which removes about 5 percent of a 100,000-example run, and semantic deduplication with embeddings, which removes about 20 percent. Length limits and language identification trim another 10 percent and 5 percent. Instruction-following difficulty scoring then keeps only the top quarter or so, and a judge model removes low scorers. Magpie shows the same logic at larger scale, since its authors kept 300,000 of roughly 4 million generated conversations.
Judging deserves special caution because a judge is itself a language model with preferences. Ask it for narrow, rubric-based scores such as factual accuracy, format compliance, and helpfulness, and keep only examples above a threshold like 3.5 out of 5. Our guide on how to evaluate outputs with an LLM judge covers rubric design and bias checks in detail. Small and clean sets can win decisively, as the LIMA study showed with only 1,000 curated examples on a 65 billion parameter model. Always finish by reading a random sample of 5 to 10 percent of the surviving data yourself. Human review catches the odd failures that automated scores miss.
Measuring Diversity and Coverage in Generated Datasets
Stepping back from filtering, a clean dataset can still be dangerously narrow, which is why diversity must be measured. The study Synthetic Eggs in Many Baskets compared human and generated instruction data across several teacher models. It found lexical diversity of 79.60 for synthetic text against 89.15 for human text, using a score based on Self-BLEU. Semantic diversity was closer, at 0.9507 against 0.9713, so the generated data was not hopelessly repetitive. Synthetic responses were also much longer, averaging 243.2 words compared with 78.5 for human answers.
Those numbers point to two habits that every team should adopt early. First, track simple statistics on every batch, such as type-token ratio, n-gram entropy, and the spread of response lengths. A sudden drop in entropy between batches is an early warning that the teacher has settled into a rut. Second, check topic coverage by embedding the prompts, clustering them, and counting how many clusters each source fills. Empty clusters show where the next generation round should aim.
The same study found that mixing several teacher models gave a better proxy for human text than using a single source. Multi-source fine-tuning gave lower perplexity on a human-written test set than single-source fine-tuning, and it cut self-preference bias in one judge from 0.193 to 0.159. Using two or three different teachers is a cheap form of insurance against one model's habits. Pair those checks with the broader essential metrics for AI data quality so that completeness, consistency, and freshness are tracked alongside diversity. Treat the resulting dashboard as a release gate for every dataset version.
Cost Economics Compared With Human Annotation
Looking at the numbers, the cost gap between people and teacher models is the headline reason this field exists. Alpaca's authors reported spending under $500 on API calls to produce 52,000 demonstrations, plus under $100 of cloud time for the 3-hour training run. The PremAI guide estimates a minimum viable pilot at $50 to $200 in API and GPU spend over roughly one week. It also cites a Hugging Face analysis in which open-weight annotators cost about $2.70 for work that GPT-4 annotators priced near $3,061. Even allowing for rough accounting, the order of magnitude is not in doubt.
Hidden costs deserve equal attention before you celebrate those savings. Filtering consumes embedding compute and judge calls, and a strong judge can cost nearly as much as the generator did. Human review of a 5 to 10 percent sample still needs expert time. Building a trustworthy held-out test set of real examples is a fixed expense that never goes away. A fair budget treats generation as the cheap step and verification as the step where real money and expertise are spent. Teams serving the finished model should also plan ways to reduce LLM inference costs, because a smaller fine-tuned student often exists precisely to cut that bill.
Where Synthetic Data Helps Most Across Domains and Tasks
Given the economics, the next question is where the technique actually pays off, and the answer is uneven. Code is the clearest success, because tests can verify every generated solution. Microsoft's phi-1 model reached 50.6 percent pass@1 on HumanEval with only 1.3 billion parameters after training on filtered web text plus about 1 billion tokens of GPT-3.5 textbooks. Its successor phi-1.5 reached common-sense performance comparable to models about five times larger, according to the authors. Math follows the same pattern, since final answers can be checked automatically.
Structured output is another strong fit, including JSON extraction, SQL generation, tool calling, and form filling. A parser or schema validator can reject malformed generations instantly, so the surviving data is clean by construction. Customer support and internal-assistant tuning also benefit, because generated dialogues can teach tone, escalation rules, and refusal behavior without exposing real tickets. Safety training is a further use, where teams generate adversarial prompts and ideal refusals at a volume no red team could write by hand. In each case the common thread is a cheap, reliable way to check the output.
Synthetic data helps less when the goal is injecting new facts, since a teacher cannot reliably invent knowledge that it does not hold. Product catalogs, policies, and fast-changing documentation are better served by retrieval than by weights, as our comparison of retrieval augmented generation versus fine-tuning explains. Fine-tuning on generated question and answer pairs about a document tends to teach the style of the answers more than the content. Open-ended creative writing and broad world knowledge also resist improvement, because quality is subjective and the teacher's own limits cap the student. Use synthetic data to shape behavior and format, and use retrieval to supply facts.
Rare-language and low-resource settings sit in the middle, with promising but mixed results that depend heavily on teacher quality. Translation and back-translation of existing examples can seed those languages, provided native speakers review a sample. Specialized professional domains such as medicine, law, and finance add a further constraint, because a confidently wrong generated example can be actively harmful. Experts should therefore write the seeds and audit the output in those fields. The more expensive an error is, the larger the human review share should be.
The Risks of Synthetic Data: Model Collapse, Bias, and Contamination
Despite the benefits, the risks are well documented, and the best known is model collapse. In a widely covered Nature study, researchers trained language models recursively on text produced by earlier generations. By the ninth generation a prompt about medieval architecture produced a list of jackrabbits, and nearly all tested models showed repeating phrases. The authors concluded that collapse is likely when models learn from previous generations, though they also noted that carefully filtered generated data is not impossible to use. Our own explainer on what happens when AIs train on AIs covers the mechanism in plain language.
Bias and error inheritance form the second family of risk. A teacher passes along its hallucinations, stereotypes, and blind spots, and a student trained on thousands of such examples learns them as facts. The Alpaca authors stated plainly that hallucination was a common failure mode of their model, even compared with the teacher it learned from. Judge models add self-preference, and the Synthetic Eggs study measured a self-preference bias of 0.258 for a vanilla 8B judge. That is a reminder that using one model family to generate, filter, and grade your data creates a closed loop of shared habits.
Contamination is the quiet third risk, because generated data can leak benchmark questions into training and inflate your evaluation scores. Teachers may have memorized public test sets, and they can reproduce near copies when prompted with similar tasks. The wider web is also filling with machine text, and the PremAI guide reports that 74.2 percent of newly created pages in April 2025 contained some AI-generated text. Fresh scrapes therefore need the same scrutiny as a deliberate synthetic set. Decontaminate against every benchmark you plan to report and keep a private test set that has never touched a model.
Legal, Privacy, and Ethical Questions Around Generated Data
Moving on from technical risk, legal and ethical questions deserve a seat at the design table. Many commercial model providers restrict using their outputs to train competing models, so read the terms of every teacher before you generate a single example. Open licenses vary too, and NVIDIA's license for Nemotron-4 explicitly permits using the model's outputs, which is why that family is popular for data generation. Record which teacher produced which batch so a licensing change or dispute can be handled without retraining everything. This article is general information and not legal advice, so involve counsel for commercial projects.
Privacy is often presented as the main upside of synthetic data, but the protection is not automatic. A generator seeded with real customer records can memorize and reproduce them, which turns a privacy tool into a leak. Techniques such as differential privacy, strict de-identification, and membership-inference tests help, and our overview of privacy challenges and solutions in AI is a good starting point. Ethical practice also includes asking what bias a teacher may spread, a risk illustrated by the story of how bad training data turns chatbots toxic. Document your data sources, disclose synthetic training where it affects users, and keep a human accountable for each release.
Putting Real and Synthetic Data Together at Sensible Ratios
From there, the central design decision is how to mix real and generated examples. The most important research result in this area is about accumulation, not volume. Gerstgrasser and colleagues showed that performance degrades when each generation replaces real data with synthetic data. When successive synthetic data is accumulated alongside the original real data, collapse is avoided. In a simplified linear-model analysis they also proved that test error stays bounded under accumulation. The practical rule is never to discard your real data. It is the first rule in any sound plan for synthetic data for fine-tuning: benefits, risks and workflow.
How much real data is enough is less settled, and honest answers are ranges rather than formulas. The PremAI guide recommends a real-data floor of at least 25 percent in the final mix, and it describes 20 to 30 percent as a common target. Narrow tasks with strong verifiers can tolerate less, while open-ended assistants and safety behavior should lean on more human data. Treat any ratio as a starting hypothesis, then test two or three mixes on a held-out set of real examples. The estimator earlier in this article lets you explore cost and mix trade-offs before you commit compute.
Watch the rare cases and the tails of your distribution, not just the average score. The same guide advises tracking accuracy on rare queries before and after each training round, because falling tail accuracy with a stable average is an early collapse signal. Mixing sources helps as well, so blend generations from several teachers and several prompt templates rather than one. Record the provenance of each example, including teacher, prompt template, and batch date, so that bad batches can be removed later. Freeze a versioned manifest of the exact mix for every released model.
Agentic Workflows That Generate and Verify Data Automatically
On top of single-shot generation, agentic workflows add planning, tool use, and self-checking to the data loop. A generator agent drafts an example, a verifier agent runs code, queries a database, or checks a schema, and a critic agent decides whether to keep, repair, or discard it. Failed examples can be sent back with the error message, which often yields a correct revision at a fraction of the human cost. NVIDIA's Nemotron-4 program is a public template, since its alignment pipeline paired a generator with a dedicated reward model to score outputs. Our guide to agentic AI for smarter workflows covers the orchestration patterns behind such loops.
Agentic data work also produces a special kind of training example, namely full multi-step trajectories. A simulated user, a tool environment, and a scoring function can create thousands of tool-calling conversations with known outcomes. Those trajectories teach a student when to call a tool, how to read an error, and when to stop. The same discipline applies as everywhere else, which means verification must be independent of generation. If the verifier is the same model with the same prompt, it will approve its own mistakes and the loop will amplify them. Log every accepted and rejected trajectory so you can audit what the loop considers success.
Evaluating Fine-tuned Models Trained on Synthetic Data
Shifting to measurement, evaluation is where synthetic projects succeed or quietly fail. Build a held-out test set of real, human-written examples before generation begins, and never let teacher outputs touch it. Compare the fine-tuned student against the base model given a strong system prompt, because prompting alone sometimes closes most of the gap. Report accuracy on common cases and rare cases separately, so that a rise in the average cannot hide a drop in the tails. Add task-specific automatic checks such as schema validity or unit-test pass rate wherever they exist. These checks keep any synthetic data for fine-tuning: benefits, risks and workflow review tied to measurable evidence.
Benchmarks can disagree, which is why one score is never enough. In the Magpie paper, the Magpie-Pro-300K-Filtered model scored 25.08 on AlpacaEval 2 against 22.92 for the official Llama-3-8B-Instruct. On Arena-Hard, the same comparison reversed, with 18.9 for the Magpie model and 20.6 for the official one. That split is a healthy reminder to use several metrics plus human review rather than trusting a single leaderboard. Choose evaluations that match the real task, and treat public benchmarks as sanity checks only.
Safety and fairness checks must be part of the suite, not an afterthought. The Synthetic Eggs study found that about 39.4 percent of responses from one small model fell in a danger zone of high quality and high harmfulness under adversarial prompts. Run refusal and jailbreak tests before and after fine-tuning, and compare the results with the base model. Follow a structured process such as how to audit models for bias to test fairness across user groups. Block the release if a safety metric regresses, no matter how good the headline accuracy looks.
Common Mistakes and How Teams Recover
Rounding out the technical picture, a short list of mistakes accounts for most failed projects. The first is trusting a single teacher, which bakes one model's habits into every example. The second is skipping deduplication, which lets near copies dominate training and makes the student overfit to a few phrasings. The third is training on everything the generator produced, when the evidence says a smaller filtered subset usually performs better. A fourth is discarding real data in a rush to scale, which is the exact setup that research links to collapse. Each of these errors shows why synthetic data for fine-tuning: benefits, risks and workflow must be managed as one connected system.
Other errors are quieter and therefore much easier for busy teams to miss. Teams often let the same model generate and judge, forgetting the self-preference effect, or they set sampling temperature so low that outputs converge. Leaked boilerplate such as "As an AI language model" can also flood a dataset and make the student sound robotic. Recovery starts with provenance, because a dataset manifest lets you find the bad batch and rebuild without starting over. Re-run deduplication, add a second teacher, restore the real-data floor, and compare against a frozen baseline model. Because the student is built on pretrained weights, the broader principles of transfer learning in machine learning still apply when you retrain.
The Future of Synthetic Data in Model Training
Looking ahead, analysts expect generated data to take over more of the training pipeline. Gartner has stated that by 2030 synthetic data will completely overshadow real data in AI models. Whether or not that exact milestone arrives, open releases already point the same way, from Nemotron-4's 98 percent synthetic alignment data to the textbook-style corpora behind the phi family. The open web is meanwhile filling with machine text, which makes clean human data scarcer and more valuable. Teams that own genuine, well-governed human data will hold a lasting advantage in synthetic data for fine-tuning: benefits, risks and workflow as machine text spreads.
Three technical trends look durable over the next several years. First, generation will be agentic and verifier-driven, with tools and tests deciding what survives instead of a single judge prompt. Second, source diversity will become a standard dial, with pipelines blending many teachers, personas, and temperatures by default. Third, provenance tracking will mature, so that every training example carries a record of how it was made and which license applies. Regulators and auditors are likely to ask for exactly those records.
The long-run winner is not the biggest synthetic dataset but the best-governed one. Smaller students trained on curated generations will keep moving from data centers to laptops and phones. Teams that want to understand the full stack can start with our step-by-step guide to building your own LLM step by step. The story of synthetic data for fine-tuning: benefits, risks and workflow will keep evolving, but the core discipline of generating cheaply and verifying carefully is unlikely to change. The next section turns that discipline into a concrete pipeline.
Chart From AIplusInfo
Filtered synthetic data beat larger public datasets
AlpacaEval 2 length-controlled win rate after supervised fine-tuning of a Llama-3-8B base model. Higher is better.
Source: Table 1 of the Magpie paper on alignment data synthesis from scratch. Blue bars mark the Magpie datasets. On Arena-Hard the official model still leads, so the two views disagree.
How to Build a Synthetic Data Pipeline for Fine-tuning Step by Step
Step 1 - Define the task and write gold seeds
Next, define the task in one precise sentence before you touch any model. A good definition names the input, the output format, the audience, and the failure modes that matter, such as a wrong currency or a missing field. Write down how success will be measured, for example exact-match accuracy on extracted fields or a rubric score from reviewers. Then collect between 50 and 100 real or hand-written gold examples with a domain expert. Split off at least 200 real examples as a locked test set that no generator will ever see. Store everything in JSON Lines files so that each record is one object on one line.
Each gold example should demonstrate the exact format and tone you want the final model to produce. Include a handful of difficult cases, such as ambiguous inputs, missing fields, and polite refusals. Tag every seed with a topic label so that you can check coverage by category later. A typical seed record looks like the snippet shown directly below this paragraph. Keep the instruction, input, and output fields consistent across the whole file.
{"id": "seed-001", "topic": "invoices", "instruction": "Extract the invoice number and total as JSON.", "input": "Invoice INV-2041. Total due: 1250.00 EUR. Net 30.", "output": "{\"invoice_number\": \"INV-2041\", \"total\": 1250.0, \"currency\": \"EUR\"}"}Step 2 - Generate candidates with a teacher model
Generate candidate examples by showing the teacher a few random seeds and asking for new ones. Run the teacher behind an OpenAI-compatible server such as vLLM, or call a hosted API only if its terms allow training use. Sample four seeds per request and rotate several prompt templates to keep variety high. Use a temperature between 0.7 and 1.0 so the model does not collapse onto its most likely phrasing. Pro tip: write the teacher name, template id, temperature, and timestamp into every record, because you will need that provenance later. Generate two to three times more candidates than your final target, since filtering will remove most of them.
import json, random, time
from openai import OpenAI

client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
seeds = [json.loads(line) for line in open("seeds.jsonl")]
TEACHER = "your-teacher-model-name"
TEMPLATES = [
    "Write {n} new, varied examples in the same JSON format as the samples.",
    "Invent {n} harder examples with messy input and edge cases, same JSON format.",
]

with open("candidates.jsonl", "w") as out:
    for i in range(2000):
        shots = random.sample(seeds, 4)
        template_id = i % len(TEMPLATES)
        prompt = TEMPLATES[template_id].format(n=5) + "\n\nSamples:\n"
        prompt += "\n".join(json.dumps(s) for s in shots)
        resp = client.chat.completions.create(
            model=TEACHER,
            messages=[{"role": "user", "content": prompt}],
            temperature=0.9,
        )
        record = {"raw": resp.choices[0].message.content, "teacher": TEACHER,
                  "template": template_id, "temperature": 0.9, "ts": time.time()}
        out.write(json.dumps(record) + "\n")
Step 3 - Deduplicate with embeddings
Raw generations contain many near copies, so deduplication is the first filter to run. Parse each response into individual examples and drop any that fail JSON parsing. Remove exact duplicates with a simple hash of the normalized instruction and input. Then embed every instruction and remove examples whose cosine similarity to an earlier kept example exceeds a threshold such as 0.90. The PremAI example pipeline removed about 5 percent of records at the exact stage and about 20 percent at the semantic stage. Run this stage before any model-based judging, because duplicates inflate the cost of every later step.
Tune the threshold by reading sampled pairs near the cutoff rather than trusting a default. If pairs at 0.88 look like genuine variations, raise the threshold, and if pairs at 0.93 look identical, lower it. Keep a log of what was removed so you can inspect the decisions later. The snippet below uses a greedy pass, which is fine up to roughly 100,000 examples. Larger sets should use an approximate nearest neighbor index instead, since a greedy pass over a million rows becomes far too slow.
import json
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer("all-MiniLM-L6-v2")
rows = [json.loads(line) for line in open("parsed.jsonl")]
texts = [r["instruction"] + " " + r.get("input", "") for r in rows]
emb = model.encode(texts, convert_to_tensor=True, normalize_embeddings=True)

kept_idx = []
for i in range(len(rows)):
    if kept_idx:
        sims = util.cos_sim(emb[i], emb[kept_idx])[0]
        if float(sims.max()) > 0.90:
            continue
    kept_idx.append(i)

with open("deduped.jsonl", "w") as out:
    for i in kept_idx:
        out.write(json.dumps(rows[i]) + "\n")
print(len(rows), "->", len(kept_idx))
Step 4 - Judge and filter with a rubric
Judging adds a second quality filter on top of the deduplication pass. Ask a strong model to score each example from 1 to 5 on accuracy, format compliance, and helpfulness, and to return JSON only. Use a different model family from the generator when possible, which reduces the self-preference effect. Keep only examples whose average score is at least 3.5, then sample 5 to 10 percent of the survivors for human review. Wherever the task has an automatic check, such as a JSON schema or unit tests, apply it first because it is cheaper and more reliable than any judge.
import json
from openai import OpenAI

judge = OpenAI(base_url="http://localhost:8001/v1", api_key="not-needed")
RUBRIC = ("Score the example from 1 to 5 for accuracy, format and helpfulness. "
          'Reply with JSON only: {"accuracy": n, "format": n, "helpfulness": n}')

def score(example):
    resp = judge.chat.completions.create(
        model="your-judge-model-name",
        messages=[{"role": "system", "content": RUBRIC},
                  {"role": "user", "content": json.dumps(example)}],
        temperature=0,
    )
    s = json.loads(resp.choices[0].message.content)
    return (s["accuracy"] + s["format"] + s["helpfulness"]) / 3

with open("judged.jsonl", "w") as out:
    for line in open("deduped.jsonl"):
        ex = json.loads(line)
        try:
            ex["score"] = score(ex)
        except Exception:
            continue
        if ex["score"] >= 3.5:
            out.write(json.dumps(ex) + "\n")
Step 5 - Mix with real data and format for training
Mixing is the step where you protect the student model from collapse. Load your filtered synthetic examples and your real examples, and build the training set so that real data is never below your chosen floor. A floor of 25 percent real data is a sensible starting point, and the accumulation research says you should never discard real examples. Convert each record into the chat format your training library expects and shuffle with a fixed seed. Write a manifest that records the counts, the ratio, the teacher names, and the file hashes for this exact version.
import json, random

random.seed(7)
real = [json.loads(l) for l in open("real.jsonl")]
synth = [json.loads(l) for l in open("judged.jsonl")]
REAL_FLOOR = 0.25

max_synth = int(len(real) * (1 - REAL_FLOOR) / REAL_FLOOR)
synth = random.sample(synth, min(len(synth), max_synth))

def to_chat(r):
    user = r["instruction"] + ("\n\n" + r["input"] if r.get("input") else "")
    return {"messages": [{"role": "user", "content": user},
                         {"role": "assistant", "content": r["output"]}]}

mixed = [to_chat(r) for r in real + synth]
random.shuffle(mixed)
with open("train.jsonl", "w") as out:
    for m in mixed:
        out.write(json.dumps(m) + "\n")
print({"real": len(real), "synthetic": len(synth), "total": len(mixed)})
Step 6 - Fine-tune with LoRA and evaluate on real data
Fine-tune the student with low-rank adapters so that the run fits on a single GPU and takes roughly 4 to 12 hours instead of days. The TRL SFT trainer documentation shows how to pass a LoRA configuration to the trainer, and adapter training typically uses a higher learning rate than full fine-tuning. Choose a small rank, a few epochs, and a validation split drawn only from real data. Watch the validation loss, because a falling training loss with a flat validation loss signals overfitting to generated phrasing. Save the adapter, the training config, and the dataset manifest together so that the run can be reproduced exactly. Pin library versions in a requirements file for the same reason.
Evaluation closes the loop, and it must run on the locked real test set from Step 1. Score the fine-tuned student, the untouched base model with a strong system prompt, and the previous release side by side. Report common and rare cases separately, and run your safety and refusal checks before anyone ships the adapter. If tail accuracy drops while the average rises, return to Step 5 and raise the real-data floor. Repeat the loop until the student beats the baseline on real data, because that result is the proof that your synthetic data for fine-tuning: benefits, risks and workflow plan works. A held-out real set of roughly 10 percent of your gold examples is usually enough to expose regressions.
from datasets import load_dataset
from peft import LoraConfig
from trl import SFTConfig, SFTTrainer

train = load_dataset("json", data_files="train.jsonl", split="train")
trainer = SFTTrainer(
    model="your-student-model-name",
    train_dataset=train,
    args=SFTConfig(output_dir="student-lora", num_train_epochs=3,
                   learning_rate=1e-4, per_device_train_batch_size=4),
    peft_config=LoraConfig(r=16, lora_alpha=32, lora_dropout=0.05,
                           task_type="CAUSAL_LM"),
)
trainer.train()
trainer.save_model("student-lora")Recommended by AIplusInfo
Books and kits to go deeper
Hand-picked titles that map to the synthetic data workflow described above.
As an Amazon Associate, AIplusInfo earns from qualifying purchases.

Book
Hands-On Large Language Models: Language Understanding and Generation
Jay Alammar and Maarten Grootendorst walk through fine-tuning and generating text with LLMs, which supports the teacher and student steps covered above.
Buy on Amazon
Book
AI Engineering: Building Applications with Foundation Models
Chip Huyen covers dataset engineering, synthetic data and evaluation for foundation models, the same concerns this workflow raises.
Buy on Amazon
Book
Build a Large Language Model (From Scratch)
Sebastian Raschka builds and fine-tunes a GPT-style model in code, a useful base before training on instruction data you generate.
Buy on AmazonKey Insights
- NVIDIA reported that over 98 percent of the data in its Nemotron-4 340B alignment process was synthetic, showing that frontier-scale alignment can run almost entirely on generated examples.
- Stanford's Alpaca team generated 52,000 instruction demonstrations for under $500, proving that an instruction-following model no longer requires an annotation budget in the tens of thousands of dollars.
- Self-Instruct lifted GPT-3 by 33 absolute points on Super-NaturalInstructions, yet human evaluation on novel tasks still showed a gap of about 5 points to InstructGPT-001.
- Microsoft's phi-1 reached 50.6 percent pass@1 on HumanEval with 1.3 billion parameters, helped by roughly 1 billion tokens of synthetic textbooks among about 7 billion training tokens.
- The Magpie team kept 300,000 conversations out of roughly 4 million generated, a retention rate near 7.5 percent that shows how aggressively good pipelines must filter.
- Replacing real data with generated data causes decline, while accumulating synthetic data alongside real data avoided model collapse in the experiments reported by Gerstgrasser and colleagues.
- Synthetic responses averaged 243.2 words versus 78.5 for human answers, a verbosity gap that teams should control with explicit length limits in the generation prompt.
- Gartner predicts that by 2030 synthetic data will completely overshadow real data in AI models, which makes governance and provenance a strategic concern today.
Taken together, these figures describe a field where generation is cheap, filtering is decisive, and real data remains the anchor. The cost evidence from Alpaca and the PremAI guide shows why teams start with a teacher, while the retention rate in Magpie shows that most generated text is thrown away. Collapse research explains why the discarded real data should never be deleted, and diversity research explains why one teacher is rarely enough. Verifiable domains such as code let small models punch above their weight, whereas open-ended assistants need more human oversight. Anyone following the synthetic data for fine-tuning: benefits, risks and workflow outlined here should therefore invest first in verification, provenance, and held-out real evaluation.
| Dimension | Human annotation | Teacher distillation | Seed-free generation | Verifiable rejection sampling |
|---|---|---|---|---|
| Best for | Gold test sets, sensitive domains, nuanced judgment | Instruction following and style transfer | Broad general alignment data at scale | Code, math, structured output |
| Typical cost | $15,000 to $50,000 per 5,000 examples | $50 to $500 in teacher calls | Local GPU time for millions of drafts | Compute for many attempts per prompt |
| Speed | Weeks | Hours to days | Hours to days | Hours to days |
| Diversity | High but limited by annotator pool | Bounded by seeds and prompt templates | High, driven by the model's own prompts | Bounded by the prompt set |
| Quality control | Reviewer agreement and audits | Judge scores plus human sampling | Heavy filtering, about 7.5 percent kept in Magpie | Automatic tests and answer checkers |
| Main risk | Cost, delay, and inconsistent labelers | Inherited hallucination and teacher bias | Style drift toward the generating model | Weak tests that accept wrong answers |
| Privacy exposure | Annotators see raw data | Seeds may leak if copied from real records | Low, since no real records are needed | Low when prompts are public or synthetic |
| Typical dataset size | 1,000 to 10,000 curated examples | 2,000 to 52,000 examples | 300,000 filtered conversations | Thousands to millions of verified solutions |
| License concerns | Contractor agreements | Teacher terms of service apply | Model license applies to outputs | Model license applies to outputs |
Synthetic Data Fine-tuning in Practice: Three Working Examples
Stanford Alpaca and Its 52,000 Generated Instructions
Stanford's CRFM team used text-davinci-003 to generate 52,000 instruction-following demonstrations in the Self-Instruct style, then trained a 7B LLaMA model on them. The data cost under $500 in API fees, and the first training run took about 3 hours on eight 80GB A100 GPUs, which the team priced at under $100. The result was a model that behaved qualitatively like its much larger teacher on many everyday instructions. The authors still documented clear limits, including frequent hallucination, toxicity, and stereotypes, and they called hallucination a common failure mode. The team intended the release for academic research only, citing model licensing and safety concerns. The project's lasting contribution was showing that a few hundred dollars could replace a large annotation program.
Microsoft's phi-1 and Textbook-Quality Data
Microsoft researchers trained phi-1, a 1.3 billion parameter code model, on about 7 billion tokens of data. That mix combined roughly 6 billion tokens of filtered web code with about 1 billion tokens of GPT-3.5 generated textbooks and exercises. The model reached 50.6 percent pass@1 on HumanEval and 55.5 percent on MBPP, which was strong for its size. Quality filtering of the web portion mattered as much as the synthetic portion, so the gains cannot be credited to generation alone. A limitation is that the model specialized in Python coding and was not built as a general assistant. The approach also depends on the teacher writing accurate textbooks, which is a real cost and a real dependency. The follow-up phi-1.5 model, also 1.3 billion parameters, was reported by its authors to be comparable to models about five times larger on language tasks.
Magpie's Seed-Free Alignment Data
The Magpie team ran Llama-3-8B-Instruct and Llama-3-70B-Instruct with only the chat template as input, so the models invented user questions and then answered them. They generated 3 million and 1 million conversations respectively and filtered each set down to 300,000. Fine-tuning a Llama-3-8B base model on the filtered 70B set scored 25.08 on AlpacaEval 2, a lift of about 2 points over the 22.92 of the official Llama-3-8B-Instruct. The official model still led on Arena-Hard, with 20.6 against 18.9, so the win was not universal. The method depends on access to a strong aligned model, which limits who can reproduce it cheaply. Its data inherits that model's style and safety behavior, a trade-off worth testing before adoption.
Lessons From Three Case Studies in Synthetic Data Training
Case Study: NVIDIA's Nemotron-4 340B Alignment Pipeline
NVIDIA faced a familiar problem when it set out to align a 340 billion parameter model, because high-quality human preference data is slow and costly to collect at that scale. The team needed large numbers of diverse prompts, responses, and preference judgments without relying on a huge annotation workforce. Their solution was a synthetic data generation pipeline in which strong instruct models draft candidate answers and a dedicated reward model scores them. According to the technical report, over 98 percent of the data used in the alignment process was synthetically generated. The team released base, instruct, and reward models under an open license that permits using their outputs, and it open-sourced the generation pipeline. That made the recipe reproducible for outside teams that want to generate data for smaller students.
Several important limits deserve emphasis before any team copies this approach. The generators and the reward model still encode their own biases, and the report is vendor-authored, so independent replication matters. The models are large enough to need a single DGX H100 node with 8 GPUs even in FP8 precision, which puts them out of reach for many teams. Cost-conscious teams therefore use them as teachers for smaller students, as the authors themselves suggest. A 98 percent synthetic share also does not mean zero human input, since evaluation and the choice of what counts as good still rest on human judgment.
Case Study: Self-Instruct and the 33 Point Jump
The researchers behind Self-Instruct faced a bottleneck in 2022, because instruction tuning depended on human-written demonstrations that were costly and narrow in scope. Their solution was to bootstrap from a small pool of 175 human-written seed tasks, let GPT-3 propose new instructions and answers, and filter out invalid or near-duplicate items. Fine-tuning GPT-3 on the filtered data produced a 33 point absolute lift on Super-NaturalInstructions, reaching performance on par with InstructGPT-001. The impact was a recipe that dozens of later projects copied, including Alpaca. A human evaluation on expert-written novel tasks still left the model about 5 points behind InstructGPT-001. The method also inherits any errors in the base model's generations, so noise in the data remains a concern that filtering only partly removes.
Case Study: Synthetic Eggs and Source Diversity
Researchers Schaffelder and Gatt studied a problem that many teams overlook, which is that fine-tuning on data from a single teacher narrows the student's behavior. They built instruction datasets from several source models and fine-tuned Llama-3.1 models with LoRA on single-source and multi-source mixtures, then compared them with human-written data. Multi-source data lowered self-preference bias for an 8B judge to 0.159, against 0.193 for single-source data and 0.258 for the vanilla model. Lexical diversity of synthetic text reached 79.60 against 89.15 for human text, so a gap remained even with several teachers. The authors also found that about 39.4 percent of one small model's responses under adversarial prompts fell in a danger zone of high quality and high harmfulness. The study is limited to English, single-turn prompts, LoRA training, and Llama-3.1 targets, and its quality scores come from judge models, so results may not transfer to other settings.
Common Questions About Synthetic Data for Fine-tuning
Synthetic data for fine-tuning is training text produced by a model rather than collected from people. A teacher model drafts instruction and response pairs, a filter removes weak or duplicate items, and the survivors are used to adapt a smaller student model. The process turns an expensive annotation project into a mostly automated pipeline with human review at key checkpoints.
Narrow tasks often need only about 2,000 to 5,000 well-filtered examples, according to the PremAI guide. The LIMA study showed strong results from just 1,000 curated examples on a 65 billion parameter model. Larger general-purpose assistants use hundreds of thousands, as in the 300,000 conversations kept by Magpie. Quality and diversity matter more than raw volume in every case.
The PremAI guide estimates that 5,000 expert-written examples cost between $15,000 and $50,000, while teacher-model generation costs roughly $50 to $500. Stanford reported under $500 in API fees for the 52,000 Alpaca examples. Filtering, judging, human review, and a real test set add costs that should be budgeted from the start. The net saving is still large for most projects once everything is counted.
Model collapse is the loss of rare knowledge and variety that happens when models are trained recursively on generated data. A Nature study showed outputs degrading into repetitive nonsense after several generations. Research by Gerstgrasser and colleagues found that accumulating synthetic data alongside the original real data avoids collapse. Keep all real data, mix several teachers, and monitor accuracy on rare cases.
There is no universal ratio, so treat any number as a hypothesis to test. The PremAI guide suggests keeping at least 25 percent real data in the final mix, with 20 to 30 percent as a common range. Narrow tasks with strong automatic verifiers can tolerate less real data than open-ended assistants. Always compare candidate mixes on a locked set of real test examples.
Choose a teacher that is clearly stronger than your student on the target task and whose license allows training use. Open-weight models served locally reduce per-token cost and many contractual concerns. Using two or three different teachers is a cheap way to improve diversity and avoid one model's habits. Record the teacher name, version, and settings for every batch.
It depends on the provider's terms of service and on your jurisdiction, and some commercial providers restrict using outputs to train competing models. Some open licenses, such as the one NVIDIA uses for Nemotron-4, explicitly permit using model outputs. Read the terms of every teacher before generating data and keep provenance records. This article is general information and not legal advice, so consult counsel for commercial projects.
It can reduce exposure, but the protection is not automatic. A generator seeded with real customer records may memorize and reproduce them in its outputs. Techniques such as de-identification, differential privacy, and membership-inference testing help verify that no individual records leak. Fully synthetic data built from public or invented seeds carries the lowest risk.
Stack several filters together instead of relying on any single one of them. Start with exact and embedding-based deduplication, then apply length and language checks, schema or unit-test validation, and finally a rubric-based judge model. The PremAI example pipeline kept examples scoring at least 3.5 out of 5 and reviewed a random 5 to 10 percent by hand. Automatic checks should always run before judge models because they are cheaper and more reliable.
Judges are useful but biased, so they always need a few safeguards. The Synthetic Eggs study measured a self-preference bias of 0.258 for a vanilla 8B judge, which means models tend to favor their own style. Use a different model family from the generator, grade against a narrow rubric, and calibrate against human labels on a sample. Prefer verifiable checks over judges wherever the task allows them at all.
It works poorly for new facts, because a teacher cannot reliably invent knowledge it does not hold. Fine-tuning on generated question and answer pairs mostly teaches format and style. Retrieval is usually a better way to supply product details, policies, and fast-changing documents. Use synthetic data to shape behavior and retrieval to supply facts.
Evaluate on a locked set of real, human-written examples that no teacher has touched. Compare the student with the base model given a strong system prompt, and report common and rare cases separately. Add safety, refusal, and fairness tests, and decontaminate against public benchmarks. Use several metrics, because benchmarks such as AlpacaEval and Arena-Hard can disagree.
The PremAI guide outlines a four-week plan covering seeding, generation, filtering, and training with evaluation. A minimal pilot can run in about a week on a budget of roughly $50 to $200. Production pipelines take longer because of governance, review, and monitoring work. Starting with 50 to 100 gold seeds and a locked test set keeps the schedule realistic.