Introduction
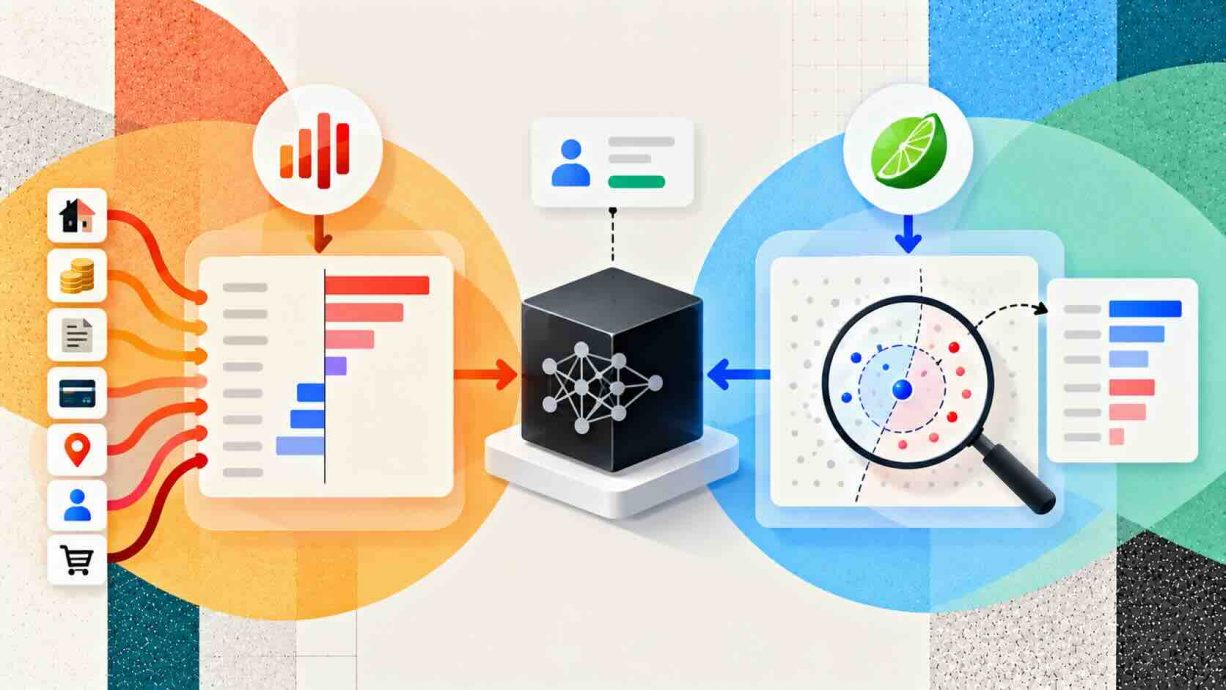
Few questions in machine learning matter more than why a model made its prediction, and this guide to Explainable AI (XAI) Methods: SHAP and LIME Explained answers it. BCC Research values the explainable AI market at USD 7.8 billion in 2024 and projects USD 22.6 billion by 2030, showing how quickly buyers now demand transparency. SHAP and LIME are the two post hoc techniques that most data science teams reach for first when a gradient boosted tree or neural network must justify a single decision. Both methods are model agnostic, which means they can explain almost any classifier or regressor without opening the model itself. They differ sharply in how they work, how much they cost to run, and how far their explanations can be trusted. This article explains the mechanics, the intuition behind the math, a working Python workflow, the published failure modes, and the regulatory pressure that makes all of it urgent. By the end you will know which method fits which problem and which warning signs mean an explanation should not be believed.
Quick Answers on Explainable AI (XAI) Methods
What is the difference between SHAP and LIME?
SHAP splits a prediction among features using Shapley values from game theory and supports local and global views. LIME fits a simple surrogate model around one prediction, so it runs faster but stays strictly local.
When should I use SHAP instead of LIME?
Use SHAP when you need consistent attributions, global summaries, or audit evidence, especially for tree models. Choose LIME for quick instance-level checks on text, images, or slow models where speed matters more than theory.
Are SHAP and LIME explanations always reliable?
No. SHAP and LIME both depend on the model, the background data, and random sampling, and published studies show explanations can be unstable, disagree with each other, or be manipulated. Treat them as evidence to test, not proof.
Key Takeaways
- SHAP gives theoretically grounded, additive feature attributions for local and global analysis, while LIME gives fast, sparse, local linear approximations.
- Neither method is a ground truth about the world, because both explain the model’s behavior and inherit its flaws, its correlations, and its blind spots.
- Explanations can disagree across methods, models, and random seeds, so serious teams compare several runs and report ranges instead of single plots.
- Regulators in lending and high-risk AI expect specific, accurate reasons, which makes validated explanations a compliance requirement rather than a nice extra.
Table of contents
- Introduction
- Quick Answers on Explainable AI (XAI) Methods
- Key Takeaways
- What Is Explainable AI and How Do SHAP and LIME Fit In?
- Why Black Box Models Demand Explanations
- Intrinsic Models, Post Hoc Methods, and Other Explainable AI Families
- How LIME Builds a Local Surrogate Explanation
- How SHAP Turns Shapley Values Into Feature Attributions
- SHAP and LIME Compared Across Seven Practical Dimensions
- Choosing Among Kernel, Tree, and Deep SHAP Explainers
- Putting SHAP and LIME to Work in a Python Pipeline
- Reading SHAP Plots and LIME Charts Without Fooling Yourself
- The Risks and Limits of Explainable AI Methods
- The Disagreement Problem and Fragile Explanations
- Ethics, Fairness, and the Danger of Explanation Washing
- Regulation and the Legal Case for Explanations
- Measuring Explanation Quality Before You Trust It
- Alternatives and Complements Beyond SHAP and LIME
- The Future of Explainable AI Practice
- Key Insights
- Explainable AI in Practice: Three Real Deployments
- Lessons From Three Explainable AI Case Studies
- Frequently Asked Questions on Explainable AI (XAI) Methods
What Is Explainable AI and How Do SHAP and LIME Fit In?
Explainable AI (XAI) Methods: SHAP and LIME Explained covers the techniques that reveal why a model made a prediction. SHAP assigns each feature Shapley-value credit, while LIME fits a simple local surrogate around one prediction.
An Interactive From AIplusInfo
Which Explainer Can Your Budget Afford?
Set the model family, table width, number of rows, and prediction latency to see how many model evaluations LIME and SHAP need.
Tree ensemble
30
1,000
2 ms
Recommended route
TreeSHAP
Model evaluations and wall-clock time
LIME
KernelSHAP
Model specific SHAP
Assumptions: LIME draws 5,000 samples per row, KernelSHAP uses 2 times the feature count plus 2,048 coalitions against a 50 row background, and DeepSHAP uses one pass per background row. These are planning estimates. For a measured reference, the LIME paper reports under 3 seconds for a 1,000 tree forest with 5,000 samples and about 10 minutes for one Inception image prediction.
Why Black Box Models Demand Explanations
Modern predictive models earn their accuracy by combining thousands of weak signals in ways no person can follow by hand. A gradient boosted ensemble may contain hundreds of trees, and a neural network may hold millions of weights, so inspecting the parameters tells an analyst almost nothing. A model that cannot justify an individual decision is a liability in any setting where someone can appeal the outcome. Loan applicants, patients, and job seekers all have a stake in knowing which facts about them drove a score. Engineers have their own reasons to ask, because an unexplained prediction is nearly impossible to debug once it turns out to be wrong. Explainable AI was invented to close this gap, and our primer on explainable AI covers the basics.
Opacity also hides defects that standard accuracy metrics never reveal to the team. A classifier can reach a high test score by exploiting a spurious shortcut, such as a watermark, a hospital identifier, or a background color tied to the label. Practitioners call this shortcut learning, and it only surfaces once someone asks which inputs the model actually relied on. Explanations give teams a cheap way to ask that question before deployment rather than after an incident. They also let domain experts compare the model's reasoning with their own knowledge and flag logic that looks wrong. The dangers of opaque AI show up most painfully when nobody bothered to check.
Trust is the third pressure, and it is partly social rather than technical. People accept a recommendation more readily when it arrives with reasons they can evaluate, and they reject one that appears as an unexplained number. Research on LIME showed this effect directly, because users who saw explanations changed their minds about which model deserved their trust. Commercial demand reflects the same pressure, with analysts projecting double-digit annual growth in spending on explainability tooling. That growth is driven by finance, healthcare, and public sector buyers who face audits, appeals, and regulators. That is why Explainable AI (XAI) Methods: SHAP and LIME Explained has become a standard topic for teams that already own models.
Intrinsic Models, Post Hoc Methods, and Other Explainable AI Families
Explainability techniques fall into a few families, and knowing the families makes the choice between methods much easier. Intrinsically interpretable models, such as linear regression, small classification and regression trees, and rule lists, expose their reasoning directly in their structure. Post hoc methods leave the trained model alone and study its behavior from the outside by probing it with inputs and watching the outputs. SHAP and LIME belong to the post hoc family, and both are model agnostic, so they can wrap almost any prediction function. Model specific methods, such as gradient based saliency for neural networks or TreeSHAP for tree ensembles, trade that flexibility for speed and precision. Each family answers a slightly different question, so teams often combine more than one.
Scope is the second axis that separates these methods from each other. A local explanation describes a single prediction by answering why this applicant was declined, while a global explanation describes the whole model by answering which features matter overall. LIME is local by design, whereas SHAP can produce both because averaging absolute local values across a dataset yields a global importance ranking. A third distinction separates attribution methods, which score input features, from counterfactual methods, which point to the smallest change that would flip the outcome. Feature attribution is by far the most common form in production, which explains why this guide concentrates on it.
How LIME Builds a Local Surrogate Explanation
Building on that vocabulary, LIME stands for Local Interpretable Model-agnostic Explanations, and Marco Ribeiro, Sameer Singh, and Carlos Guestrin introduced it in 2016. The core idea is simple: a complex model may be impossible to describe globally, but near one data point its behavior can often be approximated by a straight line. LIME therefore perturbs the instance, asks the black box to score each perturbed copy, and weights the copies by their closeness to the original. It then fits a sparse linear model to those weighted samples and reports the coefficients as the explanation. The original LIME paper describes this as learning an interpretable model locally around the prediction. Positive coefficients push the prediction toward the class being explained, and negative coefficients push it away.
How the perturbation works depends entirely on the data type being explained. For tabular data, LIME samples new values for each feature from distributions estimated on the training set, so the neighbors it creates are synthetic rows rather than real customers. For text, it randomly removes words from a bag-of-words representation, and for images it switches groups of neighboring pixels called superpixels on and off. The number of perturbed samples and the kernel width that defines closeness are the two settings that most affect how stable a LIME explanation looks. The original paper reports that explaining a 1,000-tree random forest with 5,000 samples took under 3 seconds on a laptop, while one Inception image prediction took about 10 minutes. Cost therefore depends far more on how slow the underlying model is than on LIME itself.
The output is easiest to understand through the classic wolf and husky demonstration. The authors deliberately trained a weak classifier on photos in which every wolf stood on snow, and LIME highlighted the snowy background rather than the animal. That single picture told reviewers the model was cheating, something its accuracy figure could never have revealed. In practice a tabular LIME report is a short ranked list of feature conditions, such as an income range, each with a signed weight. Analysts read the list as a local recipe: these are the facts, within this neighborhood, that moved the score up or down.
Limitations deserve equal attention because they shape how far a LIME result can be trusted. A sparse linear surrogate cannot represent strong non-linearity, so when the model bends sharply near the instance the explanation can mislead. Random sampling means two runs with different seeds can return different top features, which is why serious users fix the seed and repeat the run. Tabular perturbation also treats features as independent, so it can generate unrealistic rows, such as a ten year old with a mortgage. The authors themselves note that local fidelity does not guarantee global fidelity, and they list the choice of sample count and feature limit as open questions.
How SHAP Turns Shapley Values Into Feature Attributions
Turning to SHAP, the method grew out of cooperative game theory, where Lloyd Shapley showed in 1953 how to divide a payout fairly among players who contribute unequally. SHAP, short for SHapley Additive exPlanations, reached machine learning through a 2017 NeurIPS paper by Scott Lundberg and Su-In Lee. Features play the role of players, and the gap between the model's prediction and a baseline expectation is the payout to be shared. A feature's Shapley value is its average marginal contribution across every possible order in which features could be added to the model. Because the number of orderings explodes as features multiply, exact computation is exponential, so practical implementations lean on approximations or on model structure.
What makes SHAP attractive is a short list of guarantees. Lundberg and Lee defined a class of additive feature attribution methods and showed that six earlier techniques, LIME among them, belong to it. They then proved that exactly one member of the class satisfies three desirable properties: local accuracy, missingness, and consistency. Local accuracy means the attributions sum to the model output, and missingness means absent features receive zero credit. Consistency means a feature never loses credit when the model comes to rely on it more. Shapley values are the only attribution scheme in that class that satisfies all three properties, which is the central theoretical argument for SHAP.
The practical output is a base value plus one signed number per feature, and those numbers add up exactly to the prediction. If the average model output is 0.30 and a particular applicant scores 0.62, the features together account for the 0.32 difference, with each feature receiving its share. Because the same additive structure holds for every row, stacking thousands of local explanations produces global summaries, dependence plots, and interaction views. The price is a dependence on the background dataset used to represent missing features, which quietly changes the answer when it is chosen badly. Analysts should therefore record the background sample alongside every SHAP result they share.
SHAP and LIME Compared Across Seven Practical Dimensions
Stepping back from the mechanics, the two methods differ on seven dimensions that matter in day-to-day work: scope, theoretical guarantees, speed, stability, supported data, correlated features, and audit suitability. SHAP covers local and global needs and carries formal guarantees, while LIME stays local and offers none beyond its local fit. LIME is usually faster, especially against exact SHAP on wide tables, although TreeSHAP closes much of that gap for tree models. Stability favors SHAP in most published comparisons, since LIME's random sampling can reorder features between runs. A perspective paper by Salih and colleagues summarizes these trade-offs and stresses that both methods inherit the weaknesses of the model they explain. The comparison table later in Explainable AI (XAI) Methods: SHAP and LIME Explained lays the same dimensions out side by side.
Choosing between them is rarely an either-or decision in mature teams. A common pattern uses LIME for fast, interactive checks during development and SHAP for the reports that reviewers, auditors, and customers will read. When the two disagree on the top features, that disagreement is itself useful information, because it flags a prediction that deserves a closer look. Disagreement should never be resolved by quietly picking the more flattering chart. Reporting both results, with the settings used to generate them, keeps the analysis honest.
Choosing Among Kernel, Tree, and Deep SHAP Explainers
Choosing among the SHAP explainers is mostly a question of model type, because each variant exploits a different structure to avoid the exponential cost. KernelSHAP is the model agnostic option and works by fitting a weighted linear regression, which the original paper describes as linear LIME with a specific kernel. It is flexible but slow, since it must evaluate the model on many coalitions of features for every explained row. TreeSHAP is the specialist for decision trees, random forests, and gradient boosted ensembles such as XGBoost and its uses in tabular prediction. Lundberg and colleagues presented TreeSHAP as the first polynomial time algorithm for computing game theoretic optimal explanations for tree models. That speed is why SHAP became the default tool for gradient boosted trees in credit, insurance, and healthcare.
DeepSHAP targets neural networks by combining SHAP values of small network components through a backpropagation rule borrowed from DeepLIFT. It is much faster than KernelSHAP on deep models, although its results depend on the chosen reference inputs and on how the network is built. Teams weighing machine learning versus deep learning for a tabular problem should note that explanation tooling is easier and cheaper on trees. LinearSHAP covers linear models in closed form, and the library also offers sampling based and partition based explainers for text and images. When a tree ensemble fits the problem, TreeSHAP delivers exact attributions in seconds, which removes most of the practical argument for choosing LIME.
Background data and runtime budgets deserve a final check before any explainer is deployed. KernelSHAP cost grows with the number of background rows and sampled coalitions, so teams usually summarize the background set with a few dozen cluster centers. Interventional TreeSHAP also depends on a background sample, whereas the path dependent variant uses the tree's own cover statistics and needs none. Each choice changes the meaning of the attribution, so it belongs in the documentation of any explanation that supports a decision. A simple rule is to prefer the cheapest explainer that matches the model, and to spend any saved compute on repeated runs and stability checks.
Putting SHAP and LIME to Work in a Python Pipeline
Moving on to implementation, a minimal pipeline needs only a trained model, a held-out test set, and the two open source packages named shap and lime. The first code block below installs the packages, loads a public breast cancer dataset from scikit-learn, and trains a gradient boosted classifier. Keeping the model simple makes it easier to confirm that every explanation reflects behavior you can reason about. Fix the random seeds everywhere, because reproducibility is the first requirement of any explanation that someone else will review. Split the data before you explain anything, and explain only rows the model never saw during training. Everything in Explainable AI (XAI) Methods: SHAP and LIME Explained is easier to verify when the pipeline is reproducible from a clean environment.
pip install shap lime scikit-learn

import shap
from lime.lime_tabular import LimeTabularExplainer
from sklearn.datasets import load_breast_cancer
from sklearn.ensemble import GradientBoostingClassifier
from sklearn.model_selection import train_test_split

data = load_breast_cancer(as_frame=True)
X_train, X_test, y_train, y_test = train_test_split(
    data.data, data.target, test_size=0.2, random_state=0
)
model = GradientBoostingClassifier(random_state=0).fit(X_train, y_train)
print("test accuracy:", round(model.score(X_test, y_test), 3))
The SHAP step comes next, and for a tree ensemble it is a two-line affair thanks to the TreeExplainer. The SHAP documentation describes the library as a game theoretic approach to explaining the output of any machine learning model. Calling the explainer on the test set returns an explanation object holding one value per feature per row, expressed in log-odds units for this classifier. A waterfall plot shows a single prediction as a staircase from the base value to the final score, while a beeswarm plot stacks every row to show global behavior. Always inspect at least one waterfall and one beeswarm, because the first shows the local story and the second shows whether that story is typical.
explainer = shap.TreeExplainer(model)
shap_values = explainer(X_test)

shap.plots.waterfall(shap_values[0])   # one prediction
shap.plots.beeswarm(shap_values)       # global view
LIME needs a different input because it samples new rows around the instance, so it must be shown the training data to learn each feature's range. The lime package on GitHub states that it works with any classifier that takes a numpy array and returns a probability for each class. You pass the model's probability function, choose how many features to report, and choose how many perturbed samples to draw. Raising the sample count smooths the result at the cost of more model calls, so a slow model makes this the main budget decision. Setting the random state in the explainer makes the output repeatable, which matters when the result goes into a report.
lime_explainer = LimeTabularExplainer(
    X_train.values,
    feature_names=list(X_train.columns),
    class_names=["malignant", "benign"],
    mode="classification",
    random_state=0,
)
exp = lime_explainer.explain_instance(
    X_test.values[0], model.predict_proba, num_features=8, num_samples=5000
)
print(exp.as_list())
The final step is the one most teams skip, which is comparing the two outputs on the same row. If SHAP and LIME agree on the leading features and their direction, confidence in the explanation rises. If they disagree, rerun LIME with several seeds and a larger sample count, then check whether the SHAP ranking holds across models trained on bootstrap samples. Log the model version, the background data, the seeds, and the package versions next to every stored explanation. Those few lines of metadata turn a screenshot into evidence that an auditor can reproduce months later.
Reading SHAP Plots and LIME Charts Without Fooling Yourself
Beyond the code, the harder skill is reading the pictures correctly, because a clean chart invites more confidence than it deserves. In a SHAP beeswarm plot each dot is one row, its horizontal position is the feature's contribution, and its color encodes the feature value. A cluster of red dots on the right means high values of the feature push predictions up, while mixed colors on both sides signal an interaction or a non-monotonic effect. The ranking of features carries the message, and the raw magnitude depends on the output scale, so a value in log-odds cannot be read as a probability change. LIME bar charts follow the same logic locally, with one color for features that support the predicted class and another for features that oppose it.
Context decides whether any of this analysis is meaningful for the decision at hand. An explanation of an overfit model faithfully describes the overfit behavior, which is why overfitting versus underfitting in practice belongs on the checklist before anyone interprets a plot. Correlated features split credit unpredictably, so two near duplicate columns can each look unimportant even when the pair drives the model. Always state the units, the background data, and the model version beneath every chart, and avoid causal language such as because or leads to. These plots describe what the model does with its inputs, and they say nothing about what would happen in the real world if an input changed.
The Risks and Limits of Explainable AI Methods
Despite the popularity of these methods, they have well documented weaknesses, and the first is that they explain the model rather than reality. A biased or overfit model produces a faithful explanation of its own bias, so a clean looking SHAP chart is no evidence that the model is fair or correct. The second weakness is the treatment of correlated inputs, since standard implementations break the dependence between features when they simulate missing values. That practice can create unrealistic data points, such as a patient with a very high weight and a very low body mass index. Perturbation based explanations are only as trustworthy as the synthetic data they are computed on, and nobody can fully verify that data.
Computation cost and sampling variance cause the third and fourth problems on the list. Exact Shapley values are exponential in the number of features, so wide tables force approximations whose error is rarely reported alongside the result. LIME adds sampling noise, so identical inputs can yield different feature orderings across runs unless the seed and sample size are controlled. A perspective on SHAP and LIME by Salih and colleagues adds that both methods give different top features for different models trained on the same data. Practitioners therefore need to treat an explanation as an estimate with uncertainty, not as a measurement.
The most unsettling weakness of these methods is adversarial rather than statistical. Researchers have shown that a model can be wrapped to behave in a biased way on real inputs. The wrapper produces innocent looking explanations because the explainers query it on off-distribution samples. Teams that rely on explanations alone for fairness evidence are exposed to this trick. The literature on adversarial attacks in machine learning shows how routine such attacks have become. The case studies later in this guide quantify the problem with published numbers. Any audit plan should pair explanation tools with outcome testing on real data.
The Disagreement Problem and Fragile Explanations
Looking closer at reliability, researchers have named the clash between explanation methods the disagreement problem. A study of practitioners and explanation methods evaluated four real-world datasets, six post hoc methods, and six predictive models, and it found that state-of-the-art methods often disagree. Disagreement can mean different top features, different signs, or different rankings, and each kind causes a different failure in practice. When a loan officer and a regulator receive different reasons for the same decision, the organization has a documentation problem as well as a technical one. Understanding the kinds of disagreement is the first step toward managing it.
The more worrying finding concerns how practitioners resolve conflicts between methods in daily work. The same study reports that data scientists often rely on ad hoc heuristics, such as trusting the method they know best or the chart that looks most plausible. That habit can let a misleading explanation drive a consequential decision, because nothing in the workflow checks it against a principled standard. A disagreement between methods is a diagnostic signal about the model or the data, and it should trigger investigation instead of a quiet choice of favorite. Common culprits include correlated features, strong interactions, unstable models, and background data that do not match production inputs.
Fragility has several practical sources that are worth listing separately here. Small changes to the training sample or the random seed can reorder features, particularly in the middle of the ranking where importance values are close. Hyperparameter choices change which features the model leans on, so the same dataset can produce different stories under different configurations. Explanations also drift over time as data distributions move, which means a chart that was accurate at launch can mislead a year later. Stability should therefore be measured and monitored continuously instead of simply being assumed.
A workable defense combines a few habits that cost little. Compare at least two explanation methods and at least two model families on every high-stakes use case, and record where they diverge. Report feature importance with intervals computed across seeds and bootstrap samples instead of a single point value. Document the resolution rule in advance, for example by requiring agreement on the top three features before an explanation is shown to a customer. Teams building fairness programs can pair these habits with AI bias audits for fairness that test outcomes directly.
Ethics, Fairness, and the Danger of Explanation Washing
Beyond technical reliability lies an ethical risk that deserves its own name, which is explanation washing. The term describes a polished explanation used to make a questionable model look trustworthy, whether or not anyone intended deception. A neat bar chart can reassure a regulator, a customer, or an executive without proving anything about discrimination. Fairness is a property of outcomes across groups, and no feature attribution chart can establish it by itself. Teams that ignore this distinction risk shipping models whose explanations are tidy while their error rates differ sharply between groups.
Responsible practice treats explanations as one input into governance rather than a substitute for it. That means testing outcomes by subgroup, documenting the intended use, and defining who may override a model and when. It also means telling affected people honestly what an explanation can and cannot show. That duty connects directly to the dangers of AI bias and discrimination discussed elsewhere on this site. Organizations that formalize these duties through responsible AI governance frameworks tend to catch problems earlier. Explanations then become evidence inside a larger review process, which is the role they are best suited to play.
Regulation and the Legal Case for Explanations
Turning to the law, explanations are increasingly an obligation rather than a courtesy. In the United States, CFPB Circular 2022-03 states that creditors must give specific and accurate reasons for adverse actions regardless of the technology used. The circular adds that a creditor's lack of understanding of its own methods is not a defense, and it notes that post hoc explanations approximate models and must be validated. That language matters for SHAP and LIME because both are approximations, so a lender cannot simply paste their outputs into a notice. The lender has to show that the approximation is accurate for the model in use.
European rules point in the same direction as the American guidance on explanations. Article 86 of the EU AI Act gives people affected by certain high-risk system decisions the right to request clear and meaningful explanations of the system's role. The right applies where the decision has legal or similarly significant effects that the person sees as harmful to health, safety, or fundamental rights. Providers and deployers therefore need explanation capabilities designed into the system and not bolted on after a complaint arrives. Compliance teams should treat SHAP and LIME outputs as draft evidence that must be validated, documented, and translated into plain language before it reaches a customer.
Standards bodies add a useful shared vocabulary for that work, and the next section returns to it. Regulators also expect consistency, so the same facts should produce the same reasons across channels and over time. The practical consequences are straightforward: version the model and the explainer together, test explanations against held-out cases, and keep an audit trail linking each notice to its inputs. Governance leaders following AI governance trends and regulations will recognize explanation capability as a standing requirement rather than a one-off project. Legal review should happen early, since rules differ by sector and jurisdiction. Explainable AI (XAI) Methods: SHAP and LIME Explained should therefore be treated as an input to legal review, not a substitute for it.
Measuring Explanation Quality Before You Trust It
Stepping back to measurement, the central question is whether an explanation is faithful to what the model actually does. The NIST report on four principles of explainable AI, published in September 2021, names explanation, meaningfulness, explanation accuracy, and knowledge limits as the core requirements. Explanation accuracy means the explanation correctly reflects how the system produced its output, which is exactly what fidelity tests try to measure. Meaningfulness means the intended audience can understand it, which no automated metric can fully confirm. An explanation that is accurate but unintelligible fails its audience just as surely as one that is clear but wrong.
Several practical tests make these principles operational for engineering teams that ship models. Deletion and insertion tests remove or restore the features an explanation calls important and check whether the prediction changes as expected. Stability tests rerun the explainer under new seeds and bootstrap samples and report how often the top features stay the same. Sanity checks randomize the model or the labels and confirm that the explanation changes accordingly. Human studies, like the user experiments in the original LIME paper, test whether real people make better decisions with the explanation in front of them. Applying these tests is what separates Explainable AI (XAI) Methods: SHAP and LIME Explained as a discipline from a collection of attractive charts.
Alternatives and Complements Beyond SHAP and LIME
Beyond SHAP and LIME, several other methods answer different questions and deserve a place in the toolbox. Permutation importance and partial dependence plots give global views that are easy to explain to non-specialists. Counterfactual explanations tell an applicant the smallest change that would have flipped the decision, which is often the most actionable form of reasoning. Anchors report if-then rules that hold with high precision around an instance, and integrated gradients attribute predictions of neural networks along a path from a baseline. Teams can find the simpler models in the toolbox through resources such as top machine learning algorithms explained.
Some researchers argue the whole post hoc approach is a mistake for high-stakes work. Cynthia Rudin's argument in Nature Machine Intelligence is that developers should stop explaining black boxes for high-stakes decisions and build inherently interpretable models instead. She also questions the assumed trade-off between accuracy and interpretability, and she notes that saliency maps show only where a network looks. The strongest position is pragmatic: use an interpretable model whenever it performs well enough, and reserve post hoc tools for cases where it does not. The 2018 FICO explainable machine learning challenge reflected both camps, since IBM Research won with an explainable model while a Duke team earned recognition for a fully transparent one.
Choosing among these options starts with the decision at stake. If an affected person will see the reasons, simple rule-like or counterfactual outputs usually communicate best. If a data scientist is debugging, rich attribution plots from SHAP are more useful. If a regulator will review the model, interpretable designs plus validated explanations create the strongest record. Mixing approaches is normal, and the goal is a documented rationale for each choice.
The Future of Explainable AI Practice
Looking ahead, regulation and scale will keep pushing explainability from research into routine engineering. Expect explanation tooling to move into model monitoring platforms, where attributions are tracked alongside accuracy and drift so that behavior changes are caught early. Healthcare will be a leading adopter because clinicians must understand a model before acting on it, as the discussion of AI in healthcare applications illustrates. The field is moving from producing explanations to proving that they are accurate, stable, and understood by the people who rely on them. Standard benchmarks for faithfulness and stability should make that proof easier over time.
New model families raise fresh questions that current explanation tools only partly answer. Large language models generate fluent natural language rationales, yet those rationales may not reflect the computation that actually produced the answer, so they cannot replace attribution analysis. Concept based methods, which describe behavior in human terms such as stripes or tumor shape, are gaining ground for vision models. Medical settings will also force progress on consent, accountability, and clinician override, topics covered in ethical concerns in healthcare AI. Teams that build explanation skills now will adapt more easily as the tools change. Anyone studying Explainable AI (XAI) Methods: SHAP and LIME Explained today is therefore learning a skill with a long shelf life.
Chart From AIplusInfo
Hiding bias from LIME and SHAP
Share of test points where the scaffolded classifier removed the sensitive feature from first place (percent).
COMPAS
Communities and Crime
German Credit
Source: Slack and colleagues, Fooling LIME and SHAP, arXiv 1911.02508. Bias hidden is the share of test points where the sensitive feature was no longer ranked first after the single-feature attack. Scaffold fidelity is the agreement between the scaffolded classifier and the original biased classifier on held-out data.
Key Insights
- BCC Research projects the explainable AI market will climb from USD 7.8 billion in 2024 to USD 22.6 billion by 2030, making explanation skills a core engineering requirement.
- The original LIME experiments recovered truly important features with recall above 90 percent on simple models, showing that local surrogates can be faithful.
- Lundberg and Lee showed that six earlier attribution methods fit one additive class, and only the Shapley-value solution satisfies local accuracy, missingness, and consistency together.
- Scaffolded classifiers hid the sensitive feature from LIME on 100 percent of COMPAS test points, according to Slack and colleagues, so explanations alone cannot prove fairness.
- Across four datasets, six methods, and six models, explanation methods often disagreed, so one SHAP or LIME chart should never be the only evidence behind a decision.
- In a Nature Biomedical Engineering study of more than 50,000 surgeries, anaesthesiologists anticipated about 15 percent of hypoxaemia events unaided but about 30 percent with explained risk predictions.
- Since May 2022 the CFPB has told lenders that complex algorithms never excuse missing reasons, so a poorly understood model carries real legal exposure for every lender.
Taken together, these figures describe a field that is growing fast while its core tools remain imperfect. SHAP offers formal guarantees and global views, LIME offers speed and simplicity, and both inherit the quirks of the models they explain. Published experiments show that explanations improve human judgment, yet other experiments show they can disagree, drift, or be gamed. Regulators have responded by demanding specific and accurate reasons, which turns validation from a research nicety into a compliance duty. The sensible response is to combine methods, test stability, and document every setting behind a published explanation. Teams that do so gain a defensible record, while teams that skip it risk trusting a chart that merely looks convincing.
| Dimension | SHAP | LIME |
|---|---|---|
| Scope | Local explanations plus global summaries built by aggregating many rows | Local explanations only, one prediction at a time |
| Theoretical guarantees | Local accuracy, missingness, and consistency for Shapley values | Local fidelity of a sparse linear surrogate, with no global guarantee |
| Speed | Fast for trees through TreeSHAP, slow for model agnostic KernelSHAP | Moderate and tied to sample count and model latency |
| Stability | Generally steadier, though background data and sampling still matter | Can reorder features between runs because of random sampling |
| Supported data | Tabular, text, and images through specialized explainers | Tabular, text, and images through perturbation of inputs |
| Correlated features | Marginal baselines can create unrealistic data points | Independent perturbation can create unrealistic data points |
| Audit suitability | Additive outputs that sum to the prediction, easy to document | Quick checks, but weights need repeated runs before they are filed as evidence |
Explainable AI in Practice: Three Real Deployments
LIME's Wolf and Husky Experiment
In practice the clearest demonstration of explanation value came from the LIME authors, who built a flawed classifier on 20 hand-picked images where every wolf stood on snow. They trained it to separate wolves from huskies, then showed graduate students with machine learning coursework its predictions with and without LIME explanations. Before seeing explanations, 10 of 27 students said they trusted the model, but afterward only 3 of 27 did, a drop from about 37 percent to about 11 percent. The share who named snow as a likely cause rose from 12 of 27 to 25 of 27, which turned a hidden shortcut into an obvious one. The wolf and husky experiment in the LIME paper is small and the authors admit its limits, because the sample was modest and the model was intentionally broken. It also shows only that explanations help people spot an error someone planted, and a subtle real-world flaw may still slip past a reader.
Prescience and Hypoxaemia Prediction During Surgery
Moving to medicine, University of Washington researchers built Prescience, a system that estimates the risk of low blood oxygen during anaesthesia and displays the factors behind each estimate. The team trained it on minute-by-minute electronic records from more than 50,000 surgeries, with thousands of candidate features for each prediction. Each alert arrives with its contributing factors, so an anaesthesiologist can judge whether the reasoning matches the patient on the table. According to the Nature Biomedical Engineering paper, clinicians anticipated about 15 percent of hypoxaemia events unaided but about 30 percent with the system's help. The authors report that the explanations were broadly consistent with the literature and with prior clinical knowledge. The data came from a single health system and patient-level records are not public, so external validation is still limited.
Airline Passenger Satisfaction and Explanation Stability
Shifting to a stability test, Salih and colleagues trained four models on 500 airline passengers, half of them satisfied, using 22 features and a 20 percent test split. The light gradient boosting machine reached 0.91 accuracy, ahead of a support vector classifier at 0.86, logistic regression at 0.85, and a decision tree at 0.84. They then compared SHAP rankings and found that two models ranked the Class feature first while the other two ranked different features first. A stability score called the Normalized Movement Rate was lowest, and therefore best, for the gradient boosting model at 0.231, against 0.445 for the decision tree. A collinearity correction called the Modified Index Position moved Ease of Online booking from 15th to 5th place for the gradient boosting model. Readers can check each ranking in the airline analysis by Salih and colleagues itself. The authors caution that these are single runs on a small sample with default parameters, so tuning could still change the picture.
Recommended by AIplusInfo
Books to go deeper on SHAP and LIME
Hands-on titles that extend the techniques and cautions described above.
As an Amazon Associate, AIplusInfo earns from qualifying purchases.

Book
Interpretable Machine Learning with Python, Second Edition
Walks through SHAP, feature importance, and bias mitigation with worked Python examples on datasets such as COMPAS.
Buy on Amazon
Book
Applied Machine Learning Explainability Techniques
A practitioner guide to applying explainability methods such as LIME and SHAP to make models more trustworthy in production.
Buy on AmazonLessons From Three Explainable AI Case Studies
Case Study: Scaffolded Classifiers That Fooled LIME and SHAP
Beyond the lab demonstrations, a team of machine learning researchers posed a sharp problem: could a discriminatory model hide its bias from the very tools auditors rely on? Slack and colleagues examined LIME and SHAP in a 2019 preprint using three real tabular datasets, namely COMPAS recidivism scores, Communities and Crime, and German Credit. Their challenge was that both explainers query the model with perturbed samples that look different from real data, which creates an opening for an attacker. The team built a scaffold that sends real-looking inputs to a biased classifier and sends the explainers' off-distribution samples to an innocuous classifier. The resulting hybrid kept its biased behavior on real data while its explanations looked clean.
The attack nearly always worked against LIME, which stopped ranking the sensitive feature first on 100 percent of COMPAS points and 100 percent of Communities and Crime points. On German Credit the same attack hid the sensitive feature on 91 percent of points. SHAP resisted somewhat better, with the sensitive feature dropped from first place on 84 percent of COMPAS points and 85 percent of German Credit points. The scaffold also agreed with the original biased model less often under SHAP, between 75 and 91 percent on held-out data, which shows the SHAP attack was less faithful. The authors acknowledge limits, because their biased classifier is perfectly discriminatory, only three tabular datasets were tested, and gradient-based explainers were not studied. These caveats make the work a stress test and not proof that real deployments are being gamed. Even so, it is a strong reason to pair explanations with outcome testing, and the full paper on arXiv reports every number in detail.
Case Study: UK Biobank Heart Attack Models Disagree
Turning to medicine, a recent perspective paper tested what happens when different models explain the same patients. The problem was practical, because clinicians need to know whether the factors an explanation highlights belong to the disease or to the model that happened to be chosen. The authors analyzed 1,500 UK Biobank participants labeled as having had a myocardial infarction or not, held out 20 percent for testing, and used 10 features. They built four models, a decision tree, logistic regression, a light gradient boosting machine, and a support vector classifier, and explained each with SHAP and LIME. All four models agreed on the top three features by SHAP and reached similar accuracy, yet the remaining seven features moved around.
Body mass index ranked last for the decision tree and logistic regression, third for the gradient boosting model, and seventh for the support vector classifier. LIME told an equally unsettling story for one representative patient, since alcohol consumption pushed the prediction toward heart attack in two models and away from it in two others. The authors recommend presenting SHAP outputs with plain-language statements of assumptions and comparing several models before choosing one. They also stress limits, because single runs, default parameters, and small samples mean the rankings could change with tuning. For anyone deploying clinical models, the lesson is that an explanation belongs to a model and not to a disease. The UK Biobank analysis in the perspective paper is worth reading in full.
Case Study: Lenders Facing the CFPB Adverse Action Rule
Rounding out the set, US lenders faced a concrete compliance problem when machine learning models began replacing traditional scorecards. Federal law requires a creditor to tell an applicant the specific reasons for a denial, and many teams worried that complex models made that duty impossible to meet. On May 26, 2022, the Consumer Financial Protection Bureau issued Circular 2022-03, saying creditors may not use complex algorithms that prevent specific and accurate reasons. The circular adds that a creditor's lack of understanding of its own methods is not a defense. A natural solution is to pair complex models with post hoc attribution tools such as SHAP so that candidate reasons can be generated for each denial. That solution still leaves lenders responsible for showing the reasons are accurate.
Market analysts see the commercial stakes as large, and BCC Research projects the explainable AI market to grow from USD 7.8 billion in 2024 to USD 22.6 billion by 2030. The circular also sets a practical limit on trust in vendor tools, because post hoc explanations approximate models and creditors must be able to validate those approximations. That requirement is hard to meet for deep ensembles, so some lenders move toward interpretable models whose reasons are exact by construction. Critics of post hoc tools, led by Cynthia Rudin, argue that a model needing after-the-fact explanation should not make high-stakes credit decisions at all. The controversy is unresolved, and the circular does not pick a side between the two approaches. Teams should review the full circular with counsel and test reason codes against held-out denials before relying on them.
Frequently Asked Questions on Explainable AI (XAI) Methods
Explainable AI is a set of techniques that show why a machine learning model produced a particular output. Some models are explainable by design, such as short decision trees or linear models. Others are black boxes that need post hoc tools like SHAP and LIME to reveal which inputs mattered. The goal is to give people reasons they can check, challenge, and act on.
SHAP stands for SHapley Additive exPlanations, and it builds on Shapley values from cooperative game theory. It treats each feature as a player and measures its average marginal contribution to the prediction across many feature combinations. The resulting values add up to the difference between the prediction and a baseline. Because of that additive structure, the same numbers can be summarized into global importance charts.
LIME stands for Local Interpretable Model-agnostic Explanations, a method for explaining single predictions. It perturbs a single instance, scores the perturbed copies with the black box model, and weights them by closeness to the original. A sparse linear model fitted to those weighted samples becomes the explanation. Its coefficients show which features pushed the prediction up or down near that one point.
Neither method wins in every situation, because each one trades something away. SHAP offers stronger theoretical guarantees, global summaries, and usually steadier results, but it can be slow for model agnostic use. LIME is quick and simple for single predictions, yet its random sampling can change the ranking between runs. Many teams use LIME for exploration and SHAP for reports that others will review.
Both are model agnostic in principle, since they only need a function that maps inputs to predictions. SHAP also offers specialized explainers for trees, linear models, and deep networks that run much faster. Practical limits appear with very slow models, very wide inputs, and data types the library does not support. Always test the explainer on a few known cases before trusting it at scale.
The methods define importance differently, so their numbers are not directly comparable. LIME fits a local linear approximation using random perturbations, while SHAP averages contributions over feature combinations using a background dataset. Correlated features, sampling noise, and different baselines can all change the ranking. Treat a disagreement as a signal to investigate the model and the data.
The tabular implementation draws 5,000 perturbed samples by default, which is a reasonable starting point. More samples usually reduce run-to-run variation but cost more model calls. Check stability by repeating the explanation with several random seeds and comparing the top features. If the ranking keeps changing, increase the sample count or review whether the local linear surrogate fits the model.
Not exactly, because SHAP values are local contributions for individual predictions. A global importance chart is usually built by averaging the absolute SHAP values of each feature across many rows. That summary shows how much a feature moves predictions on average, not whether it causes outcomes. Classic permutation importance answers a different question about how much accuracy drops when a feature is scrambled.
No, because fairness concerns outcomes across groups and explanations describe how a model uses its inputs. A model can look reasonable in a feature chart and still produce unequal error rates between groups. Research on scaffolded classifiers has also shown that explanations can be manipulated to hide bias. Pair explanations with subgroup performance testing and a documented governance process.
The act does not name any specific tool or algorithm. Article 86 gives affected people a right to request clear and meaningful explanations of an AI system's role in certain high-risk decisions. How a provider meets that duty is a design and legal question, and SHAP or LIME outputs may be one input. Any explanation used for compliance should be validated, documented, and written in plain language.
Start with the single decision and name the two or three features that mattered most. Describe each bar as a push toward or away from the outcome, and avoid causal language such as because. State the baseline in plain words, for example the average applicant, so the starting point is clear. Finish by saying what the chart cannot tell you, such as whether the model is fair.
They can be applied to language models by treating tokens or phrases as the features, but the cost is high and the results are noisy. Token level attributions show which words influenced an output without explaining the reasoning inside the network. Natural language rationales written by the model itself may not reflect its real computation. Treat all of these outputs as hints that need verification.
Inherently interpretable models, such as sparse linear models, rule lists, and small trees, give exact reasons by construction. Counterfactual explanations describe the smallest change that would flip a decision, which applicants often find more useful. Global tools such as permutation importance and partial dependence plots add complementary views. For high-stakes decisions, an interpretable model that performs adequately is often the safest choice.